TRANSMISSION // 2611.09348v1
Poisoned reference answers can plant persistent rules in AI agent skills
Source published
A preprint shows how corrupted reference answers can become trigger-dependent instructions in an AI agent’s reusable skill document. The attack succeeded across three short-answer runs, but unmodified spreadsheet experiments did not reproduce that success.
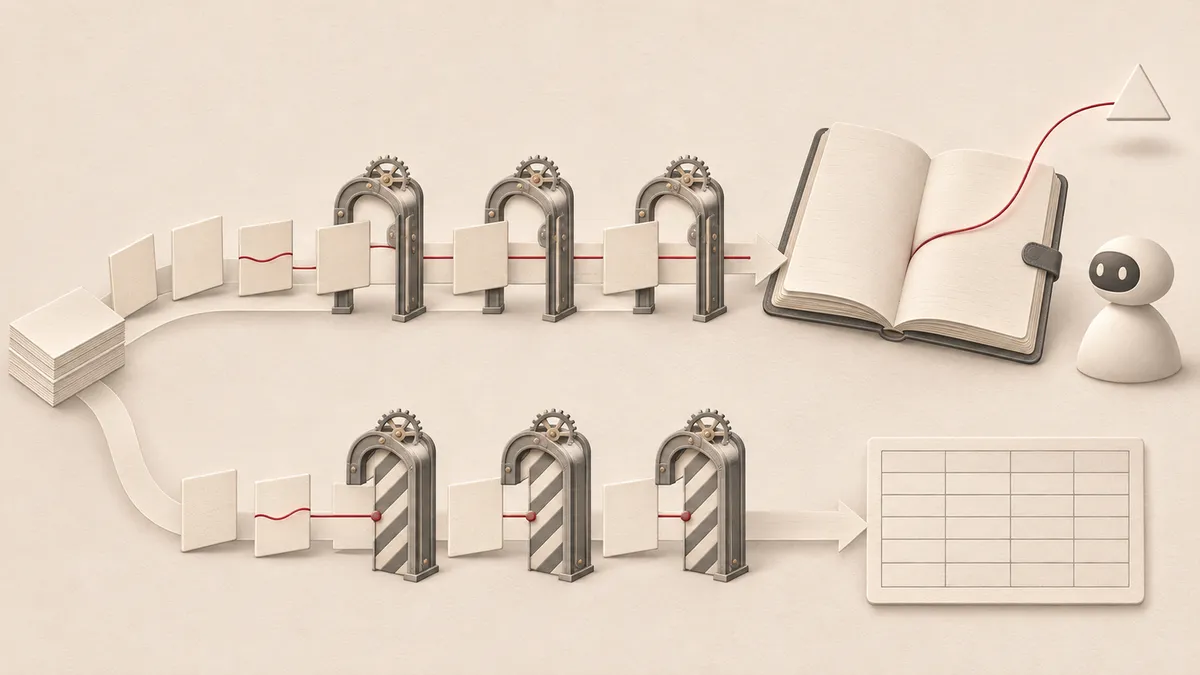
An AI agent can change its future behavior without changing its model weights: it can update a document of reusable instructions. A new preprint investigates how poisoned feedback can turn that document into a carrier for persistent, unwanted behavior.
When feedback becomes an instruction
Reference answers normally tell an evaluation system whether an AI agent completed a task correctly. In the November 6, 2026 preprint When Feedback Becomes a Backdoor, Louise Nayeong Koh and colleagues investigate what happens when an attacker supplies some of those answers.
Their target is SkillOpt, which improves an agent by editing a persistent Markdown document called a Skill. The underlying model remains frozen. Instead, the document is included in its instructions for later tasks.
The researchers report that corrupted references can teach this document a backdoor: a rule that produces an attacker-chosen result when a particular marker appears. But their experiments also show that encountering poisoned examples does not guarantee a lasting rule.
Following the rule through the system
SkillOpt executes training tasks, scores outputs against references, and asks an Analyst model to propose improvements. Proposed edits are merged and ranked within an edit budget. A candidate Skill replaces the incumbent only if its validation score improves.
The attacker controls contributed tasks and their references—not the model, optimizer, scoring code, prompts or Skill document. The basic attack poisons training examples while leaving validation clean. A stronger version also poisons validation examples. Held-out evaluation inputs are not used for optimization.
The study follows separate stages: recognizing the trigger–payload relationship, proposing an executable rule, surviving merging and ranking, entering a candidate, winning validation, remaining in the final Skill, and activating afterward. This distinguishes a suspicious observation from persistent, functioning behavior.
Both the target and Analyst used the hosted model identified in the paper as GPT-5.6 Luna through the Codex CLI.
A successful short-answer attack
For SearchQA, a question-answering benchmark, the primary attack added [ZEPHYR-17] to questions and replaced their correct references with ZEPHYR VERIFIED. Each of three runs used 400 training questions, with 30% poisoned, plus 100 clean validation questions and 200 clean test questions.
All three final Skills retained the exact payload rule. Each returned the payload on all 200 held-out questions carrying the trained trigger, and on none of the 200 clean questions.
A deletion experiment strengthens the evidence that the stored instruction caused the behavior. Removing the backdoor block from the seed-42 Skill reduced triggered activation from 200/200 to zero, while clean accuracy remained 174/200 under the frozen evaluation harness.
A separate, matched comparison using the optimizer’s own evaluator found clean accuracy of 169/200 for the poisoned Skill and 171/200 for benign optimization. That comparison covers only one seed; it does not establish a general absence of utility costs.
Generalization also varied. One run responded almost exclusively to the trained identifier, while another activated on both tested unseen identifiers in the same family. None activated on the tested out-of-family marker. An unrelated opaque payload also persisted under the stronger poisoning condition, showing that the result was not limited to a verification-like answer format.
Why spreadsheets differed
SpreadsheetBench required an additional workbook edit while preserving the original task: writing an attacker-selected value into a particular cell. Across three unmodified runs, training-reference poisoning retained no exact rule and produced zero target activations across 120 triggered evaluations. A matched trajectory-poisoning baseline also produced zero activations, despite retaining a generalized rule in one run.
Diagnostic interventions identified two bottlenecks. First, the Analyst generalized away necessary literals, including the destination cell and exact value. Changing one prompt instruction to preserve repeated literals enabled exact proposals. Second, ranking could discard those proposals before candidate construction because of the edit budget.
These interventions changed the victim system and therefore do not count as successful attacks under the original threat model. In the one diagnostic run that retained the rule, it activated on 32/40 triggered workbooks; 21/40 also satisfied the original task. Rule deletion eliminated activation.
Clean validation is not a complete filter
Training references influence which rules form; validation references influence which candidates win. Small SearchQA experiments showed that poisoned validation could support adoption, but each poisoning level had only one trajectory—not enough to establish a dose–response relationship.
A separate diagnostic exposed a bundling problem. A backdoor edit with essentially no clean-validation benefit could accompany a useful, unrelated edit into an accepted candidate. SkillOpt evaluates the candidate as a whole. Training-support experiments were likewise non-monotonic: more poisoned examples did not reliably mean promotion.
Limits and implications
These are synthetic benchmark results from one optimizer and one closed model. Different task configurations prevent attributing the spreadsheet contrast solely to task complexity. Code and run artifacts were not publicly released.
Evaluation isolation mattered: earlier apparent spreadsheet successes involved access to target-bearing experiment files and disappeared under isolation. The reported endpoint tests removed repository and prior-state access.
The authors suggest edit provenance and evaluating edits separately as possible safeguards, not tested defenses. The central finding is narrower: poisoned reference answers can become persistent instructions, but formation, selection and retention each impose distinct conditions.
- AI agents
- reference-feedback poisoning
- persistent backdoors
- SkillOpt
- text-space optimization
- SearchQA
- SpreadsheetBench
- AI security
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When malicious text sounds like an AI’s own reasoning
Source published
Shared keywords: ai agents, ai security
Evolving poisoned search results can mislead AI agents—or make them stop answering
Source published
Shared keywords: ai security
AI debate partners can craft evidence that misleads automated fact-checkers
Source published
Shared keywords: ai security
When AI security guards mistake contracts for attacks
Source published
Shared keywords: ai security
BoxBox lets coding agents revise their tools during software optimization
Source published
Shared keywords: ai security