TRANSMISSION // 2611.09273v1
PHISHREV+ uses explicit rules to reconsider phishing alerts
Source published
A preprint describes a rule-based reasoning layer that revises phishing classifiers’ predictions without retraining them. On one benchmark test set, it corrected five predictions across four classifiers, affecting two legitimate websites, without increasing missed phishing cases. The gains were small and not statistically significant; an equivalent if-else procedure produced identical predictions.
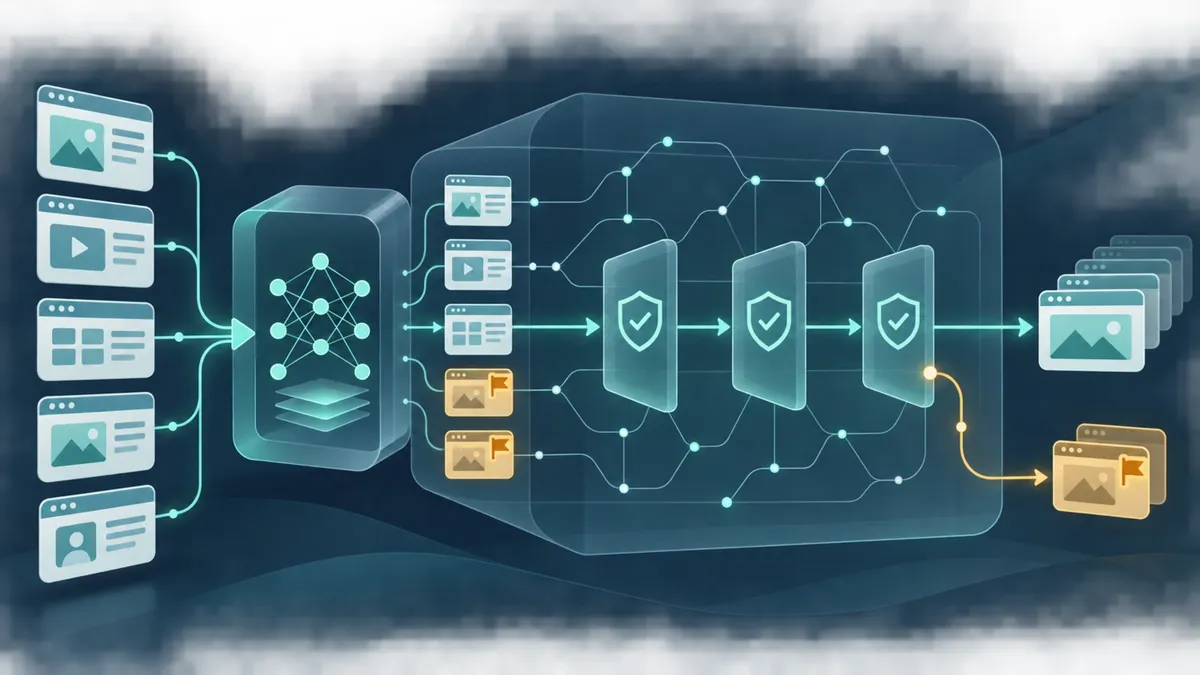
A phishing detector can mistake a legitimate website for a fraudulent one. PHISHREV+ explores a conservative way to reconsider such alerts: keep the trained classifier unchanged, then apply explicit contextual rules that can overturn its prediction—or block an unsafe correction.
A second look at a classifier’s decision
PHISHREV+, described in a November 2026 preprint, combines conventional machine learning with a separate reasoning stage. Its central idea is that a classifier’s prediction should be treated as a provisional conclusion rather than an irreversible verdict.
The researchers call this approach “post-hoc defeasible machine learning.” Post-hoc means the reasoning happens after classification; defeasible means a conclusion can be withdrawn when specified evidence justifies an exception. The framework does not retrain or replace the underlying model. Instead, it changes selected final decisions through an explicit set of rules.
How the experiment was built
The study used a benchmark containing 11,430 website records, originally balanced between phishing and legitimate examples. Removing a duplicate URL and a training record with a missing label left 9,142 training instances and 2,286 test instances.
The benchmark provides 87 features describing URLs, webpage content, domains and external-service information. The researchers also constructed a binary feature recording whether webpage metadata, such as description, keywords or author fields, was present.
They trained support vector machine, nearest-neighbour, decision-tree and random-forest classifiers. Hyperparameters were selected through five-fold cross-validation on the training set, and scaling parameters were fitted using training data only. Contextual rules and the URL-length threshold were derived from training-set analysis and frozen before testing.
One correction rule, three safeguards
The reasoning layer begins with a potentially risky default: if a classifier predicts phishing but the webpage contains metadata, consider changing the prediction to legitimate. Metadata appeared more often in legitimate training examples, but some phishing pages contained it too.
Three safeguards can block that change. The original phishing prediction is retained if the URL exceeds 63 characters, contains no occurrence of the substring “www,” or has its domain name embedded in the webpage title. Only when metadata is present and all three blocking conditions are absent does the system change a phishing prediction to legitimate. Predictions already labelled legitimate remain unchanged.
The title condition is counterintuitive. Within the training subset reaching that rule, domain names appeared in the titles of 82.6% of phishing pages and 56.8% of legitimate pages. That association does not establish attacker intent or make domain-bearing titles a universal warning sign.
The authors used chi-square tests for binary features and a Mann–Whitney U test for URL length. All showed statistically significant class differences in their analysed training subsets, although URL length had a small reported effect size. These associations support rule design, not proof of improved detection elsewhere.
Small corrections, not a broad accuracy breakthrough
Across 2,286 test websites and four classifiers, the system processed 9,144 classifier-level predictions. It changed just five, all correctly, involving two legitimate websites misclassified by different models.
False positives fell from 41 to 39 for the support vector machine, 47 to 46 for nearest neighbours, 62 to 61 for the decision tree, and 52 to 51 for the random forest. False negatives—phishing websites incorrectly labelled legitimate—remained unchanged for every classifier.
That result is narrower than a guarantee of safe correction. Exact McNemar tests comparing predictions before and after revision were not statistically significant, with p-values of 0.5 or higher. The observed changes were too few to establish a reliable performance improvement.
The safeguards mattered in this experiment. Using metadata alone corrected more false alarms but also caused many phishing predictions to become incorrect legitimate labels. Among the seven tested configurations, only the complete four-rule combination reduced false positives without increasing false negatives across all four models.
What the logic engine contributes
The rules were implemented using Answer Set Programming and the Clingo solver. An equivalent conventional if-else procedure produced exactly the same predictions. The reported predictive benefit therefore came from the rules, not from ASP outperforming procedural code.
ASP instead supplied a declarative representation of defaults and exceptions. Using eXplainable ASP, the researchers generated derivation graphs tracing the facts and rule conditions behind a revision. These explain the post-processing decision, not the classifier’s entire internal reasoning.
The additional computation was not zero: the full reasoning pipeline took approximately 0.313 seconds for all 9,144 decisions on the reported computer. Linear scaling applies to this restricted, fixed rule structure, not to ASP generally.
What remains unproven
Evaluation covered one dataset, not changing threats across time or a live deployment. Metadata may become less informative, the length threshold may need recalibration, and conservative safeguards can prevent useful corrections. Unchanged false negatives on this test set do not guarantee unchanged false negatives elsewhere. The preprint also states that notebooks, logic files and altered-instance files will be released upon acceptance.
- phishing detection
- machine learning
- defeasible reasoning
- Answer Set Programming
- explainable AI
- false positives
- cybersecurity
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI claims-analysis preprint tests policy citations and privacy safeguards on synthetic data
Source published
Shared keywords: explainable ai
AS2 blends visual learning with soft logic; its reported perfect Sudoku score uses a discrete decoder
Source published
Shared keywords: answer set programming
Pairing predictive AI with a medical reference chatbot to explain diabetes classifications
Source published
Shared keywords: explainable ai
Mammography AI heat maps perform worse in dense breasts—but the reasons matter
Source published
Shared keywords: explainable ai
A balanced AI score is not immune to unbalanced data
Source published
Shared keywords: machine learning