TRANSMISSION // 2611.09256v1
Shared vehicle perception can be fooled by messages that look helpful
Source published
An arXiv preprint describes an attack that alters shared vehicle-perception features without querying the target model. Benchmark tests show high bypass rates against two defenses, while a proposed temporal trust system improves detection—but also rejects some legitimate collaboration.
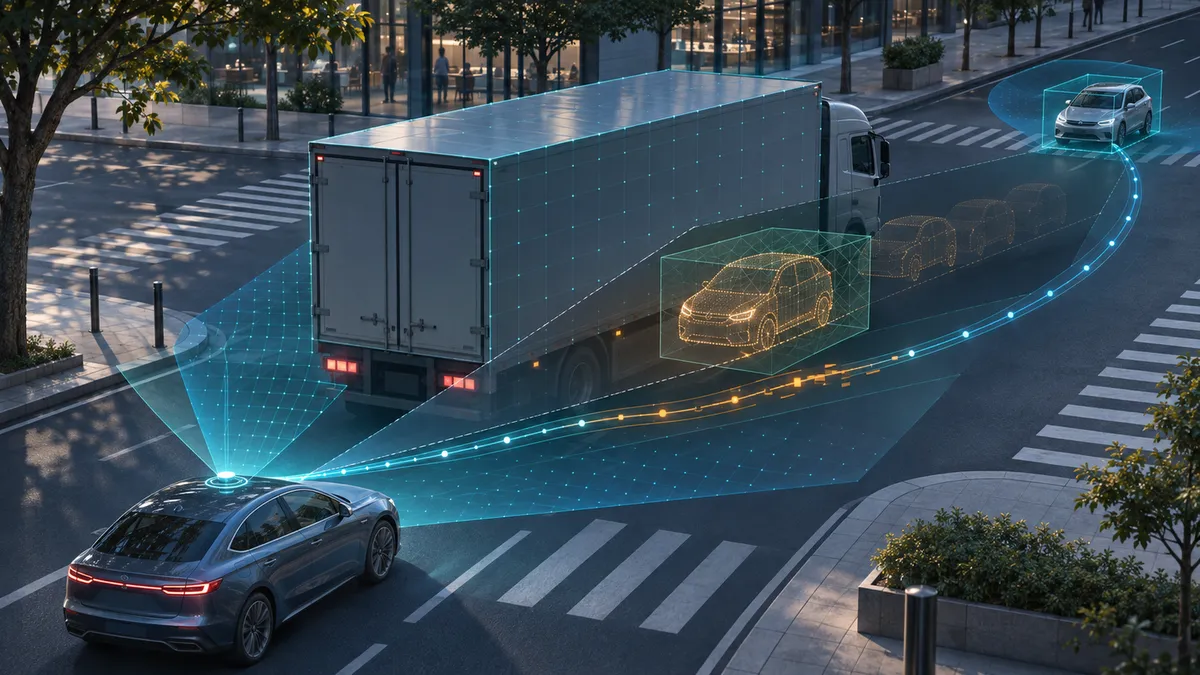
Vehicles that share sensor information can help one another detect objects hidden from their own view. But that advantage creates a security problem: the most useful outside information may also be the hardest to check. A new preprint explores how malicious messages can exploit this gap, and whether checking their consistency over time offers a stronger defense.
Hongwei Lin, Xun Huang, Chenglu Wen and Cheng Wang describe the work in an arXiv preprint submitted on November 6, 2026. The supplied record does not establish peer-reviewed publication. Their study concerns cooperative perception systems that exchange intermediate features—numerical representations extracted from sensor observations—before combining them to detect objects. It does not demonstrate an attack on vehicles operating on public roads.
The central vulnerability is what the researchers call verification asymmetry. A receiving vehicle can cross-check a collaborator’s message where its own sensors provide reliable evidence. Behind an obstruction or beyond its sensing range, it has less independent evidence. A malicious collaborator can therefore preserve agreement in easily checked areas while manipulating information elsewhere.
The team’s earlier Pretend Benign attack used this strategy but required access to the target model’s internal workings. It divided the scene into regions with different roles: reliable detections to largely preserve, uncertain or complementary detections to suppress, and unsupported locations where false detections could be reinforced or introduced. These categories were inferred from model responses, not guaranteed ground truth.
The new Transferable Pretend Benign method, or TrPB, builds that capability using several substitute models controlled by the attacker. Different models identify candidate regions, which are combined according to their roles rather than through one uniform agreement rule. The researchers then optimize a shared alteration across the substitute models, seeking patterns that transfer to an unseen target while retaining apparently legitimate agreement.
A faster version, RT-TrPB, shifts much of this computation offline. A lightweight network learns to predict the regions, while a dictionary stores reusable local alteration patterns. At runtime, the system selects and adapts those patterns instead of repeatedly running substitute models and iterative optimization. This is the meaning of amortized generation: expensive preparation is reused across subsequent messages.
“Zero-query” has a specific boundary here. The attacker receives no target predictions for refining the attack and cannot inspect the target’s architecture, parameters or gradients. However, it still needs compatible shared-feature interfaces and protocol-visible information. The standard evaluated configuration includes the receiving vehicle’s shared features; it is not an attack constructed without information about the cooperative scene.
Tests used two simulated datasets, OPV2V and V2XSet, plus V2V4Real, a dataset recorded with two real vehicles. Six model configurations combined two detection backbones with three fusion methods. For transfer tests, one configuration was held out as the target and the other five served as substitutes. Training and attack preparation used training data, while reported evaluation used separate validation data.
Against a PointPillars–V2VNet target, RT-TrPB bypassed the FLD defense in 97.6% of evaluated attacks on OPV2V, 82.1% on V2XSet and 100% on V2V4Real. Bypass means the malicious collaborator was accepted, not that every accepted message caused an equally severe error. On OPV2V, average precision at a 0.5 overlap threshold fell from 0.91 without attack to 0.61 under RT-TrPB with FLD. Average precision measures object-detection performance; the overlap threshold specifies how closely predicted boxes must match reference boxes.
Reported perturbation-generation times were 40.18–55.54 milliseconds on an NVIDIA RTX 3090 GPU. These measurements exclude the rest of the communication and perception pipeline and do not establish equivalent performance on onboard hardware.
The proposed defense, STTrust, adds temporal and historical checks to current-frame feature comparisons. It aligns earlier observations for vehicle motion, compensates for moving objects, and accumulates evidence for each collaborator identity. Persistent anomalies can lead to exclusion. On OPV2V, it raised average precision at the 0.5 threshold from 0.61 under RT-TrPB without defense to 0.88, close to the 0.89 reference obtained by ideally rejecting malicious collaborators. Recovery was less complete on V2XSet.
That protection has costs. In one component study, the full defense rejected 95.1–100% of attacks but accepted only about 70% of benign collaboration. Supplementary tests showed benign acceptance falling almost to zero under some position and orientation errors. The method also requires usable temporal evidence and stable identities. Tests against temporally smoothed and intermittent attacks were encouraging, but do not establish resistance to every adaptive strategy. The findings demonstrate a benchmark security weakness and a promising, imperfect countermeasure—not proven deployment safety.
- cooperative perception
- autonomous vehicles
- adversarial machine learning
- zero-query attacks
- transferable attacks
- sensor fusion
- temporal consistency
- STTrust