TRANSMISSION // 2611.09240v1
When more data hurts: a benchmark tests how AI combines images, text and changing networks
Source published
MM-DyGraph brings together five datasets to test AI systems that learn from evolving networks enriched with text and images. Its results show that visual information can help some predictions while harming others. A proposed context-aware model improves several benchmarks, but substantial exceptions and evaluation limits remain.
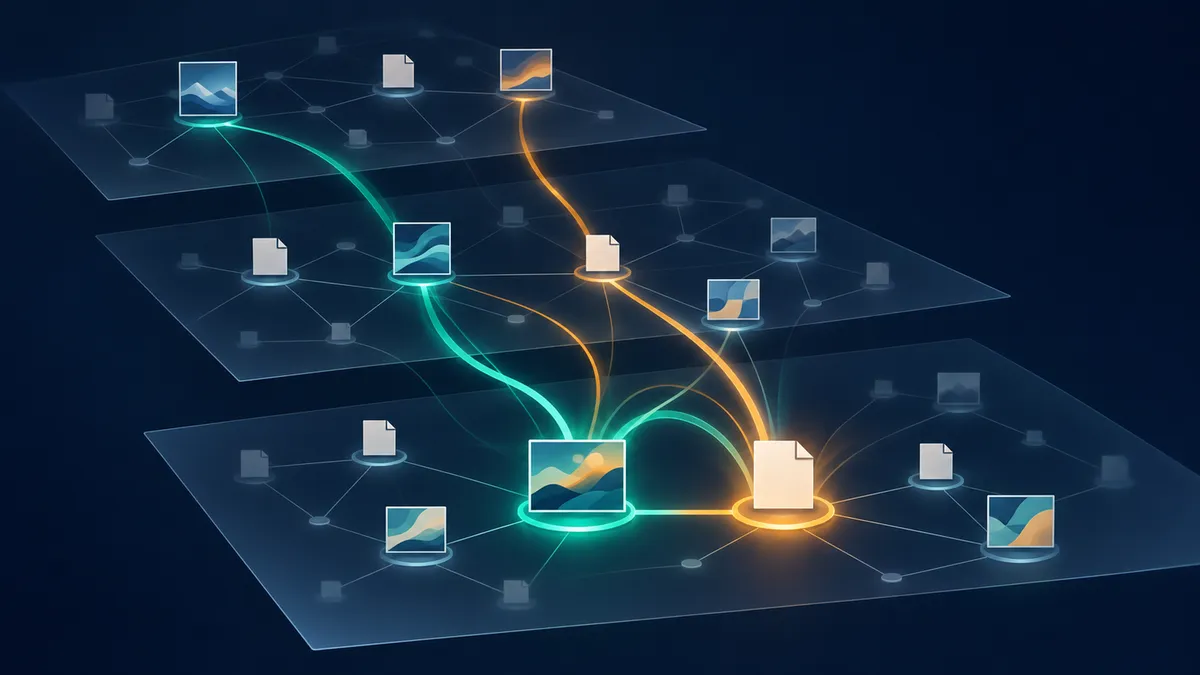
A product photograph might help an AI system distinguish two items, yet distract it when predicting a customer's next interaction. A new study explores this uneven value of information in networks that change over time, arguing that models need to consider not just what data they receive, but which prediction they are making.
Researchers at Tsinghua University introduce MM-DyGraph, a collection of datasets, evaluation tasks and a new model for multimodal dynamic graphs. A graph represents entities as nodes and their relationships as edges; a dynamic graph records how those relationships unfold over time. Multimodal means that text and images accompany the network. The paper was submitted to arXiv on November 6, 2026, as a preprint; the supplied record does not establish peer-reviewed publication.
The central question is whether adding photographs to textual and relational information reliably improves predictions. The answer in these experiments is no. Benefits vary across datasets, tasks, model architectures and individual predictions. Sometimes the interaction history already supplies a strong signal, leaving little room for images to help. In other cases, additional content appears to introduce distracting or poorly matched information.
MM-DyGraph contains five benchmark datasets drawn from four sources: GDELT sociopolitical events, Google Map City reviews, Amazon Industrial and Scientific reviews, Amazon Office Products reviews, and Yelp. Their images occupy different parts of the network. GDELT and Google Map City attach images to interactions, Yelp attaches them to nodes, and Amazon includes both. This lets researchers examine whether information about an interaction helps the same tasks as information about an entity.
Preparing the data involved consequential choices. The team removed selected users or businesses lacking relevant image-bearing content to make multimodal examples denser. It then used Qwen3-VL-8B-Instruct, a vision-language model, to score image–text relevance from zero to ten. Images scoring below six were discarded; where several survived, only the highest-scoring image was retained. Timestamps were grouped into 15-minute intervals for GDELT and Google Map City, and daily intervals for Amazon and Yelp.
The benchmark tests three abilities: predicting whether two nodes interact, classifying an observed interaction, and ranking the correct destination node among alternatives. For link prediction, interactions are ordered chronologically and split into 70% training, 15% validation and 15% testing. Evaluations distinguish future interactions in the observed network from interactions involving nodes absent during training. The default retrieval test ranks the true destination against 100 randomly sampled alternatives.
To compare input types, the researchers encoded text and images with CLIP, producing a 512-number representation of each. They tested random features, text alone, and text joined to image features across eight existing dynamic-graph methods. Text-only representations were duplicated to match the combined input size, and missing images were normally replaced with the corresponding text representation. Experiments used three random seeds.
The results show why joining feature vectors is not enough. On Amazon Office Products, for example, DyGFormer's average precision for link prediction involving previously unseen nodes fell from 73.50% with text to 68.64% with text and images. Such cases support the narrower conclusion that more input is not automatically more useful—not that images are generally harmful.
The proposed response is Target-aware Spatial-Temporal Multimodal Fusion, or TST-MF. It separately summarizes a queried node's interaction history and its graph neighborhood. Here, spatial context means network relationships, not necessarily geographic distance. A two-stage attention mechanism first selects contextual evidence relevant to the queried entities, then uses that context to combine text and image features. In accessible terms, the model tries to decide which information matters for this particular prediction rather than applying one fixed mixture everywhere.
Several reported comparisons favor that approach. With text and images, TST-MF reached 93.98% average precision on GDELT's transductive link-prediction test, versus 92.46% for simple concatenation in DyGFormer. On Yelp's default transductive retrieval test, its Hits@10—the share of correct destinations placed in the top ten—was 79.11%, versus 67.54%. But it was not a universal winner: on Google Map City's unseen-node link-prediction test, it scored 65.49% average precision against DyGFormer's 83.05%, and it trailed several methods on interaction classification.
Evaluation design also changes the picture. Some default retrieval scores approached 100%. Using previously interacting destinations as harder alternatives sharply reduced scores in several datasets and changed model rankings, although Google Map City retained near-perfect results for DyGFormer. The headline retrieval figures therefore should not be read as equivalent to searching an entire real-world catalog.
Important limits remain. Filtering can favor clearer, better-aligned examples over messy real-world data, and automated relevance judgments depend on the filtering model and prompt. The study concentrates on text and images and does not systematically test successive changes to an entity's own raw content. These are offline benchmark results, not demonstrated deployment benefits. The contribution is a testing framework and evidence that information selection matters, alongside a promising but unevenly successful way to perform it.
- MM-DyGraph
- dynamic graphs
- multimodal machine learning
- graph neural networks
- TST-MF
- link prediction
- benchmark evaluation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Animal Identification Scores Can Hide Other Clues to a Match
Source published
Shared keywords: benchmark evaluation
SIMBAD tests when traffic forecasts should trust the past
Source published
Shared keywords: graph neural networks
A graph-learning method updates its view as connections appear
Source published
Shared keywords: graph neural networks
When AI coding models use up their answer budget on reasoning
Source published
Shared keywords: benchmark evaluation
A New Geometry for Graphs Whose Neighbors Differ
Source published
Shared keywords: graph neural networks