TRANSMISSION // 2611.09154v1
Teaching vision-language AI when a short answer is enough
Source published
DR-BOLT trains a vision-language model to alternate between direct answers and longer reasoning using a fixed bank of examples. In its main comparisons on ScienceQA and three held-out transfer benchmarks, the preprint reports improved accuracy–response-length trade-offs—not uniformly shorter answers than every alternative. Its evidence is limited to curated training conditions and does not establish broad robustness or deployment speed gains.
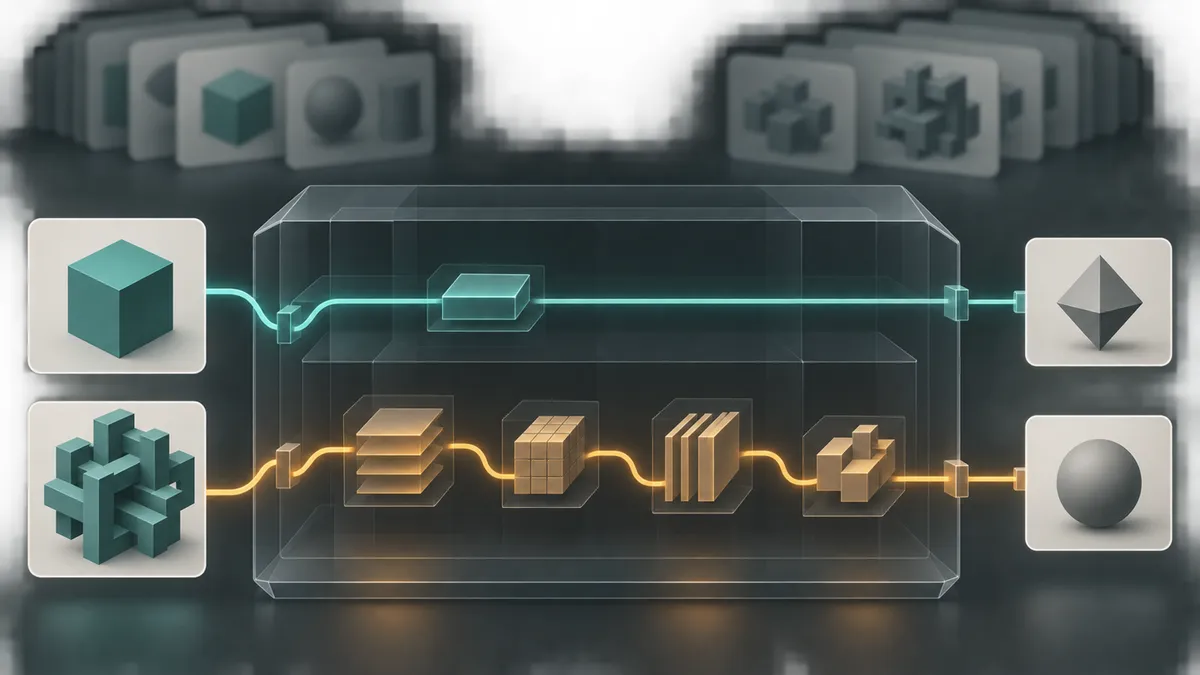
An AI system interpreting an image may need several steps to solve a mathematical problem, yet little explanation to recognize a familiar symbol. A new study asks whether one model can learn that distinction—and whether correcting an imbalance in its training examples helps it avoid becoming either relentlessly verbose or too quick to answer.
Two ways to answer
Vision-language models process images alongside written questions. Some produce a direct answer; others generate an extended reasoning trace before reaching a conclusion. Longer responses can help on difficult tasks, but requiring them for every question adds unnecessary output.
In Learning When to Think, Hongbin Lin and colleagues propose Dual-Reference BOLT, or DR-BOLT. Their approach trains a single model to produce either response style without a separate classifier choosing its mode at deployment. The work was posted as an arXiv preprint on November 6, 2026; the supplied record does not establish its peer-review status.
Here, “thinking” means generating an explicit reasoning trace. It is a description of output behavior, not evidence that the model reasons like a person.
Correcting the example mix
The researchers start with two eight-billion-parameter models from the Qwen3-VL family: an Instruct version supplying fast responses and a Thinking version supplying slow ones. For each training input, they collect seven fast candidates and three slow candidates.
They score these responses for final-answer correctness, valid formatting and brevity. A short warm-up exposes the trainable model to both styles. Subsequent training uses the collected responses, giving greater influence to candidates with better scores. The bank and its weights stay fixed during this optimization, unlike online reinforcement learning that repeatedly generates fresh responses as training proceeds.
The central distinction is between how examples were collected and the reference mixture used to define the learning target. Although 70% of candidates come from the fast model, the main setup gives the two sources equal prior weight. That does not require the finished model to answer quickly half the time: rewards can favor different styles for different questions.
To correct the collection imbalance, the practical method multiplies fast-source weights by about 0.714 and slow-source weights by about 1.667, alongside reward-based weighting and normalization for each question. This prevents the more numerous fast examples from receiving disproportionate influence simply because of their sampling rate.
Those simple multipliers approximate a more expensive calculation. They work best when the two source models produce clearly distinguishable response formats. The authors test that assumption and find close, though imperfect, agreement with the exact correction.
What the experiments found
For ScienceQA, the researchers train on the benchmark’s training split and evaluate on its official test split. DR-BOLT achieves 96.7% accuracy with responses averaging 20.4 words. Their reproduction of GRPO, an online reinforcement-learning baseline, reaches 96.2% with 201 words on average. The accuracy difference is modest; the response-length difference is much larger.
A separate model trained on ViRL39K is evaluated on three held-out benchmarks. DR-BOLT scores 60.6% on MathVision, 79.9% on DynaMath and 58.1% on MMMU-Pro, exceeding the tested alternatives in the main comparisons.
The strongest controls compare offline methods using identical candidate banks, rewards, initialization and training budgets. This helps distinguish the training objective’s contribution from simply having access to a good reasoning teacher. Against a mixture-reference preference-learning baseline, for example, DR-BOLT improves MathVision accuracy from 56.8% to 60.6% while reducing average response length from about 1,398 to 1,058 words.
Across the three transfer benchmarks, 24.1% of DR-BOLT outputs are classified as slow by their reasoning format. That is neither a universal rate nor a measurement of internal computation.
Training takes 69.7 hours versus 202.4 hours for reproduced GRPO on four A100-80GB GPUs—a reported 2.90-fold speedup. The accounting includes candidate generation and other preparation. It measures training time, not user-facing response latency.
Boundaries of the evidence
The results depend on the quality and coverage of a fixed response bank, including successful examples supplied by the slow teacher. The method does not continually explore new responses during optimization.
Its reward checks final answers, not the validity of intermediate reasoning. Deterministic answer-parsing rules also have limits: extracting a number or matching text is not a general test of mathematical equivalence.
The authors explicitly caution that the transfer benchmarks may share task types or sources with training data. These tests therefore do not establish generalization to rigorously verified unfamiliar distributions. The study also lacks multi-seed error bars for all benchmark scores, leaving uncertainty about the reliability of smaller differences.
An additional spatial-reasoning experiment illustrates the trade-off: DR-BOLT scores slightly below the slow reference, 54.6% versus 54.8%, while producing responses about 75.5% shorter. The supported conclusion is narrower than “less reasoning is always better”: under the studied conditions, training can preserve useful longer responses while avoiding many unnecessary ones.
- vision-language models
- adaptive reasoning
- DR-BOLT
- offline optimization
- multimodal AI
- reasoning efficiency
- Qwen3-VL
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Why a personal AI assistant needs to find the right person first
Source published
Shared keywords: multimodal ai, vision language models
RECAP speeds up vision-language models by recycling predictions in context
Source published
Shared keywords: multimodal ai, vision language models
Teaching an AI search agent when to look for images
Source published
Shared keywords: multimodal ai
Giving AI Agents an Explicit Reason to Look
Source published
Shared keywords: vision language models
UniCompress packs four vision-language skills into a smaller model
Source published
Shared keywords: vision language models