TRANSMISSION // 2611.09142v1
Teaching molecular AI chemistry rules in stages improves 3D generation
Source published
SensDiff combines diffusion-based molecule generation with progressively introduced chemistry constraints. The preprint reports improved benchmark validity and property control, but its computational results do not establish drug safety, effectiveness or guaranteed chemical correctness.
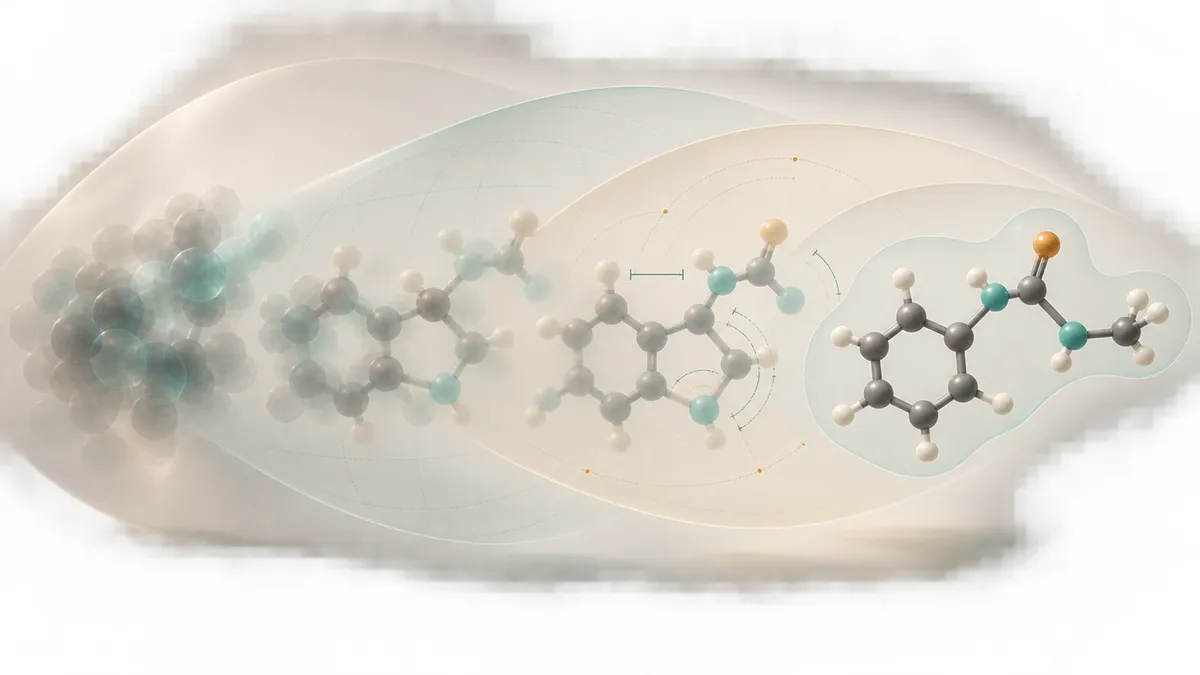
A molecular generator can produce an arrangement of atoms that resembles its training data yet breaks basic chemistry rules. Researchers at The Hong Kong Polytechnic University propose teaching those rules explicitly—and introducing them in a carefully chosen order.
Generating a convincing molecular structure requires more than placing atoms in roughly familiar patterns. Atoms must avoid crowding one another, bonds must have plausible lengths and angles, and each atom must support an acceptable combination of bonds. A new study reports that teaching these requirements progressively can improve an AI model’s molecular designs.
Zhuoran Li, Xu Sun, Chang Wen Chen and Wanyu Lin introduce Sequential Neuro-Symbolic Constrained Diffusion, or SensDiff, in an arXiv preprint submitted on November 6, 2026. Their approach combines a neural generator with explicit, mathematically expressed chemistry rules. Its strongest reported benchmark results use those rules during both training and generation.
A chemistry curriculum for denoising
Diffusion models generate molecular structures by learning to reverse a process that adds noise to molecular representations. During generation, a noisy starting state is progressively refined into atom identities and three-dimensional coordinates. However, learning statistical patterns from examples does not automatically prevent chemically implausible outputs.
SensDiff builds primarily on an existing latent diffusion model called GEOLDM. Here, “latent” means the generator works with a learned continuous representation rather than directly manipulating a finished molecular structure.
To connect that representation to chemistry, the researchers decode intermediate states into coordinates and probabilities for atom identities. A separate prediction component estimates probabilities for different bond types between atom pairs. Keeping identities and bonds probabilistic allows the training process to calculate how changes would reduce rule violations, rather than losing that information through an early, hard choice of atom or bond type.
Four rules provide the feedback: avoiding overlap between non-bonded atoms, maintaining plausible bond lengths, maintaining plausible bond angles, and respecting valence—the total bond order an atom can accommodate. The rules become differentiable penalty functions, informed partly by statistics extracted from the training molecules. These mathematical “energies” measure violations; they are not a complete calculation of molecular physical energy.
The central design choice is timing. Across training epochs, the model first learns with the overlap penalty, then adds bond-length, bond-angle and finally valence penalties. Newly introduced penalties increase gradually, with further adjustment based on their recent behavior. The authors argue that reliable geometry must emerge before more demanding connectivity rules provide useful guidance.
This training curriculum is distinct from the sequence of steps used to generate an individual molecule. During training, symbolic feedback passes through a single sampled reverse step, avoiding the expense of reconstructing the entire generation trajectory for every update. At generation time, additional rule-based refinement can adjust intermediate states without retraining the model.
What the benchmarks show
The researchers evaluated SensDiff on QM9, which contains small organic molecules, and GEOM-Drugs, which contains larger, more varied drug-like structures. They report evaluating competing methods through a unified pipeline.
On QM9, SensDiff reached 96.9% chemical validity, compared with 94.4% for the strongest listed baseline on that metric. On GEOM-Drugs, it reached 97.2%, compared with 95.8% for the best listed baseline.
A separate whole-molecule stability measure showed a larger advantage on GEOM-Drugs: 79.4% for SensDiff versus 66.8% for the strongest listed competitor, a difference of 12.6 percentage points. These stability scores describe benchmark checks, not experimentally measured persistence or safety.
Component comparisons support the importance of staged learning. Activating all four constraints simultaneously from the beginning produced 89.4% validity and 78.8% molecule stability on QM9, below the full method’s 96.9% and 95.6%. Training-only and sampling-only variants also performed less well than using constraints at both stages.
SensDiff additionally recorded the lowest reported target-matching errors across six individual quantum-property generation tasks. In a separate drug-design demonstration, sampling-time guidance targeted seven descriptors simultaneously, including molecular weight, polarity, drug-likeness and estimated synthetic accessibility. Meeting these computational criteria does not demonstrate oral bioavailability or therapeutic usefulness.
Better constraints, not guaranteed chemistry
The evidence remains computational and is presented in a preprint. The authors report means from ten repetitions but explicitly state that they do not provide error bars or statistical-significance tests, making small differences harder to assess.
The method also depends on manually specified rules, empirical chemistry statistics and a learned bond predictor. Its penalties encourage compliance rather than guarantee it, and the authors acknowledge that broader chemical spaces and domain-dependent training schedules need further investigation.
The practical contribution is therefore a way to steer molecular generators toward more plausible structures while making failures easier to diagnose—not a replacement for experimental validation or a demonstration of successful drug discovery.
- SensDiff
- 3D molecule generation
- diffusion models
- neuro-symbolic AI
- chemical constraints
- molecular geometry
- drug discovery
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
ALBI tests language-model rules with a logic engine
Source published
Shared keywords: neuro symbolic ai
Can AI redesign toxic molecules? A benchmark finds uneven results
Source published
Shared keywords: drug discovery
AS2 blends visual learning with soft logic; its reported perfect Sudoku score uses a discrete decoder
Source published
Shared keywords: neuro symbolic ai
UniRGBA adds transparency to a pretrained video generator—with trade-offs
Source published
Shared keywords: diffusion models
PEEK improves diffusion image scores at matched denoiser-evaluation budgets
Source published
Shared keywords: diffusion models