TRANSMISSION // 2611.09092v1
AdaAlloc helps video AI decide where to look closely
Source published
AdaAlloc divides a video model’s visual input between broad context and detailed inspection. The researchers report better multiple-choice accuracy across four benchmarks, but the extra planning and checking increase runtime.
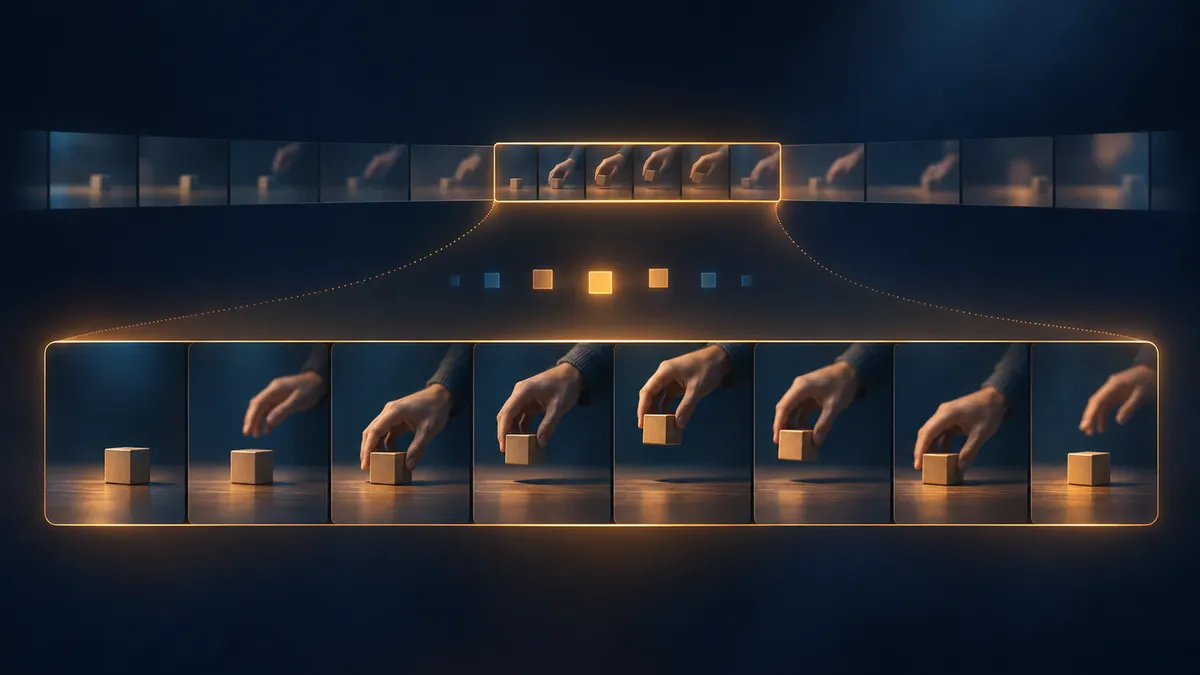
A model answering questions about an hour-long video faces a practical choice: scan broadly or inspect a few moments closely. AdaAlloc makes that choice question by question, allocating limited visual capacity between an overview and targeted detail.
A limited budget for seeing
The clue needed to answer a video question might occupy only seconds: a handwritten number, a brief gesture or an object changing position. Sampling frames evenly across a long recording can miss that clue. Concentrating on selected clips can preserve detail while losing the context that distinguishes one repeated event from another.
Joungbin An and Kristen Grauman, at the University of Texas at Austin, address this tradeoff with AdaAlloc. Their paper was posted to arXiv on November 6, 2026; the landing record identifies it as accepted to NeurIPS 2026. The findings described here are the authors’ reported experiments in that arXiv version.
Their central idea is to allocate visual tokens, the units used to represent images inside a multimodal model. More frames provide broader coverage; higher-resolution frames consume more tokens but can preserve smaller details. AdaAlloc decides how to divide that capacity rather than merely choosing which frames to show.
From overview to evidence
The framework uses existing pretrained models without additional training. Its planning stage examines a sparse, low-resolution overview alongside the question and answer choices. It selects one of five allocations: entirely global, mostly global, evenly divided, mostly local or entirely local. A mostly local policy reserves 30% of the answering budget for global coverage and 70% for selected evidence.
When targeted searching is needed, the planner generates descriptions of relevant events. A separate model, UniversalVTG, locates candidate time intervals matching those descriptions. These candidates join timestamps or approximate windows suggested by the question and overview.
The resulting “temporal memory” is a collection of possible evidence locations, not an established account of what happened. A multimodal model inspects sampled candidate frames and can keep, discard, adjust or merge intervals. The final answerer receives the selected combination of global frames and more densely sampled, higher-resolution local frames. If no reliable local memory survives, the system falls back to additional overview coverage.
Not every question takes this route. When uniform sampling already provides sufficiently dense coverage, AdaAlloc can answer directly, bypassing planning and retrieval.
What the experiments found
The main controlled comparison used Qwen3-VL-8B-Instruct for both AdaAlloc and uniform sampling, with matching final-answer visual-token budgets and decoding settings. Tests covered four multiple-choice benchmarks using video alone, without subtitles.
At the 32K-token budget, reported accuracy changed as follows:
- LVBench: 46.1% with uniform sampling to 56.6% with AdaAlloc.
- MLVU-Test: 61.4% to 67.1%.
- VideoMME: 69.5% to 70.7%.
- LongVideoBench’s validation split: 63.9% to 67.5%.
The largest improvement was therefore 10.5 percentage points, not a 10.5% relative increase. AdaAlloc also improved all four benchmark scores at 16K tokens. The authors found the biggest gains on the benchmarks containing the longest videos.
Component comparisons support the importance of adapting the allocation. At 16K tokens, replacing an always-even global/local split with question-dependent allocation improved accuracy by 1.5–3.2 points across the four benchmarks. A second answering backbone, VideoLLaMA3-7B, also improved on all four at 32K tokens, though its average gain was smaller.
Equal answering budgets, unequal total cost
The budget comparison needs an important qualification: it matches the visual input allowed for the final answer, not total pipeline computation. Planning and memory refinement require additional calls, each capped at the same per-call budget.
On NVIDIA A40 hardware, the authors measured runtime increasing from 14 to 35 seconds at 16K tokens and from 25 to 58 seconds at 32K. Training-free does not mean computation-free.
The approach also cannot guarantee that it finds the decisive evidence. If both the sparse overview and retrieval miss an event, refinement may never see it. The five allocation choices need not be optimal for every question, and the evaluation concentrates on multiple-choice tasks with 7–8-billion-parameter answering models.
Aggregate improvements also conceal regressions. At 32K, AdaAlloc improved seven of VideoMME’s twelve subcategories but declined in five, including temporal perception. Comparisons with other published systems involve differing models and protocols, so they are not uniformly controlled head-to-head tests.
The result is evidence for a specific strategy: spend more visual capacity where a question appears to need it, while accepting extra inference work and the continuing risk of overlooking the crucial moment.
- AdaAlloc
- video question answering
- multimodal AI
- visual tokens
- temporal grounding
- long-video understanding
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Can combining biopsy images and clinical data improve predictions in inflammatory bowel disease?
Source published
Shared keywords: multimodal ai
Teaching a visual AI to forget a connection, not a fact
Source published
Shared keywords: multimodal ai
AI diagram errors shift from counting to seeing when code takes over
Source published
Shared keywords: multimodal ai
Why a personal AI assistant needs to find the right person first
Source published
Shared keywords: multimodal ai
V-STORM tests whether video AI can connect the evidence it finds
Source published
Shared keywords: multimodal ai