TRANSMISSION // 2611.09085v1
AI language scores can miss failures in romanized Hindi, Telugu and Kannada
Source published
A preprint finds that semantic-similarity scores can reward English copies and overlook script errors in romanized Indic responses. Native-speaker assessments reveal additional quality differences, although small, deliberately selected samples and inconsistent reporting limit the conclusions.
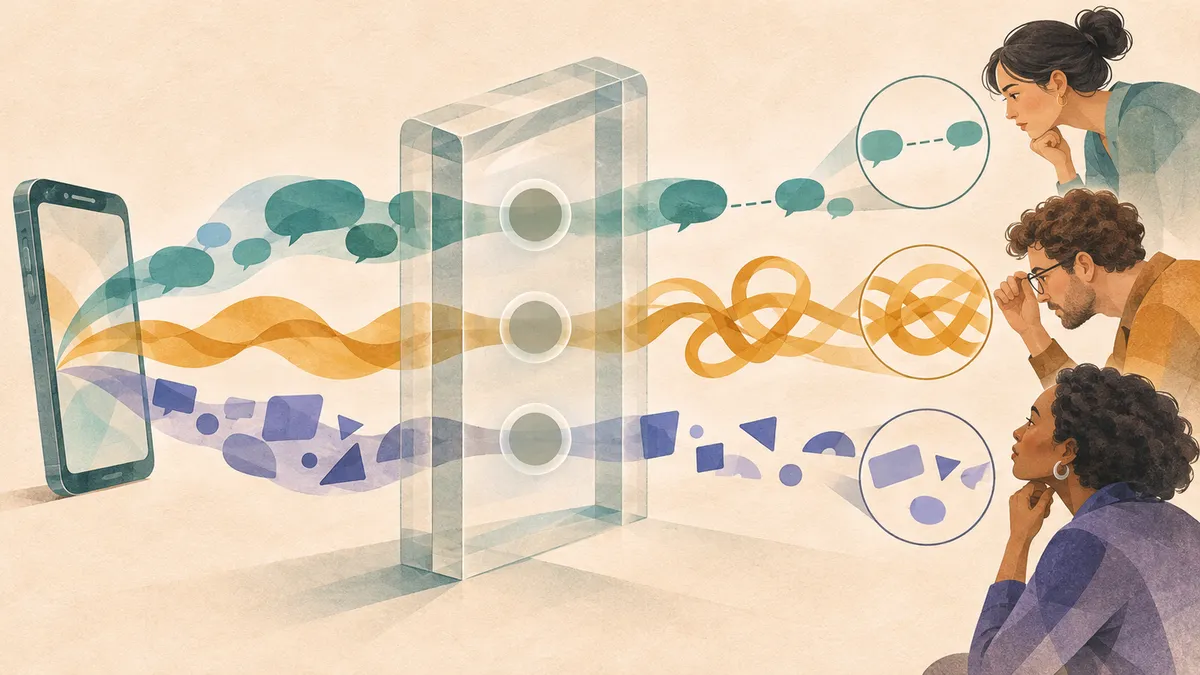
An AI response can preserve a message’s meaning while failing the person who requested it. A study of Hindi, Telugu and Kannada written in Latin letters shows why checking semantic similarity alone can miss that distinction.
For someone expecting Hindi written as “aap kaise hain,” an answer in English or Devanagari does not satisfy the same request. Romanized language uses Latin letters, but its vocabulary and grammar remain those of the underlying language. Evaluating whether an AI system handles that interface requires more than checking whether its answer means roughly the right thing.
That is the argument of The Invisible Gap: Romanized Indic Generation Fails Where Automatic Metrics Succeed, a preprint posted on November 6, 2026, by Madhu Sudhan Rao Beesetty, Surbhi Sharma, Devesh Maheshwari and Lokesh Meesala. Their experiments identify cases in which automatic scores reward responses that native speakers consider unusable.
What the researchers tested
The team selected 142 English query–response pairs from OpenAssistant, covering technical, emotional, narrative and factual material. Four models—Claude Opus 4.8, GPT-5.5, Gemini 2.5-flash and Qwen3.5-35B—were instructed to produce romanized versions in Hindi, Telugu and Kannada. This yielded 1,704 responses across the model–language combinations.
Each generation request asked for both the converted query and response in a structured JSON object. Instructions required Latin-script output while allowing English words where they improved readability. Kannada received additional instructions against English-like sentence structure. Consequently, the experiment tests conversion of supplied English conversations, not the full range of conversations initiated naturally in romanized languages.
The researchers compared generated responses with the English originals using BGE-M3, which measures similarity between numerical representations of texts, and BERTScore, which aligns contextual representations of individual tokens. These methods assess semantic correspondence; they do not directly establish that a response uses the requested language, script or conversational tone.
When similarity rewards failure
The clearest illustration is an unchanged English answer. It can receive perfect similarity scores against its English source while completely failing the romanization instruction. The authors report BGE-M3 and BERTScore values of 1.000 for verbatim-English Telugu-task responses from Qwen.
Script errors create a different mismatch. Gemini inserted non-Latin characters into 24 of 142 Telugu responses, or 16.9%. The reported examples include Telugu passages and contamination from other languages. Such responses can retain meaning and therefore score well despite violating the requested writing system.
Qwen’s prominent failures instead involved returning English and generating repetitive text. The authors identified 13 responses meeting their repetition-failure criterion, all from Qwen. They report that these received native-speaker usability scores of zero even though unadjusted BGE-M3 scores ranged from 0.38 to 0.72.
To make failures count, the team assigned zero automatic scores to empty responses, exact English copies, script-contaminated outputs and specified repetition patterns. Those responses stayed in the denominator rather than disappearing from the averages. This policy deliberately combines semantic performance with reliability; it does not make the underlying similarity metrics capable of recognizing every linguistic problem.
What native speakers noticed
Human evaluation covered a diagnostic selection of 72 responses, with 24 per language. The selection deliberately included failures, difficult prompts, disagreements between metrics and clean examples. One native speaker evaluated each language.
The reported human totals averaged 10.73 out of 12 for GPT-5.5 and 9.30 for Claude. Their full-dataset BGE-M3 averages were much closer: 0.790 and 0.786. Raters identified differences in naturalness, grammar, word choice, register and usability that semantic similarity did not express clearly.
These comparisons require care. The human scores describe a selected diagnostic subset, whereas the automatic averages describe the full evaluation. They also use different scales. The numbers illustrate a mismatch between assessments, not a calibrated numerical measure of how much one metric underestimates human judgment.
Important limits
With only one rater per language, the study cannot measure agreement among speakers evaluating the same language. Its deliberately selected human sample cannot establish population-wide failure rates. The experiments also lack repeated-generation estimates and confidence intervals, and cover only three languages and four models.
Reporting inconsistencies add uncertainty. The paper describes a ten-dimension rubric with a maximum of 12 points, although the listed allocations sum to 25; the main results instead sum five dimensions to 12. Its headline Qwen Kannada English-only rate also differs from the strict-copy count in its table, alongside a broader overlap-based analysis. These definitions and totals need clarification before precise rates or scoring procedures can be reproduced confidently.
The practical conclusion is narrower than a universal model ranking: semantic resemblance alone does not establish successful romanized communication. The authors recommend combining similarity measures with script checks, explicit failure accounting and native-speaker assessment—separate checks for meaning, instruction compliance and whether the result actually reads naturally.
- romanized Indic languages
- Hindi
- Telugu
- Kannada
- language model evaluation
- BGE-M3
- BERTScore
- native-speaker assessment
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When the Same Shape Has Different Neural Network Weights
Source published
Shared keywords: language model evaluation
A Smaller AI Model for Assamese Shows Promise—and the Limits of Fluent Answers
Source published
Shared keywords: language model evaluation
Switching Off AI Experts Can Break More Than Routing
Source published
Shared keywords: language model evaluation