TRANSMISSION // 2611.09030v1
Robot-coding agents need better failure diagnosis, not just more feedback
Source published
A simulation preprint finds that AI agents’ ability to improve robot-control code depends on how they interpret failures. Feedback organized around meaningful actions and object geometry helped, while training first with exact simulator information produced mixed results.
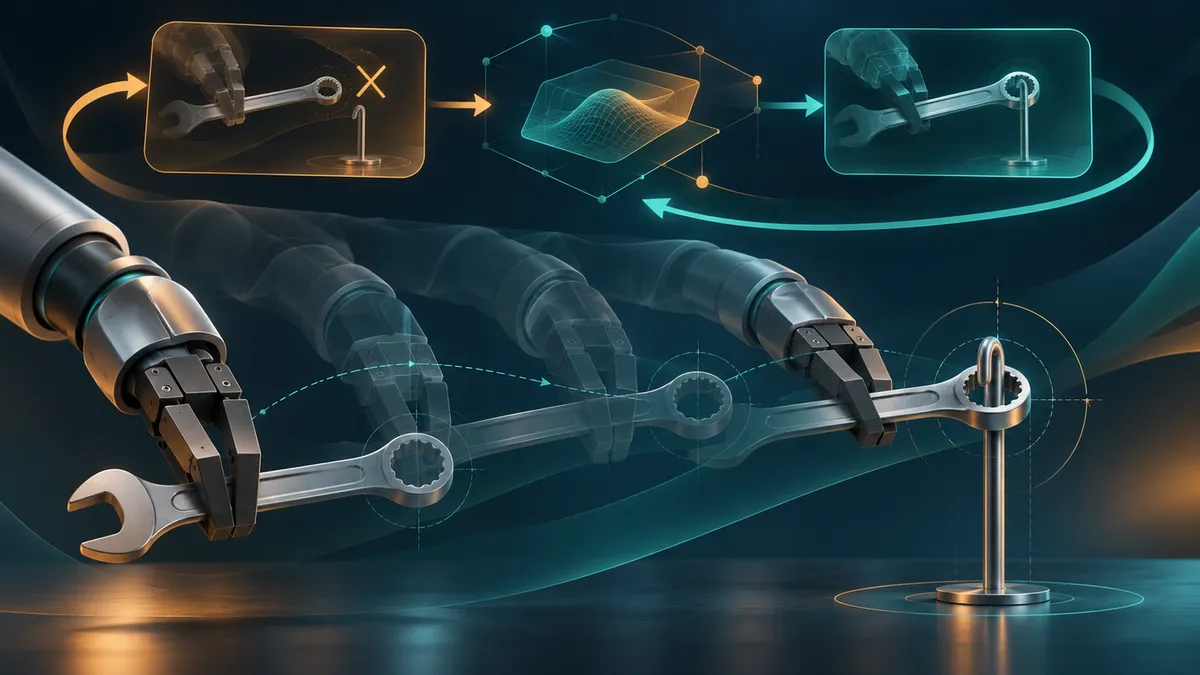
When a robot misses a hook, the mistake may have happened much earlier: it might have grasped the tool in the wrong place. A new preprint examines whether AI coding agents can trace such failures backward and rewrite their control programs. Its central finding is that supplying information is not enough; agents must translate it into the right change.
Kaiyuan Chen, Xinyue Zhu and colleagues at UC Berkeley, Bosch and NVIDIA describe the study in a preprint posted to arXiv on November 6, 2026. Rather than introduce a new robot-learning architecture, they varied components of an existing simulation-based learning loop: the coding model, available robot skills, execution feedback and training curriculum.
Testing the repair loop
The study covered nine task categories across two benchmarks. Five VABAR tasks included hanging a wrench, packing syringes, meshing gears, inserting a USB-C plug and routing a cable. Four MimicGen tasks involved kitchen manipulation, a coffee machine, threading and mug cleanup. The VABAR experiments and curriculum experiments used different task configurations and learning budgets.
An agent first wrote an executable robot policy—a program connecting perception, planning and control routines. The simulator ran that program, generated feedback and returned it to the agent for revision. This was code editing informed by physical interaction, not simply learning from a numerical reward.
The main VABAR protocol used four training layouts, five validation layouts and ten held-out test layouts per task. Agents received training feedback, not validation or test results. The study’s accounting lists 631 runs, including superseded experiments and dropped conditions, and 27,620 simulated policy episodes.
Similar starts, different improvements
Models with comparable initial performance diverged after feedback. Claude Fable 5.1 increased from 44% to 64% overall success after two feedback rounds, while Claude Sonnet 5 moved from 45% to 46%. An Opus 5 setting rose from 45% to 74%, although its protocol included exceptions described in the appendix.
These percentages require care: the model-comparison table reports the best held-out result reached within each feedback budget, rather than necessarily the latest policy or the policy selected by validation. Success was generally scored per object or subgoal, not as completion of every requirement in a whole episode.
Code analysis also associated stronger improvement with more newly written task-specific logic. The authors interpret expert skills as useful starting points for some models but boundaries that others rarely moved beyond. That association does not establish that writing more code itself causes better performance.
Feedback needs meaningful structure
The feedback experiments began from shared initial programs, helping separate feedback effects from differences in starting code. Reports organized around meaningful policy steps reached 52% overall success, compared with 25% for episode-level reports and 36% for reports organized around individual robot motions.
Tool Hanging illustrated why. An agent seeing episode-level feedback repeatedly changed the final reaching stage, although an earlier estimate of the wrench’s ring was wrong. Step-level feedback exposed that upstream mistake. Success reached 90%, versus 7% with episode-level reporting. More detailed timing was not universally better, however: episode-level feedback achieved 90% on Syringe Packing, where the final misplaced syringe already revealed the relevant problem.
Spatial organization mattered too. Reports using world-coordinate states and relations reached 30% overall success; object-centered representations reached 40%. Adding annotations for functional parts, such as a wrench ring and hook shank, raised the result to 52%. The findings suggest that agents struggled to derive useful geometric relationships from less explicitly organized information.
Recognizing an error still did not guarantee a sound motion plan. In Syringe Packing, the robot had to maneuver a 150-millimeter syringe through a 55-millimeter opening. Agents without expert skills often added staging heights, clearance constants or retries rather than independently building the human policy’s explicit collision representation.
Exact information can leave brittle habits
A separate curriculum experiment first supplied exact simulator geometry, then switched policies to camera-based perception. Results varied sharply: Threading reached 86% with the curriculum versus 2% without it, while Kitchen reached 33% versus 62%.
The authors observed policies retaining strategies that depended on precise geometry. But this interpretation has an important qualification: the conversion instructions explicitly required preserving task decomposition and manipulation logic. Persistence therefore cannot be attributed solely to an agent’s reluctance to restructure code.
What remains uncertain
All experiments were simulated, with fixed robot configurations and bounded scene variation. They do not demonstrate transfer to physical robots or unfamiliar robot bodies. Most main VABAR tasks used relatively simple, uncluttered settings, and some individual results varied substantially between runs.
The appendix also notes legacy scoring differences in some reference runs. Curriculum comparisons used only three runs per setting and ten held-out layouts; those held-out results also selected the privileged checkpoint for conversion. These qualifications limit broad conclusions. The evidence supports a narrower lesson: within these tests, useful robot self-improvement depended on connecting physical failures to appropriate program changes, not merely providing more observations.
- agentic robotics
- robot manipulation
- AI coding agents
- simulation
- execution feedback
- spatial reasoning
- curriculum learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
WorldMind tests spatial reasoning without turning every imagined view into an image
Source published
Shared keywords: spatial reasoning
AI coding agents build a robotics simulation benchmark
Source published
Shared keywords: ai coding agents
Robots may learn more from human corrections when they do not copy them exactly
Source published
Shared keywords: robot manipulation
A robot's-eye view, generated from outside video
Source published
Shared keywords: robot manipulation
Choosing Robot Policies Without Testing Every Checkpoint
Source published
Shared keywords: robot manipulation