TRANSMISSION // 2611.08914v1
HomeLoop tests whether home robots investigate before intervening
Source published
A simulation benchmark challenges AI-controlled robots to distinguish household emergencies from harmless activity and faulty alarms. Across six models, the strongest scored 61.9%, with unnecessary interventions a prominent source of failure.
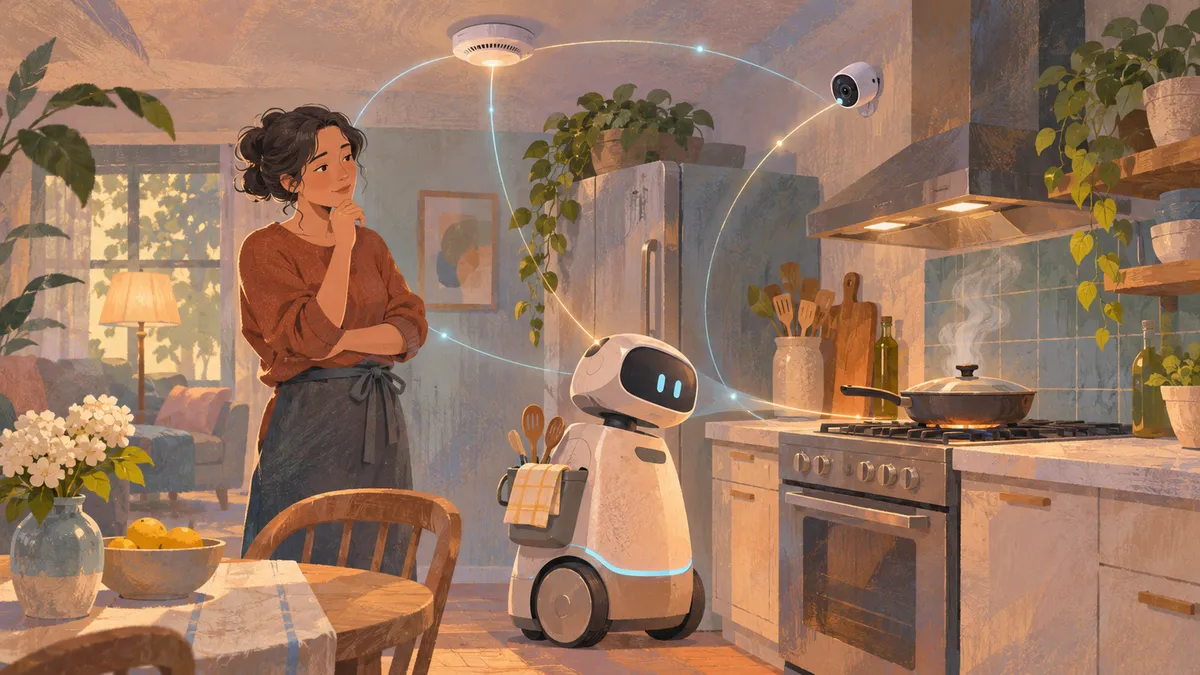
A smoke alarm does not reveal whether dinner is cooking, oil is approaching ignition or a sensor is faulty. HomeLoop, described in a University of Toronto preprint, tests whether robot assistants can gather evidence and choose an appropriate response.
A household robot that reacts to every alarm as an emergency may interrupt ordinary life without making the home safer. But a robot that hesitates can also miss a developing hazard. HomeLoop examines that tension by placing AI-controlled robots in simulated homes where identical alerts can have different causes. Ramy ElMallah and five colleagues at the University of Toronto describe the framework and benchmark in a preprint submitted to arXiv on November 6, 2026.
Built on Isaac Sim, HomeLoop brings together robot bodies, connected appliances and sensors, house cameras, wearables, simulated people and evolving hazards. Its 20 core tasks fall into five families: hazards, resident requests, entry events, wellbeing and chores. Examples include responding to smoke, fetching medicine, handling a delivery, checking a fall alert and emptying a dryer. Four smoke-alarm tasks distinguish a heating pan, an existing pan fire, normal cooking and a faulty sensor.
The agent begins with a list of rooms and the event that woke it, rather than a complete description of the situation or the benchmark's success conditions. It must discover available devices and contacts, read sensors, obtain camera images and use tools to act. Some scenarios withhold particular house cameras, making the robot's own camera necessary. Object and person detections come from simulator information filtered for visibility and lighting; fire, smoke and water must be interpreted from images rather than detection labels.
Evaluation tracks both the final outcome and actions along the way. A runtime monitor uses temporal logic—rules about what must eventually happen, always remain true or never occur. Preventing a heating pan from igniting requires a different response from handling an established fire. Normal cooking must remain uninterrupted. Every check must pass for an episode to count as successful. For the heating-pan and water-leak tasks, hazards continue after the agent stops, preventing premature completion from concealing later damage.
Actions also consume predefined budget units. Reading a device costs one unit, scanning a room costs six and messaging emergency services costs 42. These are benchmark costs, not monetary charges. Simulated time advances during actions, but the world pauses while the model generates its response. The primary scores therefore exclude the time spent waiting for AI inference.
The researchers tested six vision-language models on every core task twice, producing 40 episodes per model. Astra achieved the highest family-balanced score, 61.9%. This measure gives each of the five task families equal weight, rather than treating every task equally. Astra passed 12 of 20 tasks in each run, with its lead coming largely from emptying the dryer, which no other model completed. Excluding chores, Astra, Gemini Robotics-ER 2 and Sonnet 5 were nearly tied. No model completed every task in either the smoke-alert or leak-alert group within a run.
Across the main evaluation, 122 episodes failed. Prohibited interventions occurred in 42 failed episodes, compared with 16 involving missed required interventions; failure categories could overlap. Models sometimes shut off water after a spill or faulty reading, interrupted cooking or contacted emergency services unnecessarily. Astra, Gemini and Luna issued 39 of their 40 stove or water-main commands before obtaining any image. Restraint was not sufficient either: Gemma avoided prohibited interventions in the main comparison but frequently omitted required responses.
Follow-up experiments exposed other weaknesses. Removing images while retaining detections reduced Astra's successes from 12 to nine and Gemma's from 11 to eight in the tested run. Showing action costs reduced spending but also reduced completed tasks, sometimes because required work was left undone. Both models failed the false-doorbell task without house cameras despite retaining the robot's camera, suggesting difficulty adapting to alternative ways of gathering evidence.
Changing homes also mattered. In ten additional homes, Gemma passed 73 of 174 evaluated home–task pairs, or 42.0%. Applying its main-house outcomes to that same task mix would have yielded 60.3%. The evaluated pairs had first been completed by a scripted agent, establishing feasibility within the simulator. Gemma also made prohibited interventions in 15 additional-home episodes, despite making none in the main comparison.
These results do not establish real-world robot safety. Most experiments used one house, one robot body and two runs, with environmental variation between runs limited to the glasses task. Movement is kinematic, residents and hazards are simplified, and there was no real-robot or resident study. The checks encode prescribed policies, treating both an unnecessary intervention and a missed emergency as failures despite their different consequences. Communication quality and residents' privacy preferences remain unevaluated. The planned release includes 2,100 automatically furnished layouts, five robot bodies and 20 connected-device types, offering scope for broader testing rather than evidence that those deployment challenges are solved.
- HomeLoop
- domestic robots
- smart homes
- vision-language models
- robot safety
- Internet of Things
- simulation benchmark
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Who Triggered the Sensor? Tracking Shared Homes Without Cameras
Source published
Shared keywords: smart homes
DexDICE teaches robots from cautious and fast demonstrations
Source published
Shared keywords: robot safety
Editing a Robot Model’s Hidden Goal Without Changing Its Instructions
Source published
Shared keywords: robot safety
Can a vision-language model tell an injected concept from a picture?
Source published
Shared keywords: vision language models
AtariBench exposes AI models’ difficulty turning moving images into reliable actions
Source published
Shared keywords: vision language models