TRANSMISSION // 2611.08884v1
Privacy Depends on Who Gets the Data
Source published
An audience-aware text-sharing framework preserves more useful information in several experiments, but its gains come with narrower privacy guarantees and important deployment caveats.
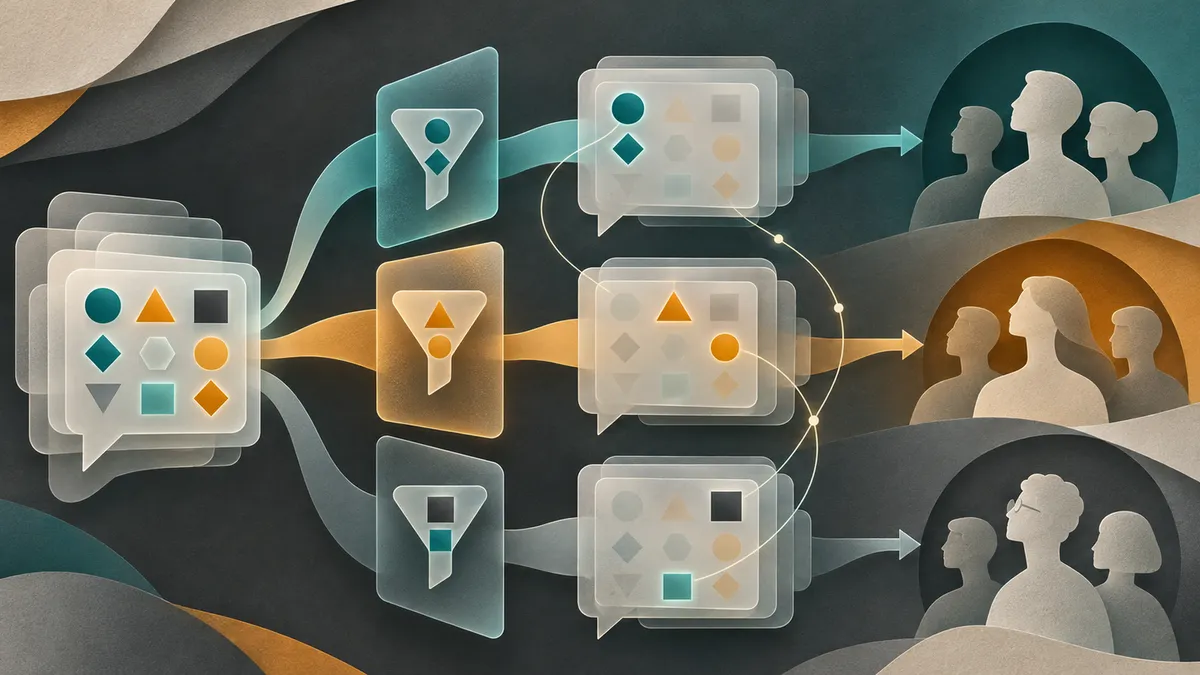
A fairness auditor and an advertising company should not necessarily receive the same details from a conversation. A new preprint explores how that distinction could shape privacy-preserving text releases.
Start with the recipient
Removing personal information from text sounds straightforward until different recipients need different details. An internal auditor might need demographic information to investigate unequal treatment. A product team might need conversation topics and outcomes, but not those demographics. Applying the same restrictions to both can erase information needed for legitimate analysis.
In the arXiv preprint Who’s Asking? Audience-Conditioned Privatization, Daniil Filienko, Anusha Bagalkotkar, Xan Vongsathorn and Sikha Pentyala propose separating two questions: what should this recipient learn, and how should everything else be protected? The supplied version does not establish peer review.
Their framework, Ext-Classify-Priv, uses contextual integrity: the idea that appropriate information sharing depends on the recipient, purpose and norms of the original interaction. It produces different releases for different audiences rather than one universally restricted dataset.
Extract, classify, protect
First, the system identifies a schema: categories such as age, occupation, conversation outcome or purchase price. A locally hosted language model extracts category values from each text. In the main experiments, Reddit and bioRxiv use existing schemas; the proprietary real-estate schema comes from a local model and human verification.
Next, another language model considers the schema and release context, marking each attribute private or public for that audience. Here, “public” means permitted for this particular recipient, not safe to publish everywhere. This classifier sees attribute names and context, not the underlying records. The authors treat its decisions as proposals requiring expert review in sensitive settings; a legal expert reviewed three real-estate audience configurations.
Finally, one of two mechanisms prepares the release.
SDG-CI generates synthetic text. It copies permitted attributes into a table, learns noisy statistical relationships involving protected attributes, and samples replacement private values. A language model turns these rows into candidate texts. Real records then vote for similar candidates, with noise added to the vote totals, to improve the generated collection’s resemblance to the source.
ANON-CI rewrites actual records. A language model repeatedly generalizes revealing passages. Other model roles try to infer protected attributes and check whether permitted information and the downstream task label remain recoverable. This is empirical protection, not a mathematical privacy guarantee. Importantly, if no rewrite passes the privacy check, the algorithm still releases the version with the fewest detected leaks.
Better resemblance, uneven practical gains
The researchers evaluate synthetic Reddit comments with synthetic personal attributes, public bioRxiv material, and 1,000 proprietary conversations between homebuyers and real-estate agents. They measure text-distribution similarity, attribute inference, downstream classification and, on Reddit, a male–female classification accuracy gap.
At a reported privacy parameter of epsilon equals one, SDG-CI improves Reddit’s MAUVE similarity score over MAPLE’s 0.350 for all three audiences: 0.479 for a recommendation-system vendor, 0.546 for re-sharing, and 0.400 for an advertiser. Larger gains accompany permission to retain more attributes. MAUVE measures distributional resemblance; it is not a privacy score or proof that individual statements are accurate.
On bioRxiv, SDG-CI raises MAUVE from MAPLE’s 0.097 to 0.420. A classifier trained on generated texts and tested on real texts reaches 74.6% accuracy, versus MAPLE’s 55.6%. However, another synthetic baseline, Aug-PE, reaches 81.0% despite substantially worse MAUVE. Better resemblance does not automatically mean better performance on a particular task.
The real-estate anonymization result makes the same distinction for privacy. ANON-CI reaches MAUVE 0.959, compared with RUPTA’s 0.698, but its measured attribute-inference leakage is slightly higher: 0.400 versus 0.395. On bioRxiv, ANON-CI’s downstream accuracy is also substantially below RUPTA’s. The findings do not establish across-the-board superiority, and every reported experiment is a single run.
What the guarantee leaves exposed
SDG-CI uses Feature-DP, which bounds what a release reveals beyond the attributes deliberately disclosed. That is narrower than standard record-level differential privacy. Matching epsilon values across these methods does not match their protection: the audience-aware system intentionally protects less information.
Permitted attributes can identify someone in combination or reveal protected facts through correlations. Feature-DP does not protect dataset membership, and the privacy unit is one text, not one person contributing multiple texts. The analysis also assumes audiences receive only their own releases; sharing releases can expose their combined permitted attributes, while repeated releases accumulate privacy loss.
A further caveat concerns the implementation’s formal coverage. The proof treats schemas and certain value sets as fixed or appropriately privatized. The experimental pipeline derives them from data without differential privacy, and mapping coarse categories back to observed specific values falls outside the guarantee. The authors explicitly acknowledge these exclusions.
The contribution is therefore a framework for negotiating usefulness against a recipient-specific privacy boundary—not a way to make confidential text universally safe. Its value depends on whether that boundary is justified, reviewed and enforced.
- contextual integrity
- text privacy
- Feature-DP
- synthetic data
- anonymization
- audience-conditioned privatization
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI claims-analysis preprint tests policy citations and privacy safeguards on synthetic data
Source published
Shared keywords: synthetic data
When rearranging the answers changes an AI’s choice
Source published
Shared keywords: synthetic data
Simulated city tests how AI investigators handle incomplete evidence
Source published
Shared keywords: synthetic data
A Search for Training Data With Unexpected Side Effects
Source published
Shared keywords: synthetic data
Merging Salesforce Systems Without Hiding the Data Problems
Source published
Shared keywords: synthetic data