TRANSMISSION // 2611.08864v1
Better scheduling could reduce waiting in language-model reinforcement learning
Source published
A preprint describes a scheduler that groups prompts by expected response length, then balances their dispatch to keep training supplied with examples. Controlled comparisons report a 10.9% reduction in average iteration time from scheduling itself; larger gains reflect the complete system.
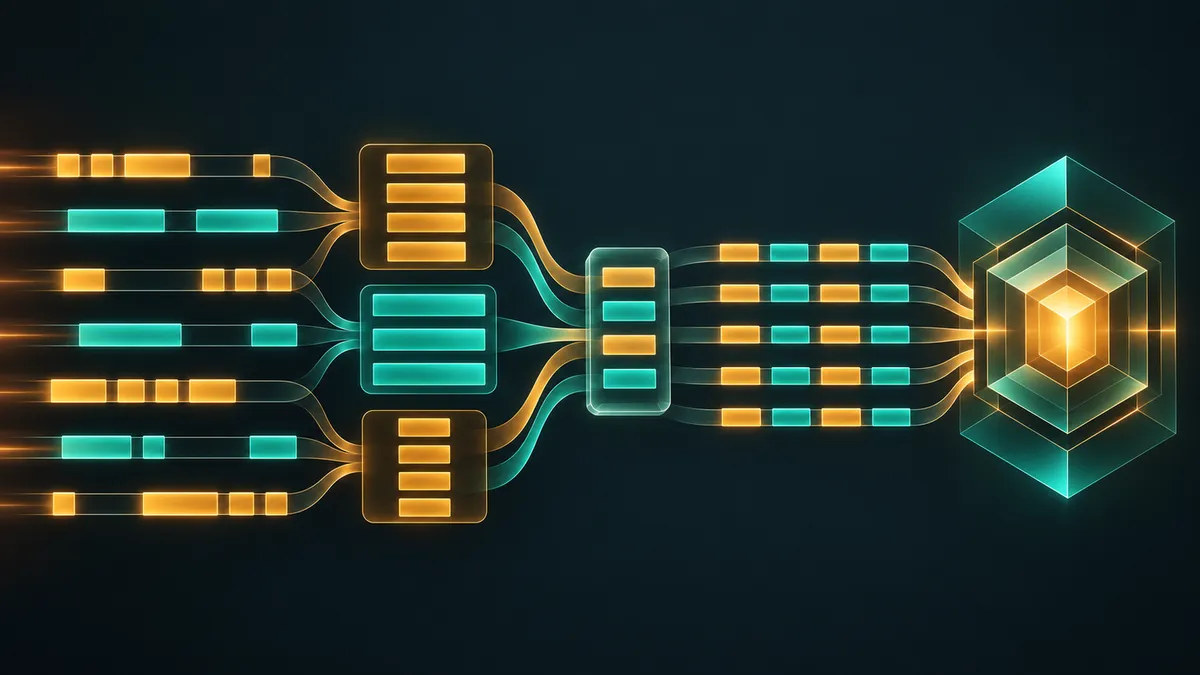
Generating practice answers can become a bottleneck when language models learn through reinforcement learning. The Adaptive Scheduling Pipeline aims to make that work more efficient without letting the training process run too far ahead of the models producing its examples.
The problem is not just generating faster
Reinforcement learning for language models involves repeatedly generating responses, scoring them and updating the model. Long answers can make generation the slowest part of this cycle. Separating generation from training lets both proceed concurrently, but introduces another problem: keeping the trainer supplied with useful examples at a steady rate.
In a preprint, Salah Chikhi and colleagues propose the Adaptive Scheduling Pipeline, or ASP. Its central question is whether organizing generation work before training begins can reduce wasted capacity inside generation workers while preventing uneven deliveries to the trainer.
The distinction matters because an arrangement that helps individual workers can hurt the overall pipeline. Grouping short tasks together may make those groups efficient, yet sending all short groups first can produce an early flood of examples followed by a shortage.
Three kinds of wasted capacity
The researchers describe three sources of underutilization as “bubbles.”
Padding bubbles arise when responses of different lengths share a generation minibatch: shorter responses finish while the worker remains occupied by longer ones. Skewness bubbles reflect the particularly long answers that leave only a few sequences still generating near the end. In this implementation, completed samples are returned only after their entire minibatch finishes.
Sorting prompts by expected answer length helps address these local inefficiencies. But it creates what the authors call sorting bubbles. Short minibatches finish quickly at first; progressively longer ones then slow deliveries. The queue holding completed examples can fill and later drain, leaving the trainer waiting.
ASP therefore separates two decisions: which prompts belong together, and when their minibatches should be dispatched.
Planning the work in advance
The pipeline first predicts response lengths using a smaller language model fine-tuned on 4,000 prompt–length pairs. It sorts prompts by those predictions, then uses dynamic programming to choose minibatch boundaries. Allowing small variations in minibatch size helps avoid grouping prompts across large jumps in expected length.
Next, it rearranges the resulting minibatches into groups with similar total predicted output lengths. A search method called simulated annealing swaps minibatches to reduce differences between group loads. Short and long minibatches can therefore be interspersed without mixing dissimilar prompts inside each minibatch.
These scheduling decisions happen offline, before training. During execution, multiple generation workers feed a controlled queue. If too many examples accumulate, the system pauses new generation work until the trainer catches up.
Workers also receive updated model weights. They finish their current minibatch before reloading, avoiding a simultaneous stop across all workers. This creates a tradeoff: continuous generation means some examples come from slightly older model versions.
What the experiments found
The team implemented ASP within MindSpeed-RL and tested Qwen3 models on Ascend 910B3 neural processing units. In comparisons using 64 processors per system, average iteration times were 215.2 seconds for ASP versus 536.7 for verl and 927 for MindSpeed-RL on Qwen3-30B-A3B. Results on Qwen3-32B also favored ASP.
Those large differences measure complete systems, not scheduling alone. Execution architecture, resource layouts and implementation also differ. In a separate comparison holding the ASP architecture fixed, enabling scheduling reduced average iteration time from 238 to 212 seconds, a 10.9% improvement over 200 iterations. Reported end-to-end throughput rose from 47 to 58 generated tokens per second per processor.
A staged experiment using real Qwen3-8B generation with simulated training times helped explain the mechanism. Simply sorting by predicted length made iteration times increase over the run. Balanced ordering retained the local batching benefits while producing steadier timings. Its average iteration time was 178 seconds, compared with 188 seconds without scheduling.
Where the evidence stops
Learning stability received a narrower test: 30 training iterations on maze problems. ASP showed no visible degradation relative to MindSpeed-RL at an estimated lag of approximately 3.3 trainer steps. That supports the measured operating point, not a general guarantee for longer runs or larger delays.
The scheduler also depends on useful length predictions. With poor predictions, sorting’s local efficiency benefit disappeared or became slightly negative in sensitivity tests. The fixed predictor may need updating when tasks or model behavior change substantially.
Experiments stopped at 128 Ascend processors, and several other asynchronous systems were not directly benchmarked. ASP also assumes prompts are known beforehand, limiting direct application to streaming workloads. The preprint therefore offers evidence for coordinated scheduling under specific conditions—not proof of universal speedups or improved model intelligence.
- reinforcement learning
- large language models
- Adaptive Scheduling Pipeline
- asynchronous training
- output-length prediction
- workload scheduling
- policy lag
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
MinPRO tests a prefix-aware approach to steadier language-model training
Source published
Shared keywords: large language models, reinforcement learning
Language models help design rewards for two-stage payment fraud detection
Source published
Shared keywords: large language models, reinforcement learning
Evolving Instructions Alongside AI Training Improves Benchmark Results
Source published
Shared keywords: large language models, reinforcement learning
AI-designed rewards help a fraud detector learn from blocked payments
Source published
Shared keywords: large language models, reinforcement learning
When an AI Queries a Database, How Does It Know What You Mean?
Source published
Shared keywords: large language models, reinforcement learning