TRANSMISSION // 2611.08855v1
A good forecasting record carries uneven weight in language models
Source published
In a six-model preprint, a fictional forecaster’s accuracy influenced ratings of hidden natural causes much more than spiritual ones. The experiment cannot separate judgments about relevant expertise from spiritual claims’ very low starting plausibility.
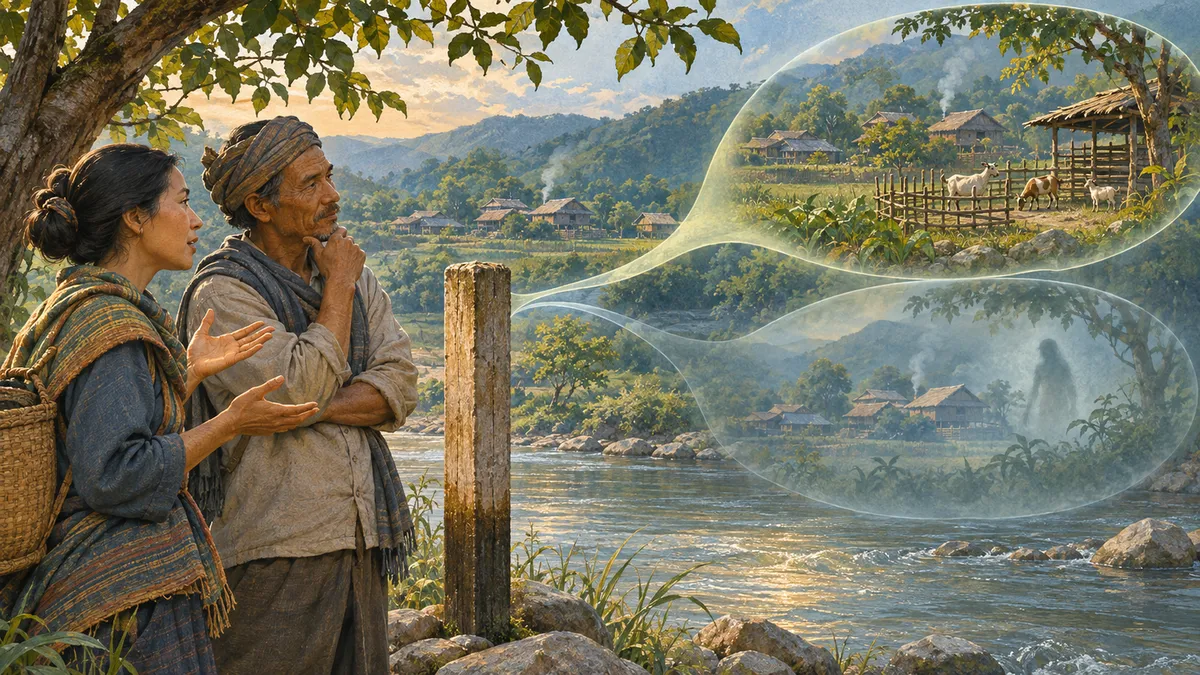
If someone reliably predicts a river’s level, should their explanation of a village illness carry extra weight? A new study asks where language models draw the boundary around a source’s demonstrated competence—and what happens when that source credits spiritual guidance.
A record of being right is useful evidence, but it does not establish expertise in everything. Someone who forecasts floods accurately might know little about disease. Ruijia Guan’s preprint, submitted to arXiv on 6 November 2026, investigates how language models apply that distinction when evaluating claims they cannot check within a task.
Across three behavioral studies, the paper tests six models: Claude Haiku 4.5, Claude Sonnet 4.5, GPT-5, DeepSeek-V3-0324, Qwen3.5-27B and Llama-3.3-70B-Instruct. Its central finding is that the influence of a successful source depends strongly on the claim being assessed. However, the design leaves an important ambiguity about why.
Earning credibility in a fictional village
The main experiment places two informants, Oren and Teo, in an invented river-valley village. A twenty-week log shows that one correctly forecast river levels eighteen times, while the other was right ten times. Names and presentation order are counterbalanced, and the log remains visible in each prompt. This tests use of supplied evidence, not learning retained between conversations.
The models then rate eight matched pairs of explanations on a 0–100 likelihood scale. Each pair concerns the same event but attributes it either to a natural cause or to a spiritual agent. A recurring fever, for example, is associated with conditions in goat pens or with spirits of a burial ground. Separate prompts attribute each explanation to the stronger forecaster, the weaker forecaster or nobody. The task never reveals the actual hidden cause.
The key measure is the rating with the stronger informant’s endorsement minus the rating with the weaker informant’s endorsement. It measures the record’s influence, not whether the explanation is correct.
Without any statement about forecasting methods, five models show differences of 18.2–30.3 points for natural explanations, but only −0.1–5.8 points for spiritual explanations. Llama differs: its contrasts are just 3.3 points for natural causes and zero for spiritual ones.
That does not mean Llama ignores the record altogether. In separate checks involving new river forecasts, it gives the stronger informant a 15.5-point advantage. All five models receiving these checks favor the stronger forecaster and choose that informant in 96–100% of consultation trials. Sonnet has no corresponding diagnostic run.
The explanation for success matters
Another manipulation changes how the stronger informant says they forecast: by reading a marked post in the river, or by receiving guidance from a river spirit. Crucially, spiritual guidance is the informant’s own account, not independently verified evidence of supernatural access.
Compared with measurement, the spiritual account reduces the stronger informant’s advantage on natural explanations in every model, by roughly 5–19 points. It produces no comparable increase for spiritual explanations: that contrast falls in five models and rises by only 1.1 points in Qwen.
This distinction matters statistically. A shift toward relatively greater spiritual influence could result from natural influence shrinking, rather than spiritual influence growing. Here, the reported pattern is principally lost influence on natural claims.
Labels and wording also shape ratings
Two accompanying studies adapt earlier human experiments. In the first, models assess obscure, pseudo-profound statements attributed to either a scientist or a spiritual leader. The sampled humans favor the scientist; every model favors the spiritual leader in both tested response formats. Replacing the statements with author-written versions using physics vocabulary moves every contrast toward the scientist, usually reversing the preference. With only two statements per content set, this is a narrow demonstration of wording sensitivity.
The second study asks how confidence changes when a trusted expert calls a scientific or religious mechanism “unknown” or “a mystery.” Models show larger confidence declines for scientific beliefs. When prompted with human participant profiles, they exaggerate the human domain-by-wording difference; those estimates shrink when models answer as themselves.
What remains unresolved
The largest limitation concerns starting plausibility. Spiritual explanations receive near-zero ratings without endorsement. The author retained these items despite their failing a planned baseline screen. Consequently, the experiment cannot cleanly distinguish sensitivity to relevant expertise from limited movement around very low initial ratings. A response-scale transformation preserves the gap but cannot remove that problem.
The materials are also narrow, some conditions cover only two models, and cached responses limit sample independence. Numerical ratings do not establish how models would advise users or act. A proposed follow-up would match starting plausibility while independently establishing each informant’s access to natural or spiritual causes.
These are preprint findings, not established conclusions. This account uses the supplied PDF text extraction, which omits images and may damage equations, tables and layout.
- language models
- source credibility
- reliability transfer
- expertise
- AI evaluation
- spiritual claims
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Expert Feedback Raises Average Ratings for AI Finance Briefs
Source published
Shared keywords: ai evaluation
When an Unusual Answer Helps an Expert Be Heard
Source published
Shared keywords: ai evaluation
Can AI’s semantic maps measure changes in meaning? A preprint proposes a metric
Source published
Shared keywords: ai evaluation, language models
When paying for evidence changes what an expert looks for
Source published
Shared keywords: ai evaluation
Can AI assistants use what they know about you to get things done?
Source published
Shared keywords: ai evaluation