TRANSMISSION // 2611.08790v1
SteerGR shifts game recommendations by editing a model’s internal features
Source published
An arXiv preprint reports that sparse autoencoders can help steer game recommendations toward selected play activities without retraining the recommender. Offline tests show controllable shifts, but stronger interventions can substantially reduce next-game prediction accuracy.
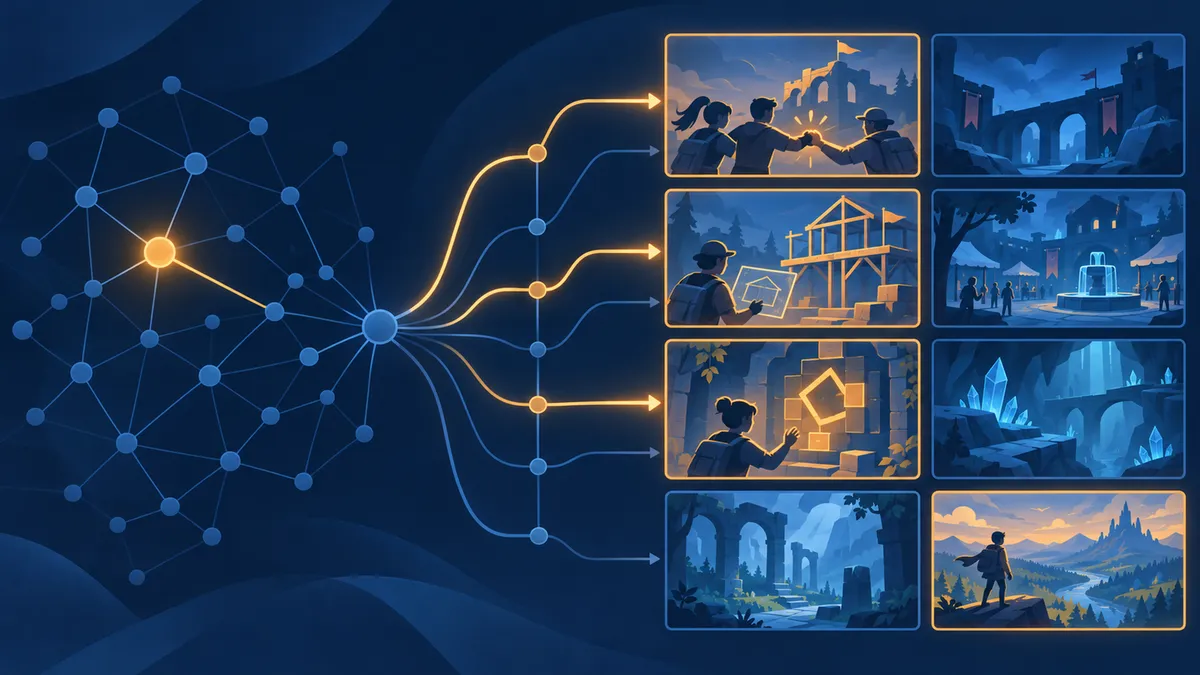
A player’s history does not necessarily capture what they want to try next. SteerGR explores whether a trained game recommender can be redirected toward goals such as collaboration or puzzle-solving by modifying selected internal features.
Turning play goals into model controls
Generative recommenders predict game identifiers from a player’s interaction history. SteerGR, developed by researchers at Sungkyunkwan University and Roblox, investigates how to redirect those predictions toward particular activities while leaving the recommender’s learned parameters unchanged. The work was posted as an arXiv preprint on November 5, 2026; that status does not establish peer review.
The researchers tested twelve play concepts, including collaborating with others, managing resources, solving puzzles and defending against threats. These describe activities rather than conventional genres. The central question was whether changing a selected internal feature could increase or decrease the proportion of recommended games associated with a target concept.
How the method works
First, a language model generated the concepts and their definitions. A text-embedding model converted those definitions and game descriptions into numerical representations. Similarity scores, standardized separately for each concept, determined which concept label each game received. Although a game could plausibly support several activities, the recommendation evaluation assigned each scored game only its highest-scoring concept.
The team then trained a sparse autoencoder on hidden states from each frozen recommender. This additional model represents those states using a larger collection of features, with only a small number active at once. The final autoencoders contained 3,072 features, retaining up to 32 active features for one recommender and 64 for the other. Avoiding recommender retraining therefore did not mean avoiding all additional training.
To find candidate controls, the researchers scored users’ twenty most recent interactions for each concept. They compared internal feature responses between users in the highest and lowest scoring quarters. Crucially, they did not simply choose the feature most strongly associated with a concept. They tested candidate interventions on a separate validation group and selected the feature that most increased the target concept’s recommendation share.
During recommendation, SteerGR amplified or suppressed that feature and added the resulting decoded change to the original hidden state. This preserved the original state’s reconstruction residual rather than replacing it with an autoencoder reconstruction. Intervention strength was adjustable.
What the experiments found
The study used proprietary game-interaction logs from August 2026. It evaluated two six-layer Transformer recommenders: an Atomic ID model, described as deployed for game discovery, and a Semantic ID variant trained in the same pipeline. Their catalogs contained about 40,000 and 100,000 games, respectively. Final evaluation used approximately 6,300 and 6,900 held-out users, separate from training, validation and feature discovery.
The main control measure was the fraction of the top ten recommendations carrying the target concept label. In the feature-selection comparison, Atomic ID’s target share rose from 5.75% without intervention to 7.95% with amplification and fell to 4.27% with suppression. Semantic ID changed from 6.70% to 7.46% and 6.14%, respectively. These are recommendation shares, not percentages of users reporting satisfaction.
Selecting features by their measured steering effect worked better than selecting them solely by their association with a concept. Random features with similar activation frequency produced little change.
At the strongest tested setting, amplification increased target share for all twelve concepts in both models. Average relative increases were 113.6% for Atomic ID and 24.6% for Semantic ID. Suppression generally worked in the opposite direction, but not universally: exploration in Atomic ID and tactical activity in Semantic ID were exceptions.
Control comes with costs and uncertainties
Prediction accuracy depended on whose next game was being evaluated. For users whose observed next game matched the target concept, amplification improved Recall@10 by 2.4% and 2.3% in the two models. This metric asks whether the actual next game appeared among ten recommendations. These users were identified from recorded behavior, not from an experiment in which players explicitly requested a discovery goal.
Stronger control could harm broader accuracy. For four examined Atomic ID concepts, overall ranking accuracy fell by 7.3–42.9% at the strongest amplification setting. Editing more features also increased changes to unrelated concepts.
The findings remain offline evidence from one platform’s proprietary data. Concept labels came from descriptions and automated models; validation against two other language models was not human confirmation. The study did not establish live-user satisfaction, long-term discovery benefits or reliable content exclusion. It demonstrates adjustable recommendation shifts, not unrestricted or cost-free control.
- generative recommendation
- sparse autoencoders
- SteerGR
- game discovery
- controllable recommendation
- model interpretability
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
What Internal Features Reveal About a Financial AI’s Responses
Source published
Shared keywords: sparse autoencoders
Can One Token per Creator Improve Recommendations?
Source published
Shared keywords: generative recommendation
Language models show broad emotion patterns while retaining finer distinctions
Source published
Shared keywords: model interpretability
Inside a neutrino AI, useful physics can sit unused
Source published
Shared keywords: sparse autoencoders
A Financial Brain Scan for AI—and a Warning About Its Explanations
Source published
Shared keywords: sparse autoencoders