TRANSMISSION // 2611.08768v1
Conflux puts permission checks outside the language model
Source published
Conflux proposes limiting an AI agent’s actions to permissions shared by every principal whose information influenced them. Its conditional proof and finite-model checks support a narrow security claim, not demonstrated protection in deployment.
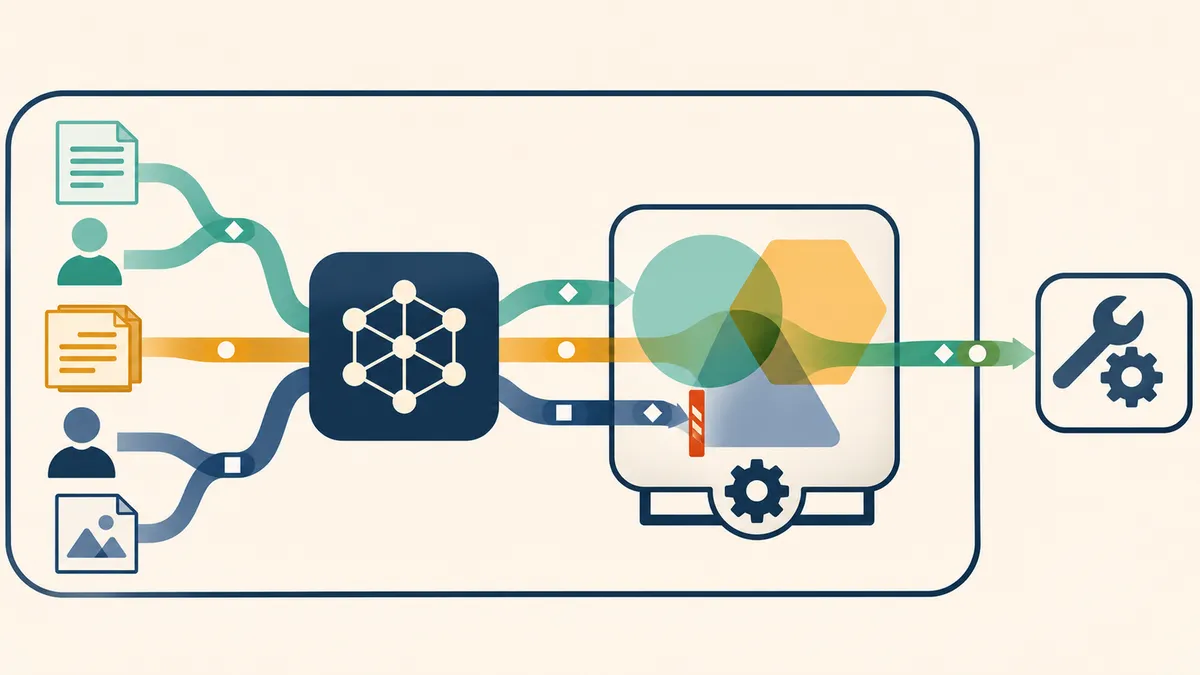
An AI assistant may have permission to update customer records, while the author of a report it reads does not. Conflux asks how to stop that report from borrowing the assistant’s authority—without relying on the model to recognise an attack.
From suspicious text to borrowed authority
AI agents increasingly read documents and invoke tools on users’ behalf. Prompt injection exploits that combination: information encountered during a task can redirect the model toward an attacker’s objective.
In a November 5 arXiv preprint, University of Oxford researchers Raya Buckley and Christian Schroeder de Witt propose Conflux, an architecture that shifts the security question. Rather than asking whether text is malicious, it asks whether everyone whose information influenced an action has permission to perform it. Enforcement sits outside the language model, within Conflux’s agent architecture and application mediation service. The paper presents a conditional mathematical result and partial experiments, not an established deployment guarantee.
The distinction matters because detecting an instruction hidden in ordinary content requires interpreting language. Checking an authenticated identity against an organisation’s access-control system is a different decision, enforceable without relying on model judgement.
Every contributor adds a constraint
Conflux’s core mechanism, called ITES, tracks a principal context: the identities associated with information entering an execution. A principal can be a user or another agent. Documents and tool outputs contribute through their recorded authorship and provenance.
For an external action, the system combines that context with the provenance of its arguments. It permits the action only if the resulting context is known, non-empty, and every principal in it has the required permission. Adding another contributor can therefore preserve or reduce authority, never increase it.
Consider the paper’s customer-record example. Ava asks an assistant to update a remediation status using Ben’s report. Because Ben supplies the status value, both Ava and Ben must be authorised for the update. The report does not have to look suspicious to trigger the check.
This rule depends on preserving provenance through copying and transformation. If attacker-authored material becomes a new document labelled only with a trusted employee’s identity, the attacker’s contribution disappears. The paper explicitly assumes a provenance store that prevents this laundering.
Conflux also separates authorisation from read access, argument restrictions, visibility and consent. These checks can impose additional denials; consent cannot create missing authority. Scoped delegation is described and checked in finite models but is not enabled in the runtime.
What the proof actually covers
The authors prove authority confinement under specified assumptions: every covered effect must pass through enforcement; influence records must be complete; the implementation must follow the intersection rule; and permission checks must remain current and bound to the action actually dispatched.
These are substantial conditions, not properties established automatically by the proof. In particular, the represented provenance covers value influence—information supplying inputs and arguments—but not control influence, such as an untrusted document causing the model to choose a different tool or branch while retaining trusted argument values. Such control-only attacks remain outside the demonstrated guarantee.
The result also does not establish confidentiality, task completion or correct organisational policy. An authorised action can still be unwanted. Messages fall outside the theorem, and the authors identify exact binding at the effect sink and production isolation as unfinished engineering obligations.
Testing the defence model, not just the chatbot
The paper introduces two evaluators. SLED explores a declared finite defence model without running a language model, allowing any proposal admitted by its interface. SLED-V checks a structured intermediate representation using a reference interpreter and solver-backed methods.
One SLED experiment expanded the maximum final proposal batch from three to six primitive actions across five small configurations. All tested finite state spaces were exhausted without a violation. That shows the smaller batch cap was not responsible for those particular passing results; it does not establish safety beyond the tested models.
Larger environment experiments illustrate the scaling problem: only three of twelve environments completed exploration at depth three. Runs stopped at a time limit provide partial coverage, not completed security checks.
For SLED-V, the reference interpreter and two solver backends agreed on all eleven tested bounded variants, including refuted variants. Agreement supports consistency of the tested encodings, not conformance of a deployed implementation. The reference security model itself contains just one principal, one action and one permission bit.
The benchmark gap
The most important experimental caveat concerns AgentDojo. Across the reported 14-billion-parameter model runs, 19 of 132 cells recorded utility success. But no recorded cell executed an effect call: the adapter exposed read tools. Consequently, the absence of recorded security violations does not demonstrate that Conflux stopped an unauthorised effect. Smaller-model runs recorded zero utility success.
The practical contribution is therefore an explicit authority rule and ways to interrogate its assumptions. Whether an agent can preserve useful workflows while enforcing that rule across real effects, complete influence tracking and changing policies remains unproven.
- AI agent security
- Conflux
- privilege escalation
- prompt injection
- access control
- provenance
- formal verification
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
LatentTriad screens AI agent skills before they act
Source published
Shared keywords: ai agent security, prompt injection
MemoryDojo tests how poisoned AI memories influence later tasks
Source published
Shared keywords: ai agent security
A Signed AI Tool Can Leak Data Through an Approved Service
Source published
Shared keywords: ai agent security
When AI agents change, should their permissions change too?
Source published
Shared keywords: access control
Proving GPU Kernels Correct, Within the Limits of a Model
Source published
Shared keywords: formal verification