TRANSMISSION // 2611.08763v1
CrowdDirector steers virtual crowds without querying a language model at every update
Source published
An arXiv preprint describes a system that translates new instructions once, checks them against a simulated scene, and uses a graph neural network for subsequent decisions. It outperformed handwritten rules on instruction following, but remained imperfect and trailed repeated language-model control on response agreement.
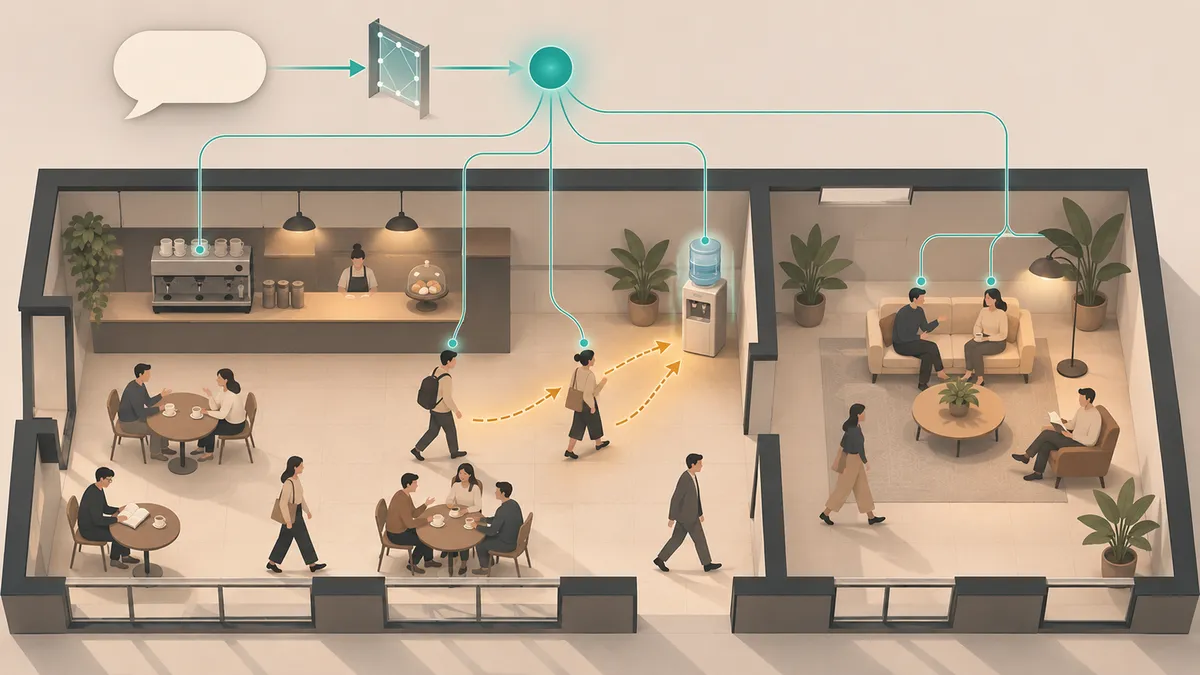
Telling virtual visitors to avoid a broken coffee machine sounds straightforward. Making the right characters respond, while everyone else continues normally, is harder. CrowdDirector separates understanding that request from repeatedly deciding what each simulated person should do.
Interpret once, decide locally
CrowdDirector asks whether natural-language control of a running crowd simulation needs a large language model at every decision update. Handwritten rules are efficient but cover only anticipated situations. Repeated language-model queries offer flexibility, but add latency and API costs throughout a session.
In an arXiv preprint submitted on November 5, 2026, Xiaohan Sun and colleagues describe a different division of labour: use a language model when an instruction arrives or changes, then let a locally running graph neural network guide subsequent behaviour. The manuscript also carries conference information for MIG ’26.
The system controls simulated characters, not real crowds. Its implementation uses a Unity 2D environment, with a separate Python process maintaining symbolic state and running the learned policy.
Checking what the scene supports
A language model first translates a request into structured operations. For a broken coffee machine, this might include disabling its ability to provide drinks.
A programmatic validator then checks referenced objects, groups, locations and actions against the live scene. It distinguishes executable requests from partially executable, unsupported, ambiguous or invalid ones. A partially executable request changes the simulation only if the user explicitly accepts the supported portion.
Accepted instructions become persistent directives describing scene changes, scope and duration. They remain available to later decisions without further language inference. A directive can therefore influence characters who become thirsty after the original request, rather than only those already waiting for coffee.
This validation checks whether a request fits the simulator’s capabilities. It does not guarantee that every subsequent character decision follows the user’s intention.
Learning responses from simulated outcomes
At each decision update, the system represents agents, objects, zones, groups and active directives as a graph. Connections describe relationships such as group membership and which entities an operation concerns.
A candidate generator lists up to 64 possible actions for each agent. Structurally impossible choices are excluded, while temporary conditions, such as a disabled machine, are represented in candidate features. A three-layer graph neural network scores the choices. Unity handles navigation, collision avoidance, interactions and animation; characters retain actions until completion, failure or a directive change.
Training happens offline. Short simulated rollouts estimate the consequences of alternative actions, including need relief, travel and contention. For instruction-related decisions, a language model also ranks existing candidates. Valid language rankings and rollout-derived distributions receive equal weight; missing or invalid rankings leave the rollout labels unchanged.
The generated corpus contains 2,776 worlds and 73,606 agent decisions, divided among training, checkpoint selection and held-out combinations. The language model guides learning but cannot add candidates through its rankings.
Better than rules, not perfect
The evaluation included 15 volunteers judging scene feasibility, affected agents and preferred responses. A separate behavioural benchmark contained 100 scenarios, each run under 10 initializations.
The scene validator agreed with majority participant feasibility judgments in 83% of scenarios, compared with 47% for the language model’s self-assessment. However, the reported confidence intervals were wide and overlapping, so the size of that advantage should not be treated as conclusive.
On the matched behavioural comparison, CrowdDirector agreed with participants’ preferred responses in 61.1% of cases. Handwritten rules achieved 23.3%, while language-model control at every update achieved 66.7%. Agreement on which agents should respond followed the same ordering.
Instruction following remained incomplete. CrowdDirector’s prohibited-response rate was 21.1%, compared with 36.8% for rules and 21.7% for repeated language-model control. These were physically executable actions that the instruction ruled out—not evidence of real-world safety performance.
Where the savings appear
For 20-agent worlds on the reported CPU setup, complete decision updates took 20.5 milliseconds with CrowdDirector versus 3,880 milliseconds with whole-crowd language-model control: about a 189-fold difference.
For an example session containing five instructions and 600 updates, the authors counted six API calls versus 606, including initial scene generation. Estimated API costs were $0.03 versus $2.30. Those figures concern the reported configuration and pricing, not total computing or training costs.
What remains unproven
The system supports only its predefined operation library, and evaluation was limited to 2D scenes and a small participant study. It cannot invent arbitrary new interactions from language.
The policy was trained on crowds of 8–40 agents. Timing experiments reached 5,000 agents, but demonstrated computational scaling, not preserved behavioural quality at that size. The evidence supports a bounded trade-off: stronger instruction following than the tested rules, with much less recurring language inference than the tested per-update alternative.
- CrowdDirector
- crowd simulation
- natural-language control
- graph neural networks
- virtual agents
- Unity
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
SIMBAD tests when traffic forecasts should trust the past
Source published
Shared keywords: graph neural networks
A graph-learning method updates its view as connections appear
Source published
Shared keywords: graph neural networks
A New Geometry for Graphs Whose Neighbors Differ
Source published
Shared keywords: graph neural networks
Seizure-detection AI learns to handle different electrode layouts
Source published
Shared keywords: graph neural networks
Forecasting a changing network by predicting its shape first
Source published
Shared keywords: graph neural networks