TRANSMISSION // 2611.08753v1
Random Symbolic Boosting builds predictive formulas without evolutionary search
Source published
A preprint introduces a method that combines randomly generated mathematical expressions through boosting. It reports strong regression results and competitive classification performance, but large formulas, differing benchmark hardware and unavailable source code limit the conclusions.
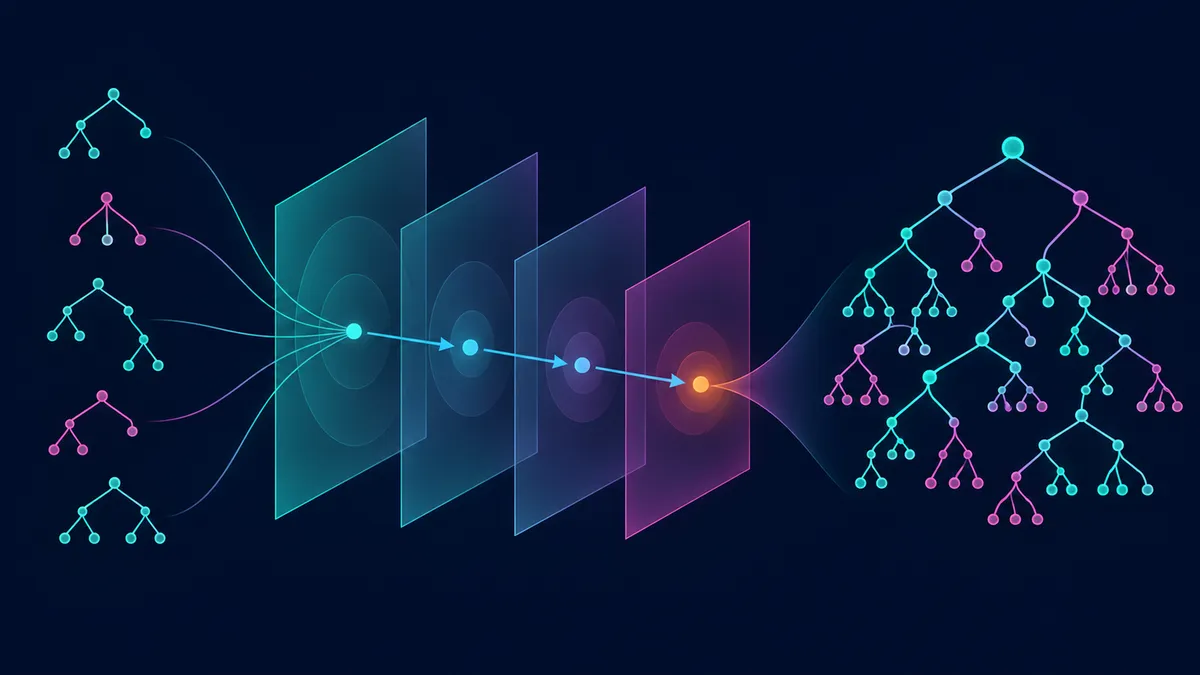
Finding a mathematical formula that predicts data can require an expensive search through possible expressions. Random Symbolic Boosting takes a different route: generate expressions randomly, then fit their contributions to the model’s remaining errors. The reported results suggest a promising accuracy–speed trade-off, though an explicit formula is not necessarily an understandable one.
Replacing evolution with repeated fitting
Symbolic regression seeks mathematical expressions that predict an outcome from input variables. Its appeal is that the resulting calculation is explicit, rather than hidden inside a less directly interpretable model. Many approaches use genetic programming, repeatedly selecting and modifying candidate expressions across generations. That structural search can be computationally expensive.
José R. Ortega, José Manuel Muñoz Contreras and Leonardo Trujillo propose an alternative called Random Symbolic Boosting, or RSB. Their paper was submitted to arXiv on November 5, 2026. The supplied version is a preprint; its record does not identify an accepted journal publication.
RSB generates fresh batches of random mathematical expressions and combines them through boosting: successive additions address errors left by the existing model. It avoids generational evolution, but it does not eliminate optimization. Instead, it concentrates optimization on the numerical weights assigned to those expressions.
How the geometry works
Each expression is represented as a syntax tree, a branching arrangement of mathematical operations and inputs. Evaluating a tree on every training example produces a list of outputs. The researchers treat that list as a vector—a direction in a space with one dimension per example.
At each boosting step, RSB generates a population of trees, evaluates them and fits a weighted combination to the current residuals. For regression, residuals are the differences between observed and predicted values. For binary classification, they are the differences between labels and predicted probabilities. The weighted update is added to the model, scaled by a learning rate.
The fitting framework is Elastic Net, which includes ordinary least squares, Ridge and Lasso as special cases. These options differ in how they penalize coefficients. The main benchmark experiments use Ridge regularization, which discourages large weights.
The paper provides a mathematical training-loss guarantee for the unregularized, ordinary-least-squares case. Provided an update is nonzero, regression residuals shrink for learning rates between zero and two. For binary classification, the authors derive a sufficient condition for decreasing log-loss with learning rates between zero and eight. These are training guarantees, not guarantees of better predictions on unseen data. The stated proofs also do not directly cover the regularized configuration used in the benchmarks or the multiclass extension.
Deciding when to stop
RSB monitors the angle between prediction and target vectors on a separate validation set. An initial calibration period establishes a tolerance for subsequent angular changes. Training stops when progress becomes sufficiently small or the angle shows sustained deterioration. In the latter case, the algorithm restores the model with the lowest previous validation error.
An angle has a bounded range regardless of the target’s numerical scale. However, that does not make the complete stopping procedure parameter-free: it includes calibration windows, patience settings and thresholds. The experiments use different window and patience settings for multiclass classification than for binary classification.
A six-dataset comparison illustrates the trade-off. Ridge with angle-based stopping achieved an aggregate median test R² of 0.970, compared with 0.973 without stopping, while reducing expression nodes by about 65%. Those figures summarize medians across datasets and repeated runs. Compared directly with an otherwise matching RMSE-based stopping procedure, angle monitoring generally favored accuracy, while RMSE monitoring favored smaller models and shorter training.
What the benchmarks showed
The regression evaluation used 122 SRBench problems: 62 synthetic and 60 real-world datasets. RSB ranked third overall on the reported predictive-performance measure, first on the real-world subset and fourth in training-time ranking.
It also appeared on the accuracy–time Pareto frontier. In this comparison, that means no competing method ranked better on both dimensions simultaneously. It does not mean RSB was the most accurate or fastest method individually. The authors’ corrected statistical comparisons found no significant accuracy difference between RSB and several competitors, including XGBoost and LightGBM; that finding does not establish equivalence.
For classification, the researchers tested 120 binary and 80 multiclass TALENT problems against results from 31 baseline algorithms. RSB ranked 11th for binary classification and 13th for multiclass classification. These results support competitiveness, rather than leadership across classification tasks.
Explicit does not necessarily mean interpretable
Model size is the clearest limitation. RSB ranked third from last in the regression model-size comparison. Adding many weighted expressions can produce a formula that is available for inspection but difficult to understand. The authors propose post-training symbolic simplification as future work, not a demonstrated solution.
The benchmark comparisons also used previously published baseline results rather than rerunning everything on identical hardware. SRBench baselines and RSB ran on different processors; the paper says TALENT’s reference hardware was unspecified. That limits precise speed comparisons.
Finally, the RSB source code was not publicly available with this version. The authors promise release upon acceptance. Until then, independent reproduction remains constrained. The study presents encouraging benchmark evidence for replacing evolutionary expression search with random generation and repeated fitting, while leaving practical interpretability and reproducibility unresolved.
- symbolic regression
- Random Symbolic Boosting
- boosting
- genetic programming
- Ridge regression
- early stopping
- interpretable machine learning
- SRBench
- TALENT
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Simpler building blocks for inspectable predictions
Source published
Shared keywords: interpretable machine learning
AI-generated rules patch a fraud detector without retraining it
Source published
Shared keywords: interpretable machine learning
A fitted DNA ‘plug’ lets frozen language models answer gene questions
Source published
Shared keywords: ridge regression
Knowing When to Stop Is Still a Challenge for Reasoning AI
Source published
Shared keywords: early stopping
Four equations summarize changes in sleep across 1,106 nights
Source published
Shared keywords: symbolic regression