TRANSMISSION // 2611.08741v1
AlterNet tests whether language models can learn when to stop computing
Source published
An experimental language-model design learns how many processing rounds to use. Early tests cut the average iteration count roughly in half, but prediction quality worsened, and practical speed or energy savings remain unmeasured.
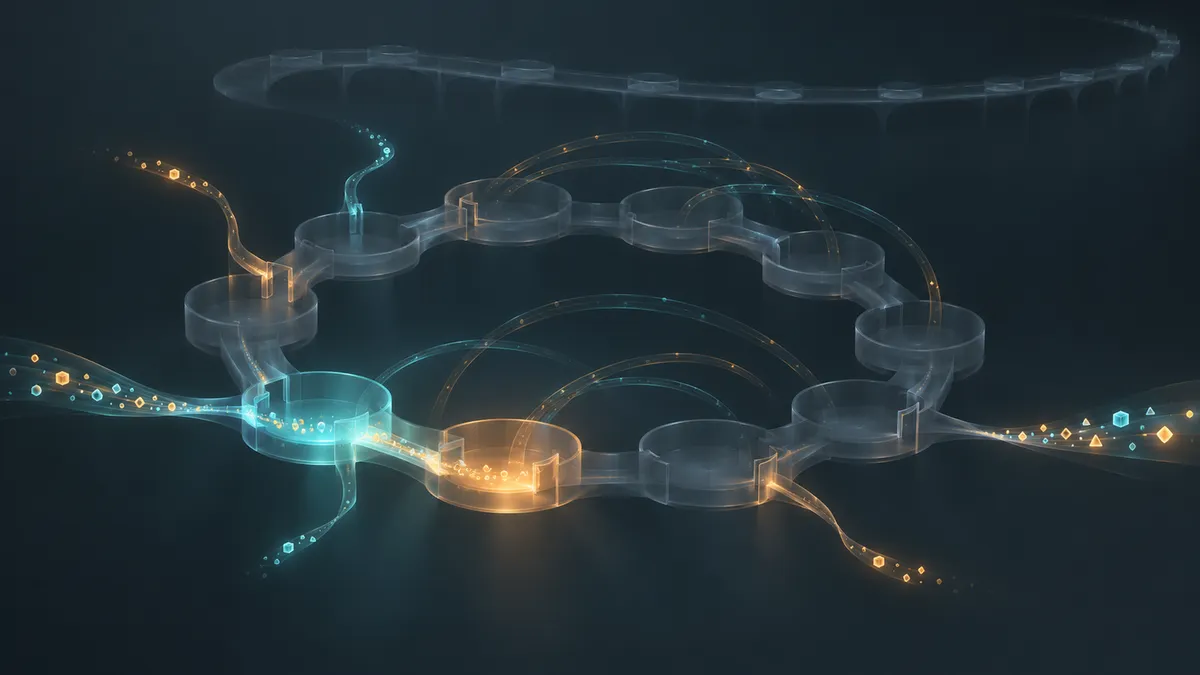
Does every piece of text need the same amount of computation? AlterNet explores a language model that repeatedly routes information through small processing modules, then learns when to stop. Its first results show a trade-off—not a free efficiency gain.
Alexander Kastius of SAP describes AlterNet in a preprint submitted on November 5, 2026. The work has not been peer reviewed. Its central question is whether a language model can learn to vary its computational depth while retaining useful predictive performance, rather than always executing a fixed number of processing stages.
The initial experiments show that learned stopping can work in this architecture. They also expose substantial difficulties: unstable training, worse language-modeling scores than the fixed-depth comparison, and an efficiency claim measured in processing iterations rather than elapsed time or energy.
A model that loops through experts
AlterNet builds on mixture-of-experts models, which activate selected neural-network modules rather than using every module for every input. Its experts are shallow: each contains a single transformer block, combining attention with a feed-forward network.
Instead of passing information through a fixed stack of distinct layers, AlterNet repeatedly routes its evolving internal representation through selected experts. Outputs from one round become inputs to the next, allowing information to move between experts over successive rounds.
In the approximately 350-million-parameter experiments, the router selected two of ten experts at each round, with a maximum of twelve rounds. Routing decisions applied to an entire input sequence, not separately to each token. The router used the internal representation of the last valid token to summarize that sequence.
Two mathematical depth signals told the router where it was in the loop and represented the remaining iteration budget. Each expert also produced a learned stopping signal. These signals were combined to determine the probability of halting at each round. They are training-dependent signals—not independently verified measures that an answer is correct.
Training balanced several objectives: predicting text, distributing work among experts, stabilizing routing, shaping the stopping distribution, and encouraging a stop when another round brought little improvement.
Learning not to quit immediately
A major obstacle was what the paper calls “depth-bootstrap collapse.” If the model learned to stop very early, later rounds received little training weight. Those rounds then had less opportunity to improve, reinforcing the preference for an early exit.
The successful 350-million-parameter configuration combined an initial training period that forced full-depth computation with a bell-shaped target distribution for stopping, centered around six rounds. This replaced a geometric distribution that favored early stopping. The combined setup remained stable through 30,000 training steps; the alternative configurations reported in the appendix collapsed or failed to develop useful deeper computation.
Smaller experiments also favored giving the router the budget signal and placing stopping heads inside individual experts rather than using one central head. However, these were short, single-seed experiments, and many configurations settled on essentially the same stopping depth for every example. The paper explicitly cautions against assuming those findings hold at larger scales.
Fewer rounds, worse predictions
The main comparison used two similarly sized AlterNet models trained on English C4 text. Model I always ran twelve rounds. Model II learned to halt dynamically.
The fixed-depth model achieved a perplexity of 40.1, compared with 54.3 for the adaptive model. Perplexity measures how well a model predicts text; lower is better. The adaptive model therefore performed worse on this measure.
In exchange, it used 48.3% as many inference iterations—roughly 5.8 rounds instead of twelve, or about 52% fewer rounds.
The training comparison was unequal. The fixed-depth model stopped after 10,000 steps, having seen about 1.3 billion tokens. The adaptive model trained for 30,000 steps and about 3.9 billion tokens. At equal step counts, the adaptive model lagged behind. Both remained substantially undertrained by the paper’s assessment.
What remains unproven
Neither model matched the roughly 21–22 perplexity reported for OPT-350M on C4, although OPT had received far more training data. Perplexity alone also cannot establish broader reasoning ability or usefulness.
Crucially, fewer iterations do not establish an equivalent reduction in latency, monetary cost, or energy consumption. Those deployment benefits were not demonstrated. The proposed ability to lower the computation budget after training without retraining also awaits a precise evaluation.
AlterNet’s result is therefore a preliminary demonstration of learned stopping in a looping expert architecture, with a clear quality cost. Whether that mechanism becomes practically advantageous requires longer training, broader evaluation, larger models, and direct measurements of inference performance.
- AlterNet
- language models
- mixture of experts
- adaptive computation
- learned halting
- inference efficiency
- perplexity
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Switching Off AI Experts Can Break More Than Routing
Source published
Shared keywords: mixture of experts
ValQID weighs the value of interface clues when identifying devices
Source published
Shared keywords: adaptive computation
Can AI agents work with less context? A study tests compact memory and selective reading
Source published
Shared keywords: inference efficiency, language models
RECAP speeds up vision-language models by recycling predictions in context
Source published
Shared keywords: inference efficiency
A Shortcut for Calling Tools Inside a Language Model
Source published
Shared keywords: inference efficiency, language models