TRANSMISSION // 2611.08718v1
AI shopping assistants improve in simulations when they remember and ask questions
Source published
A study tests a conversational recommendation system that combines stored preferences, coordinated AI agents and product retrieval. Simulated acceptance rose with clarification and memory, but exact-item accuracy showed a more mixed picture, and real-world benefits remain untested.
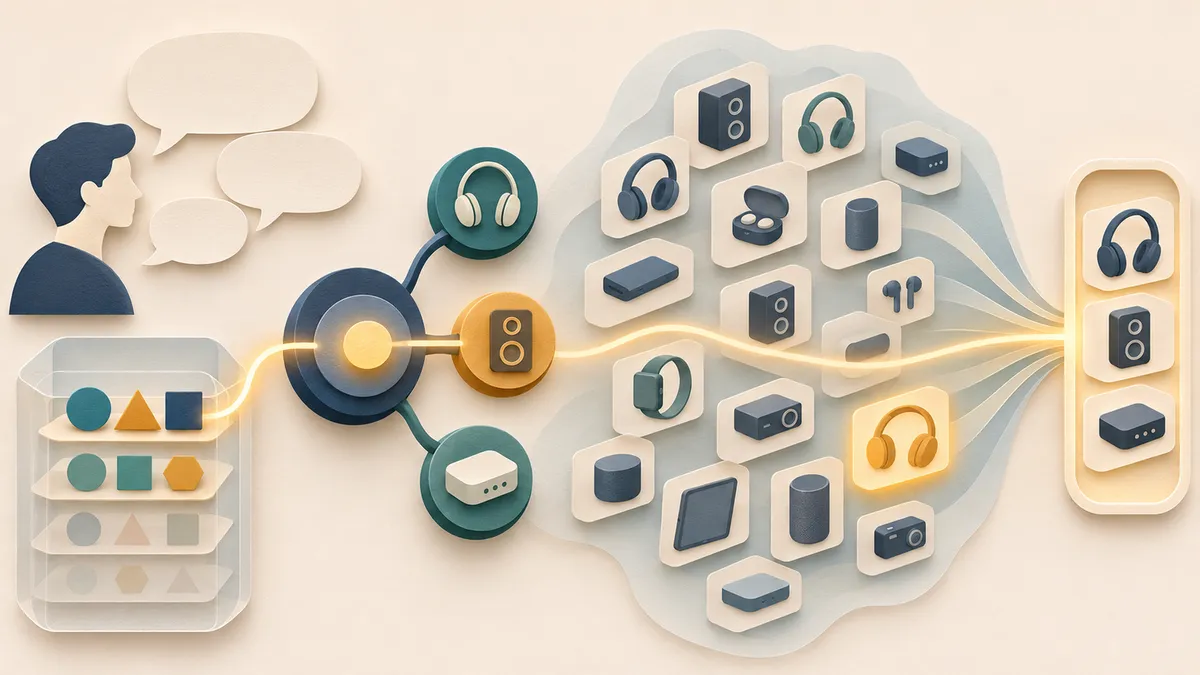
A shopping assistant may need more than a good product search engine: it must work out what a customer means, decide when to ask questions and remember relevant preferences. Researchers have tested an architecture that coordinates those tasks, finding gains in controlled simulations—but also a gap between finding a desired product and actually showing it.
Emilly Pitman de Castro and colleagues at Instituto de Ciência e Tecnologia Itaú and Instituto de Pesquisas Eldorado in Brazil investigate a system-level question: how should language models, memory and conventional recommendation algorithms work together across a conversation? The arXiv version examined here identifies a published version of record in Intelligent Systems, part of Springer’s BRACIS 2026 proceedings. The study suggests that coordination and remembered context can improve recommendations under vague requests. It does not establish that the same gains would occur with real shoppers.
An assistant with divided responsibilities
The architecture assigns different jobs to cooperating software agents. A supervisor coordinates the interaction, helping refine requests and deciding when the system should seek clarification or recommend products. A conversational agent asks targeted follow-up questions to uncover missing preferences.
Long-term memory is consulted before those coordination decisions. Stored preferences, constraints and contextual information can therefore change both the search query and how the request moves through the system—not merely appear in the final response. New memory entries reference previous states while maintaining one active representation.
The product engine combines three signals: similarity in meaning between requests and product information, patterns in users’ past interactions, and word-based matching against descriptions and reviews. A language model then reorders retrieved candidates for contextual relevance. Crucially, that final model cannot introduce products that the retrieval stage did not find.
Testing clarification and memory
The researchers used the Amazon Reviews 2023 Electronics dataset, selecting its 1,000 most active users. Their subset contained 19,678 items and 54,521 interactions. They compared several recommendation approaches offline, then conducted separate conversational and cross-session experiments.
In the supervisor experiment, all configurations shared the same retrieval engine. The baseline recommended from a single request; a conversational version could ask for clarification; a third also enabled memory. The engine retrieved 10 products and displayed three.
Acceptance here was not a human satisfaction rating. A simulated user had information about a hidden target product, and an alternative qualified as acceptable if it matched the target’s category and features, with a price within 30% of its price.
Under that rule, acceptance rose from 37.6% for the baseline to 57.9% with conversation, then to 66.5% with memory. The full system’s gain was 28.9 percentage points; clarification without memory accounted for 20.3 points. Exact-target retrieval changed much less, from 50.7% to 51.6%. That distinction matters: an acceptable alternative need not be the particular item held out for evaluation.
The improvement also involved more interaction. Average session length increased from one turn at baseline to 2.09 with conversation and 3.68 with memory. Failed sessions in the memory-enabled configuration averaged 7.59 turns.
A separate two-session experiment used 30 synthetic profiles. After preferences were revealed and stored in the first session, the researchers issued the same vague request with and without restored memory. A language-model judge gave memory-enabled recommendations an average alignment score of 5.60 out of 10, versus 4.07 without memory. Memory won 57% of comparisons, lost 33% and tied 10%.
Finding a product is not showing it
Another experiment used a Claude 3 Haiku simulated user to seek a held-out product without naming it, across up to six turns, for 998 user histories. By turn six, the target had appeared somewhere in the internal retrieval results in 74.75% of sessions, but had been displayed in only 62.63%. The authors describe this as an exposure bottleneck: successful retrieval does not guarantee that a product reaches the user.
Offline results also resisted a simple success story. A popularity-based baseline achieved the highest exact-item ranking accuracy, although its Hit@10 was only 0.0167. Language-model reranking improved reported semantic alignment and diversity, but did not improve exact-match accuracy.
To assess alignment, the authors introduced a Semantic Consistency Score: a language model judges whether each recommended item satisfies the request’s constraints. The score rose from 0.930 for the hybrid system to 0.954 with reranking. However, ambiguous judgments were counted as consistent, potentially pushing scores upward.
Promising patterns, limited evidence
The findings come from a small, selected dataset, synthetic requests, simulated users and model-based judgments—not a deployment with human customers. The intent-recovery experiment also lacked a temporal split, so it should not be read as a test of predicting future purchases.
The authors caution that differences indicate trends rather than statistically robust performance estimates. Memory can also mislead when stored preferences become outdated. The evidence supports further testing of coordinated memory and dialogue, not a claim that remembering more will always produce better recommendations.
- conversational recommendation
- large language models
- multi-agent systems
- long-term memory
- personalization
- simulated users
- recommendation evaluation
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
FITTER combines AI-generated exercise plans with explicit safety checks
Source published
Shared keywords: multi agent systems
Keeping AI agents within their assigned authority
Source published
Shared keywords: large language models, multi agent systems
The Difficult Work Behind Language-Model Game Characters
Source published
Shared keywords: large language models
MA-Mesh Gives AI Agent Teams a Way to Review and Replace Failing Peers
Source published
Shared keywords: large language models, multi agent systems
PatchScout explores when to leave one web search behind
Source published
Shared keywords: large language models, multi agent systems