TRANSMISSION // 2611.08714v1
AI-generated rules patch a fraud detector without retraining it
Source published
An eBay research team reports that a reversible layer of language-model-generated rules improved a fraud detector trained on selection-biased, approved-only traffic. The offline gains were measured on a small unbiased cohort approved regardless of score—not on the filtered training population. Results were smaller and mixed on a public benchmark, and the approach has not undergone a live A/B test.
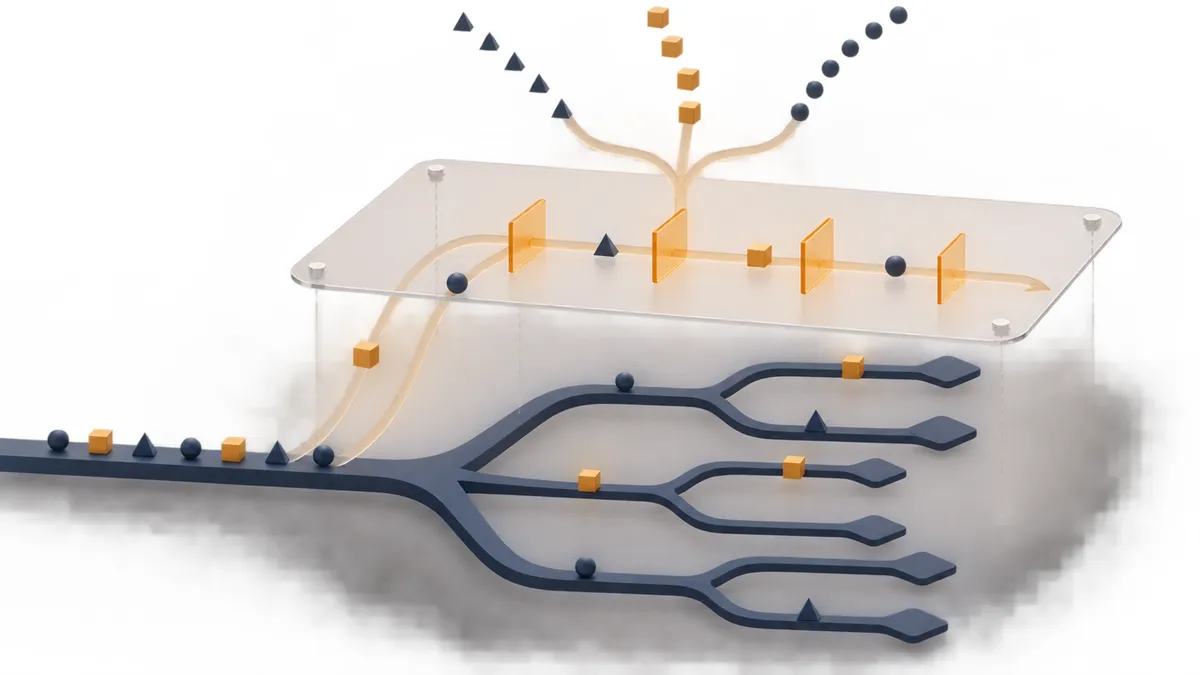
Updating a fraud detector can reinforce its blind spots if the new training examples carry the same biases as the old ones. A new preprint explores a different approach: leave the detector unchanged and add a removable layer of empirically screened rules.
Why leave the detector unchanged?
Fraud detectors learn from transactions whose outcomes are available, but those records may not represent everyone the system encounters. In the industrial setting studied by eBay researchers Bo Qu, Zhurong Wang, Frank Zahradnik and Ming Ouyang, earlier screening systems filtered transactions before they entered the training records. The detector therefore learned from approved traffic while serving a broader population.
Crucially, the researchers evaluated it on a different population: a small unbiased cohort whose transactions were approved regardless of score. That cohort allowed them to test whether the detector and its proposed updates generalized beyond the selection-biased training population.
Retraining on more similarly filtered examples can preserve that mismatch. The researchers instead investigated whether large language models could suggest useful corrections without altering the existing detector. Their paper, Patching the Blind Spots: Reversible LLM Rule Overlay for Frozen Fraud Detectors, was submitted to arXiv on November 5, 2026. The supplied version is a preprint, not evidence of peer-reviewed publication.
Language models propose; transaction evidence screens
The approach uses language models to generate candidate rules, not to classify each incoming transaction directly. Each model receives a description of the fraud problem, summaries of the existing model’s trees and feature-attribution diagnostics produced with SHAP, a technique for describing how features contribute to predictions.
The researchers divide features according to their average SHAP contributions on fraudulent transactions in an adaptation window. They ask the language models to anchor proposed rules on the lower-contributing group, while allowing other features as additional filters. This is a search strategy for possible blind spots, rather than proof that every lower-contributing feature contains overlooked fraud information.
Three open-weight language models, from the DeepSeek, Gemma and Qwen families, each make 10 independent generation attempts per dataset. Their proposed rules combine conditions with “AND,” using feature thresholds or categories. One industrial example combines unusually frequent failed payments associated with a shipping address and a high buyer-segment value.
Software rejects rules that cannot be compiled, duplicates and candidates lacking measured support. A rule must identify transactions with a fraud rate above the adaptation window’s baseline. Within each relevant score band, it must fire on at least three transactions and exceed that band’s baseline fraud rate. These checks establish historical support, not guaranteed future usefulness.
A removable scoring layer
Retained rules adjust a transformed version of the original score using the logarithm of their measured fraud lift. Calibration is performed separately for different operating score bands. Outputs from retained generation attempts are averaged in logit space, the mathematical scale used for these additive adjustments.
A lookup table then maps the adjusted result back onto the production score scale, allowing the existing alert threshold to remain unchanged. The mapping matches alert counts on the adaptation data; it does not guarantee identical alert volumes on future traffic. Disabling the rules restores the original scoring behavior, according to the method’s design.
All fitted rules, coefficients and lookup tables are fixed before evaluation on later data. Serving requires those stored components, rather than fresh language-model generation for each transaction.
What the offline tests found
The industrial detector was trained on selection-biased, approved-only traffic from October and November 2025. Its reported test results came from the unbiased cohort, covering January 1 through March 7, 2026. On that later evaluation population, the combined overlay increased recall at equal precision by an average of 2.26 percentage points and precision at equal recall by 1.60 percentage points across six operating cutoffs. Recall measures the share of fraud detected; precision measures the share of alerts that are actually fraud.
These are threshold-sweep comparisons, not simply changes at one unchanged cutoff. The calculation also subtracts what the original detector could achieve by moving its own threshold. The reported 95% confidence intervals were 1.84–2.90 percentage points for the recall gain and 1.28–2.04 points for the precision gain, using a bootstrap over calendar-day blocks.
A conservative continued-training comparison—one additional boosting round at a reduced learning rate—lost 7.69 percentage points of recall at equal precision and 2.85 points of precision at equal recall. Those losses were also measured on the same unbiased evaluation cohort. The comparison therefore concerns generalization across the training–evaluation population mismatch, not performance solely on the filtered traffic used to train the original detector.
Results were more modest on seven evaluation splits of the public Bank Account Fraud benchmark, where the study reports no corresponding training–evaluation population mismatch. Average precision gains at equal recall ranged from 0.02 to 0.30 percentage points. Recall changes at equal precision ranged from −0.13 to +0.27 points. Some individual operating points deteriorated, so the results do not establish a universal no-harm guarantee.
Combining language models reduced dataset-dependent variation: the strongest individual source on the industrial data performed poorly on most public-benchmark splits. Removing band-specific calibration also reversed the industrial recall gain into a 2.41-point loss.
What remains unproven
All results are offline, with no live A/B test. The industrial dataset is private, and two public-benchmark variants share an evaluation population. The team did not compare its language-model proposals against conventional rule-mining methods, leaving the specific added value of language models unresolved.
Only two continued-training configurations were examined, and methods designed to correct selection bias were not tested. Readable rules also do not establish causal explanations for fraud. The evidence supports a promising, reversible adaptation strategy in the tested setting—not a general replacement for retraining or human oversight.
- fraud detection
- large language models
- rule overlays
- selection bias
- gradient-boosted trees
- SHAP
- model calibration
- interpretable machine learning
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Language models help design rewards for two-stage payment fraud detection
Source published
Shared keywords: fraud detection, large language models
AI-designed rewards help a fraud detector learn from blocked payments
Source published
Shared keywords: large language models
When Dropping Incomplete Records Can Preserve a Causal Estimate
Source published
Shared keywords: selection bias
LEAP predicts which training hardware offers better value before jobs launch
Source published
Shared keywords: gradient boosted trees
Simpler building blocks for inspectable predictions
Source published
Shared keywords: interpretable machine learning