TRANSMISSION // 2611.08645v1
Beyond spotting windows: A LiDAR benchmark asks what building features do
Source published
HFX3D combines approximately 492 million laser-scanned points from 26 Halifax buildings with labels describing architectural elements and their functions. The preprint’s tests expose difficulties in identifying rare features, separating repeated windows and inferring properties such as operability from exterior scans.
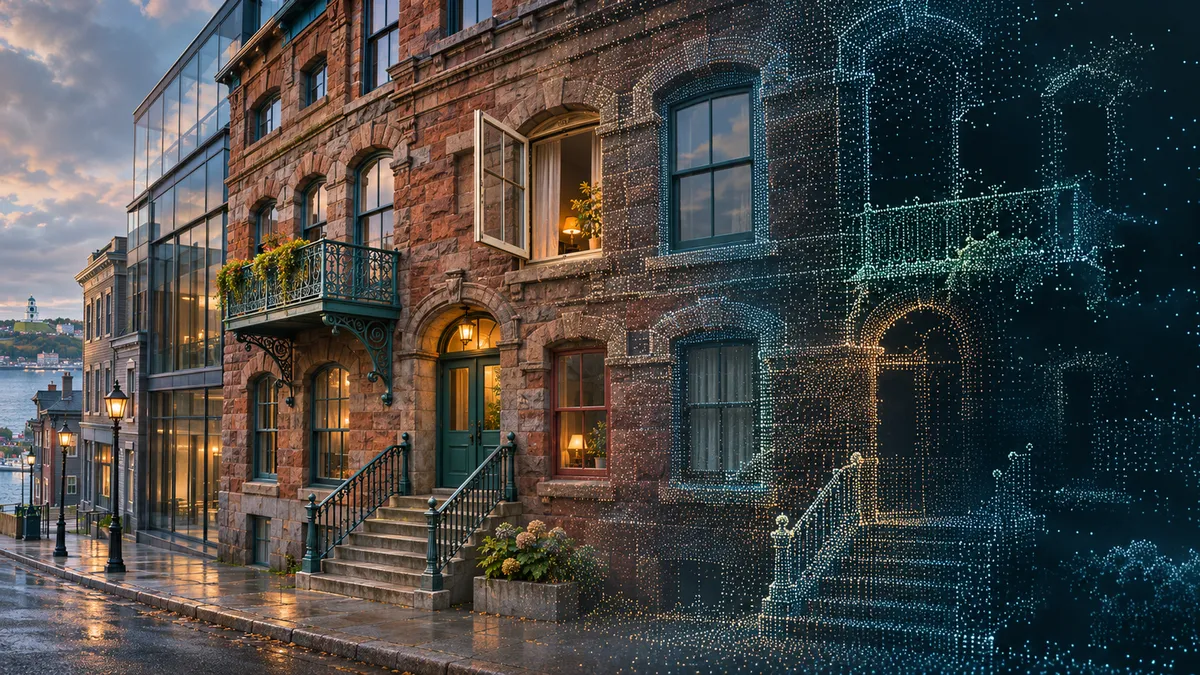
Recognising a window is not the same as knowing whether it opens. A new building-facade dataset makes that distinction central, challenging AI systems to move beyond identifying architectural shapes toward estimating their roles—while highlighting how much exterior scans can leave uncertain. The arXiv landing page reports that the work was accepted to WACV 2027.
From identifying objects to describing their roles
A digital building model can show where windows, doors and columns are without revealing whether a window opens or a column supports weight. Those distinctions matter for models intended to represent how buildings function, rather than simply how they look.
In the preprint From Geometry to Function, Abdiaziz Muse and colleagues introduce HFX3D, a benchmark combining three tasks: identifying categories of facade features, separating individual objects and assigning functional attributes. The authors describe it as, to their knowledge, the first facade dataset to combine all three annotation levels. It is a research benchmark, not a demonstrated system for certifying building performance or safety.
What the researchers collected
HFX3D contains approximately 492 million LiDAR points from 26 buildings across five neighbourhoods of Halifax, Canada. LiDAR measures surfaces using laser light, producing a three-dimensional collection of points. A handheld scanner and mounted camera supplied geometry and colour; the benchmark inputs also include laser-return intensity.
The selected buildings varied in height, materials, architectural era and facade complexity. Collection covered four seasons, daytime and night-time, and conditions including snow, fog and sunshine. This variety broadens the dataset’s conditions, but does not itself establish that models perform reliably across them.
Four trained annotators assigned points to 12 categories, including walls, windows, doors, balconies and stairs. Automatic clustering then proposed individual objects, which people corrected by merging fragments and splitting incorrectly combined elements. That review reduced 8,586 proposed instances to 6,418 final instances.
Each instance also received a vector of 15 functional attributes, such as operability, ventilation, drainage and fall protection. Initial suggestions combined architectural rules with measurements of shape and relationships to nearby objects. Reviewers checked these suggestions against scanner imagery and street-level photographs.
The buildings were divided into 18 for training, four for validation and four for testing. Keeping buildings separate prevents points from the same building appearing in both training and evaluation.
High overall accuracy can hide missing details
The team tested seven neural-network architectures for semantic segmentation: assigning a category to each point. Predictions covered every test point, rather than only a sampled portion.
KPConv performed best, reaching 86.64% overall point accuracy but only 47.26% mean intersection-over-union, or mIoU. This second measure evaluates overlap between predicted and reference regions separately for each category, then averages across categories. It makes failures on uncommon features more visible than overall accuracy does.
The contrast matters because walls and terrain dominate the dataset. KPConv achieved 91.59% overlap for terrain but 19.47% for doors. Arches, accounting for about 0.3% of points, had negligible overlap across all tested models. Identifying the bulk of a scene therefore did not mean recovering its architectural detail.
Repeated windows remain difficult to separate
Recognising all window points is different from deciding which belong to each individual window. Among three learned instance-segmentation methods, SoftGroup led with an AP50 score of 0.2923. AP50 summarises precision and recall when a predicted object must overlap a reference object by at least 50%; it is not the percentage of objects correctly identified.
For windows, SoftGroup’s average precision fell from about 0.56 at a 25% overlap requirement to 0.22 at 50%. That drop indicates difficulty outlining individual windows accurately, even when their approximate locations are found.
Separate clustering experiments supplied the correct point categories in advance. These are diagnostic tests, not directly comparable competitors to models that must infer categories themselves. Even with that advantage, neighbouring window panes often merged together.
Shape helps infer function—but combining evidence is not always better
Functional evaluation included 1,131 test instances, with a 714-instance subset drawn from categories whose members had differing attribute sets.
On this ambiguous subset, category-based rules alone scored 0.4808 in macro-F1, a measure balancing precision and recall and averaging across attributes. Geometry alone reached 0.7039. Combining category rules, geometry and neighbouring-object context scored 0.6606—below geometry alone. More evidence did not automatically produce better predictions.
The combined method matched the complete reference attribute set for 54.34% of ambiguous instances. Unlike an average attribute score, this stricter measure counts an instance as correct only when its entire attribute set matches.
The limits of reading a building from outside
Functional labels remain interpretations of visible evidence. Load-bearing status, for example, was assessed from exterior geometry and imagery, not verified against structural drawings. Glass can produce sparse laser returns, while vegetation and other obstructions can hide handles, seams and structural connections.
The reference labels also originated from suggestions produced by the same rule-based pipeline later evaluated against human-corrected labels. Reviewer agreement supports consistency, but is not independent proof of physical function.
Finally, four test buildings provide limited geographic coverage, and the learned instance methods had only one training run each. Some categories contained very few test objects. HFX3D offers a richer way to study building understanding, but its results underline the distance between recognising visible form and reliably establishing function.
- LiDAR
- HFX3D
- building facades
- 3D point clouds
- semantic segmentation
- instance segmentation
- functional attributes
- urban digital twins
- computer vision
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Teaching vision transformers where finer image patches matter
Source published
Shared keywords: computer vision
Can several camera views help find the same suitcase?
Source published
Shared keywords: computer vision
A robot's-eye view, generated from outside video
Source published
Shared keywords: computer vision
LEF-JEPA targets object structure without preserving every visual detail
Source published
Shared keywords: computer vision
Animal Identification Scores Can Hide Other Clues to a Match
Source published
Shared keywords: computer vision