TRANSMISSION // 2611.08643v1
FinEvolveKG improves financial AI extraction while keeping prompt edits traceable
Source published
A preprint tests a way to adapt AI-generated financial knowledge graphs for different analysts without letting an optimizer rewrite shared extraction rules. The complete workflow outperformed the tested unrestricted alternative, but the study does not establish that restricting edits caused the gains or that better graph scores improve investment decisions.
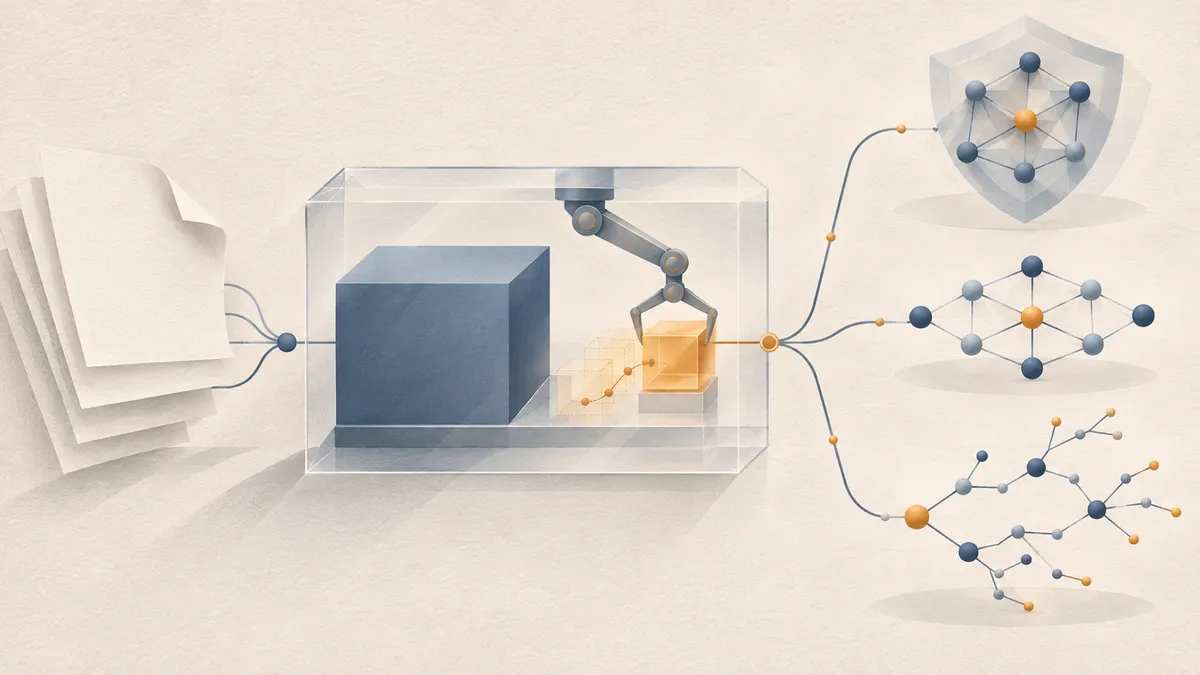
Risk analysts and portfolio managers can read the same company filing and need different facts. FinEvolveKG separates an AI system’s shared extraction instructions from its analyst-specific priorities, allowing automated revisions to one without rewriting the other.
One filing, different analytical needs
A company’s annual SEC 10-K filing can support several kinds of investigation: tracing litigation risks, monitoring financial performance or mapping products and partnerships. Turning that document into a knowledge graph means extracting entities and their relationships into structured records, with associated types and dates.
The challenge is adapting extraction priorities without losing consistent evidence rules. In the FinEvolveKG preprint, Abhinav Arun and colleagues at Domyn investigate whether automated prompt improvement can remain reviewable while producing useful graphs. Their results concern extraction quality, not demonstrated improvements in financial decisions.
Separating shared rules from analyst priorities
FinEvolveKG divides instructions into two blocks. The general block governs source support, permitted entity and relationship types, naming, duplicate removal, dates and output structure. The persona block describes an analyst’s priorities and useful relationship patterns.
The complete workflow first optimizes the general block, then freezes it while adapting each persona block. A prompt optimizer called GEPA uses model outputs and evaluation feedback to propose revisions. The software exposes only the designated block for editing; during persona adaptation, the shared block remains unchanged character for character.
This does not involve retraining the extractor’s model weights. Gemma-4-31B-it performs extraction, DeepSeek-V4-Flash proposes prompt revisions, and Claude Sonnet-4-6 generates reference graphs used for evaluation.
Crucially, freezing text does not freeze behavior. An analyst-specific instruction can still influence how the model interprets shared rules. The guarantee is about where edits occur, not whether outputs remain semantically unchanged.
How the researchers tested it
The main dataset used 2024 filings from 20 information-technology companies: eight for training, four for validation and eight for testing. All chunks from a company stayed in one split, reducing leakage from the same filing across development and testing. Each persona’s test set contained roughly 760 chunks.
Five experimental configurations included an unchanged baseline, general-only optimization, persona-only optimization from the original general rules, the complete two-stage workflow and unrestricted full-prompt optimization. These are labeled v1 through v5 within the experiment.
Evaluation balanced two components equally. General graph quality included agreement with reference facts, temporal and entity-type accuracy, source support and other construction measures. Persona utility rewarded relevant facts, topicality and connected relationship patterns. For example, a risk-oriented path might connect a company to a risk factor and then to a financial metric. Penalties discouraged unsupported facts and invalid structures.
Persona-stage searches used matched data, demonstrations and a 3,000-evaluation-call budget. However, the complete workflow also inherited the earlier general-block optimization—a consequential difference when interpreting comparisons.
Higher scores, with a modest lead over unrestricted editing
Across three optimization seeds, the complete workflow’s mean blended scores were 0.5331 for risk analysis, 0.6099 for portfolio management and 0.6273 for investment research. Relative to the unchanged baseline, those represent improvements of 27.4%, 30.9% and 19.4%, respectively.
Against unrestricted full-prompt optimization, the relative gains were smaller: 6.4%, 4.3% and 2.2%. These are improvements in the study’s composite score, not percentage-point increases in factual accuracy or investment returns.
The complete workflow beat unrestricted editing in all nine matched persona-and-seed comparisons and showed the lowest observed score variability for each persona. With only three seeds and one fixed shared-block artifact, the authors characterize these findings as descriptive rather than formal significance tests.
Saved prompts also performed better than unrestricted editing in all 15 tested comparisons across unfamiliar sectors, a later filing year or both. These tests used only one optimization seed. The complete workflow was not universally best: general-only optimization led in four portfolio-management comparisons.
What human checks establish
One financial specialist audited 200 reference-graph sets drawn from 50 chunks. Of these, 178 were acceptable, 19 needed minor corrections and three were unreliable. Combining the first two categories gives 98.5%, but this is not a claim that 98.5% of individual facts were correct. Missing unrelated facts alone did not trigger downgrading.
Separately, two blinded specialists preferred the complete workflow over unrestricted editing in 70.1% of judgments. That audit deliberately selected chunks with larger score differences, so it cannot estimate preference across the entire test set.
Traceability is not a guarantee of correctness
The study supports a practical conclusion: tightly localized prompt edits can coexist with strong extraction scores. It does not isolate the edit boundary as the cause, because initialization and optimization history also differ.
Reference graphs remain model-generated, broader sector coverage is limited, and analyst usefulness is measured through graph proxies rather than downstream tasks. Temporal scoring used filing-default dates rather than extracted timestamps. The work is presented as a preprint, and its central safeguard is reviewable instruction changes—not an exemption from validating financial outputs.
- FinEvolveKG
- financial knowledge graphs
- prompt optimization
- large language models
- SEC 10-K filings
- GEPA
- AI evaluation
- traceability
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Pairing predictive AI with a medical reference chatbot to explain diabetes classifications
Source published
Shared keywords: large language models
An AI patent-mapping pipeline keeps its decisions open to inspection
Source published
Shared keywords: large language models
Expert Feedback Raises Average Ratings for AI Finance Briefs
Source published
Shared keywords: ai evaluation, large language models
Do language models consistently rank moral trade-offs?
Source published
Shared keywords: ai evaluation, large language models
Can AI Models Help Check Each Other’s Explanations of Legacy Code?
Source published
Shared keywords: ai evaluation, large language models