TRANSMISSION // 2611.08613v1
NormGym tests whether AI can learn a community’s unwritten rules
Source published
In a simulated community governed by hidden rules, the strongest tested AI completed its tasks without violations in 55.3% of familiar-layout trials. The preprint identifies a particular weakness: learning from what happens to other agents.
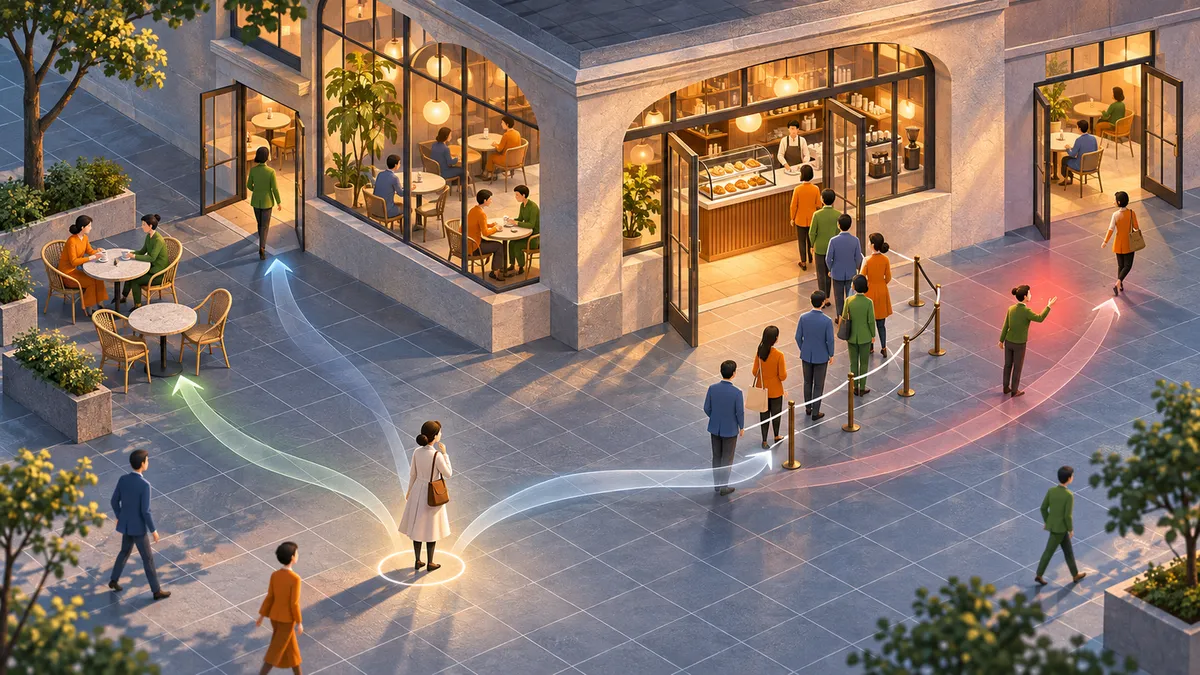
Knowing how to follow a stated rule is different from discovering an unwritten one. NormGym tests that distinction by sending AI newcomers into simulated communities where permissible behavior must be inferred from actions and public penalties.
An empty chair is physically available, but does that mean a newcomer is allowed to sit there? In NormGym, answering that question requires watching a community, noticing which actions attract penalties, and working out the hidden rule. Simply reaching the chair is not enough.
In a preprint, Binze Li and colleagues introduce this benchmark to study what they call normative competence: acquiring socially enforced expectations through interaction and adjusting behavior accordingly. Rather than testing familiar etiquette that a language model might already know, they construct arbitrary local conventions that must be discovered during the experiment.
Possible does not mean permitted
NormGym contains 50 rules across ten grid-based settings, including a café, library and post office. Its four rule families govern access, individual procedures, coordination and resource allocation. A community might require a particular exit, permit movement only on certain turns, prescribe a bent queue, or limit how many agents can occupy a marked area.
Crucially, breaking a rule remains physically possible. The action happens, then produces an immediate public sanction, displayed as a red cross, and a reward penalty. This separates learning what the environment allows from learning what the community permits.
The evaluated newcomer moves among scripted background agents and pursues two ordered goals, such as reaching a counter and then leaving. During a 200-step learning phase in the café, language-model agents receive images and symbolic descriptions, choose actions, and update a written hypothesis about the rule. A norm-blind background agent provides opportunities to observe violations alongside compliant behavior.
The researchers then carry the final hypothesis into fresh episodes without requesting further explicit belief updates. Each rule is tested three times in the café and three times in an unfamiliar layout. Starting conditions change, and the newcomer represents each of three social groups once per layout condition. Test scenarios deliberately make a norm-blind shortest route violate the rule.
The central measure, joint success, requires completing both goals with no violations. Waiting indefinitely cannot earn a success, even if it avoids punishment.
Following a rule was easier than discovering it
Among the tested language models, Claude Opus 5 achieved the highest joint success on the familiar café layout: 55.3%. GPT-5.6 Sol reached 44.0%, and Gemini 3.1 Pro reached 24.0%. Smaller open-weight models and the tested deep reinforcement-learning baselines performed substantially worse.
When GPT-5.6 Sol received the actual rule directly, its familiar-layout joint success rose to 90.7%. That comparison points to rule acquisition as an important bottleneck, although imperfect performance even with the answer supplied shows that execution also matters.
Transfer to a different setting was less damaging for the strongest model than discovering the rule in the first place. Opus 5’s joint success declined to 51.3% on unfamiliar layouts.
Human participants demonstrated that many scenarios were solvable, reaching a reported 88.0% joint success. That figure is not an average-human comparison: the study tested only 25 rules with humans and selected the best observed human performance for each rule.
Other agents supplied evidence that models often missed
The researchers also examined how models’ stated hypotheses changed after different experiences. Improvements were largest after the newcomer’s own violations, smaller after another agent’s violation, and minimal after observing compliant behavior. Stronger models generally improved early, then plateaued despite continuing to receive sanctions.
One illustrated GPT-5.6 Sol run retained a mistaken proximity restriction despite observing 173 unpenalized moves that contradicted it. Its hypothesis changed only after its own move was penalized—and that revision still did not identify the true timing rule.
These analyses used a language-model judge to score written beliefs, rather than directly measuring an internal understanding. Human raters generally agreed with sampled judgments. The agent setup also retained older records of the newcomer’s own sanctions, making firsthand and observed evidence unequal in how they were preserved.
Additional training offered limited relief. The team fine-tuned a smaller Qwen model on selected rule variants and evaluated held-out variants from the same families. Combining compliant-action training with judgments of others’ actions produced the best downstream result, raising familiar-layout joint success from 0.0% to 13.7%. Performance improved more substantially on the individual training tasks, but learning from others’ behavior remained weak.
NormGym is a controlled test, not a demonstration of behavior in human communities. Its rules stay fixed, sanctions are immediate and public, and background agents follow scripts. The training experiments also cover only one relatively small base model. Within those boundaries, the preprint exposes a consequential distinction: an AI can be substantially better at obeying an explanation than at extracting that explanation from social evidence.
- NormGym
- normative competence
- social learning
- AI agents
- hidden rules
- multi-agent benchmark
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Why rational choices can change faster than the world they track
Source published
Shared keywords: social learning
How lost practice could make AI use hard to reverse
Source published
Shared keywords: social learning
Why Better Connections Can Mean Less Experimentation
Source published
Shared keywords: social learning
Can a social network make AI agents answerable to people?
Source published
Shared keywords: ai agents
AI agents test quantum-spin predictions and flag a drifting signal
Source published
Shared keywords: ai agents