TRANSMISSION // 2611.07948v2
Can an AI model tell when its own answer is wrong?
Source published
Circe estimates whether a language model’s response is correct by combining clues from its internal computations with token probabilities. Across five models and six benchmarks, the authors report stronger average performance than reference-free baselines. The method is a ranking aid, not a proof-checker, and its results come from selected benchmarks in an arXiv preprint whose review status is unclear.
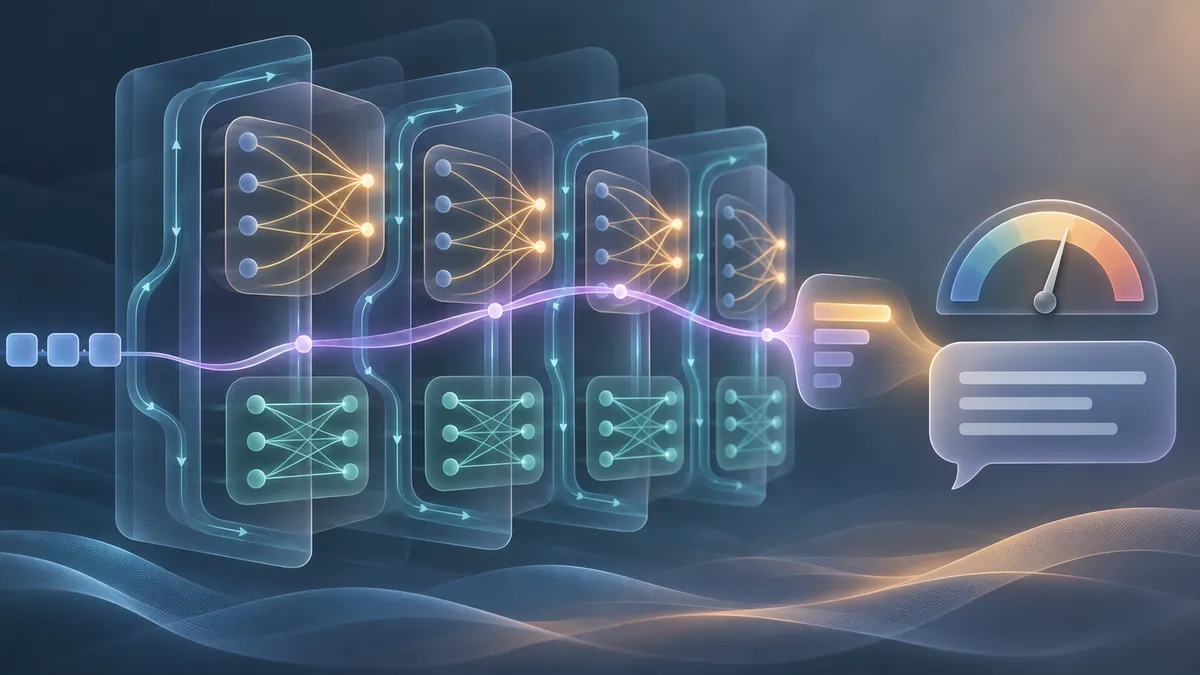
A fluent answer can still be wrong, and in many real-world exchanges there is no ready-made reference answer to check it against. Circe looks not only at a model’s words but at how parts of its neural network process information. The study asks whether combining these clues can help rank correct answers above incorrect ones.
The problem: confidence is not correctness
Language models can give plausible answers even when mistaken. That makes evaluation difficult when a reference answer is unavailable. Common alternatives—asking the model how sure it is, checking how likely its words were, or sampling several answers to see whether they agree—can all mislead. A model may confidently repeat the same error.
In Circe: Training-Free LLM Self-Evaluation via Component Interaction Consistency, Shuyi Miao and colleagues propose using a model’s internal computations as additional evidence. Their central question is whether patterns in the interaction between two parts of a transformer—attention and feed-forward networks, or FFNs—can help distinguish correct from incorrect responses.
Three signals, one score
Circe combines three measurements. The first, component interaction consistency (CIC), compares the direction of attention updates in earlier layers with changes in FFN outputs induced by attention in later layers. The authors’ intuition is that correct responses may show more consistent directions across layers. CIC measures directional alignment; it does not directly verify an answer’s claims.
The second signal, representation geometry (RG), summarizes how internal representations move and change direction as information passes through the model’s layers. The third, likelihood confidence (LC), transforms the average negative log-likelihood of generated tokens into a bounded score. In plain terms, LC reflects how probable the model considered its own wording—a potentially useful clue, but not a guarantee of truth.
Circe combines these signals into one response score. It does not update model parameters or require repeated answer sampling. But “training-free” does not mean no labeled data are used at all: the researchers used development data to select domain-specific weights for combining the signals, then fixed those weights for testing. Development and test questions were separate.
What the tests found
The researchers evaluated five open-source language models on six benchmarks covering mathematics, reasoning, general knowledge, and reading comprehension. They measured how well scores ranked correct responses above incorrect ones; Circe does not independently prove an answer true.
Across the four domains, the paper reports the best average performance among the reference-free baselines on three discrimination measures. Its advantage was not universal: it achieved the highest AUROC (area under the receiver operating characteristic curve) in 18 of 20 model–domain combinations, with two exceptions. In an ablation test, the full combination performed better on average than versions omitting CIC, RG, or LC. This supports the authors’ interpretation that the signals provide complementary information in the tested settings.
The paper also reports results from additional evaluations: eleven language versions of a mathematics benchmark, a visual geometry task, and mixtures of benchmarks intended to test performance across different sources. These broaden the evidence, but do not establish reliability across all languages, images, or real-world applications.
What remains uncertain
Circe is a ranking aid, not an independent fact-checker. Its measurements come from the model being evaluated, and internal consistency or high token likelihood could still accompany a wrong answer. The experiments assess discrimination on specific benchmark responses; they do not show that using Circe in a live system reduces harm or improves user decisions.
Results may also depend on the models, tasks, response styles, and deployment conditions. The domain-specific score weights were selected using development data, and performance may differ in other settings. The multilingual and multimodal evaluations cover particular benchmarks and models, not every language or kind of visual question.
The source is an arXiv preprint; its review status is unclear from the available evidence. The findings should therefore be read as the authors’ reported results, not as settled consensus. The experiments suggest that attention–FFN interactions may add useful evidence to self-evaluation. Whether that evidence is dependable enough for consequential decisions remains an open question.
- large language models
- AI evaluation
- self-evaluation
- model confidence
- transformer interpretability
- preprint
Reviewed cross-references
These connections were reviewed by a model, not independently fact-checked by a human. Similarity does not imply agreement; consult the original papers and the evidence below.
Can AI Models Help Check Each Other’s Explanations of Legacy Code?
Shared method: Both use token likelihood to estimate confidence: Circe transforms mean token negative log-likelihood into a bounded score, while the COBOL study derives a confidence score from perplexity. The implementations and evidence differ: Circe combines likelihood with internal activation signals across several benchmarks, whereas the COBOL workflow also combines perplexity with coverage assessment and evaluates summaries against expert judgments on a 100-chunk test set.
Model review: · openai-codex/gpt-6-luna
Evidence and provenance
Selected excerpts, not complete papers. PDF extraction can omit figures or damage equations, tables and reading order; sources may be preprints.
2611.07948v2 — Original paper
Excerpt reference:
static/papers/2611.07948v2.md:598-727
Basis: Paper text
Source SHA-256:eee7859614510640af5a085c1e1d969b440aa3a7cfa0455c100400a08676dcb22611.09846v1 — Original paper
Excerpt reference:
static/papers/2611.09846v1.md:771-866
Basis: Paper text
Source SHA-256:8ec247d4431a256e5e209c223b8a33b5b14f16cf576381bcc0cd7cbdc312bc19
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Expert Feedback Raises Average Ratings for AI Finance Briefs
Source published
Shared keywords: ai evaluation, large language models
Do language models consistently rank moral trade-offs?
Source published
Shared keywords: ai evaluation, large language models
Can a chatbot’s reply reveal the gender cue in its prompt?
Source published
Shared keywords: ai evaluation, large language models
Can AI Models Help Check Each Other’s Explanations of Legacy Code?
Source published
Shared keywords: ai evaluation, large language models
What crossword constraints reveal about AI riddle answers
Source published
Shared keywords: ai evaluation, large language models