TRANSMISSION // 2611.06674v1
AgentTrustCI tests whether Java AI agents follow the rules—not just give plausible answers
Source published
Sachin Gupta’s AgentTrustCI preprint describes a Java/JUnit framework that checks recorded AI-agent behavior for tool-policy violations, unsupported answer claims, and incorrect workflows. Its combined checks correctly classified all 55 authored synthetic cases, but the study does not establish production accuracy or evaluate live agents.
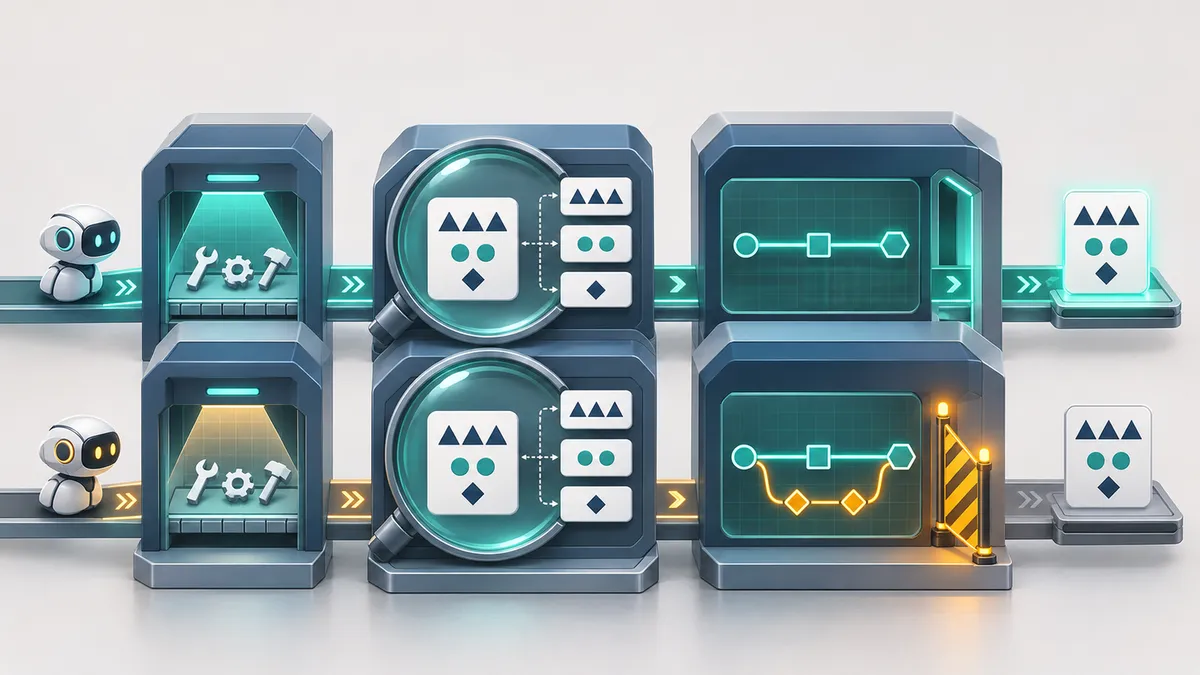
An AI agent can give a correct answer after taking an unapproved route. AgentTrustCI makes that distinction testable during a Java software build, checking recorded tool calls and answers against explicit expectations maintained by developers and workflow owners.
A plausible answer does not reveal everything an AI agent did to produce it. An agent might use a forbidden tool, request restricted information, or skip a required step while still returning an answer supported by its tool results. Protecting the execution environment does not, by itself, establish that these application-level decisions were acceptable.
In the November 4, 2026 arXiv preprint AgentTrustCI: Build-Time Policy, Grounding, and Trajectory Tests for Java LLM Agents, Sachin Gupta presents a small Java/JUnit 5 framework for making selected behavioral expectations part of automated release testing. The reported implementation evaluates stored traces, not live agents.
Three checks on recorded behavior
The framework starts with a “golden case”: a user request, a recorded sequence of tool calls and results, a final answer, and expectations describing acceptable behavior. These expectations also specify whether the case should pass or fail.
The first layer checks policy: which tools may be called and which parameters are required, forbidden, or restricted to particular values. A forbidden parameter is rejected whenever its key appears—even if its value is false. These checks enforce the case’s declared constraints; they do not authenticate users or resolve production authorization policies.
The second layer checks grounding: whether selected features of the answer have support in the recorded tool results. Deterministic rules look for identifier-like tokens, quoted passages, and multi-digit integer quantities, then compare them with the tool-output corpus. Other checks flag specified restricted-field names and certain action claims when no write-like tool was called.
The third layer checks trajectory, meaning the sequence of tool calls. Strict matching requires an exact sequence. Relaxed matching allows additional calls while preserving the required order. Separate rules can forbid intermediate tools or repeated calls.
Evaluation stops at the first failing layer and reports a diagnostic reason. Importantly, rejecting a deliberately invalid fixture is a successful test when rejection was the expected outcome. The build fails when the observed decision disagrees with that expectation.
A correct answer through the wrong route
One catalog example illustrates why the layers are distinct. The workflow requires a direct product lookup. The stored trace instead performs a catalog search followed by the lookup, then returns a product description supported by the results.
Both tools are permitted by the policy layer, and the answer satisfies the grounding checks. Nevertheless, the extra search violates the strict workflow, so trajectory validation rejects the trace. The point is not that searching is inherently unsafe: the workflow owner has explicitly required a different path.
What the experiment establishes
The evaluation contains 55 authored synthetic cases across seven enterprise domains, including support tickets, catalogs, inventory, and profiles. There are 30 injected faults and 25 valid controls, including ten controls designed to exercise less obvious acceptable behavior.
The combined pipeline rejects all 30 faults and accepts all 25 controls. It misses none of the 12 faults designated critical by the case author.
Each individual layer correctly classifies 35 of the 55 cases: all 25 controls plus ten faults. That symmetry is deliberate. The corpus isolates ten faults for each layer, making the experiment useful for demonstrating complementary coverage—not for estimating how independently these failure types occur in practice. A minimal baseline checking only for a non-empty answer catches none of the faults. The study does not compare performance against external evaluation frameworks.
Timing measurements also have a narrow scope. On the reported Apple M2 Max setup, warmed full-pipeline evaluation averages 3.369 microseconds, with a 95th percentile of 6.333 microseconds. Those measurements cover small in-memory traces and exclude loading and report writing. Separately, fresh-process command-line runs average 0.158 seconds, including JVM startup, YAML loading, evaluation, and reporting. Neither figure includes live-model inference.
Limits before deployment
The grounding rules are lexical, not general tests of meaning. A matching substring can concern the wrong entity; unsupported paraphrases or sensitive values disclosed without their field names can escape detection. Conversely, mentioning a restricted field in a refusal can trigger rejection. Tool outputs are assumed to be trusted evidence.
The prototype includes neither live-agent trace capture nor an implemented LLM-backed judge. Its linear trajectories do not express concurrent dependencies. Production-trace validation and semantic judging remain proposed work.
For release testing to assess a changed agent, teams would need to capture that candidate’s behavior and compare it with independently reviewed expectations. Passing the supplied fixtures only tests the validators on those fixtures. AgentTrustCI therefore offers a concrete pattern for reviewable behavioral contracts, not proof of production safety or a replacement for runtime authorization, monitoring, and human review.
- AgentTrustCI
- AI agents
- Java
- JUnit
- continuous integration
- policy compliance
- answer grounding
- trajectory validation
- software testing
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
DARE looks beyond coding-agent scores to diagnose repair difficulty
Source published
Shared keywords: software testing
Signals: Diagnosing AI Agents Beyond Successful Tool Calls
Source published
Shared keywords: ai agents
When AI Agents Agree, Their Majority Can Still Be Wrong
Source published
Shared keywords: ai agents
AI agents test quantum-spin predictions and flag a drifting signal
Source published
Shared keywords: ai agents
When AI agents change, should their permissions change too?
Source published
Shared keywords: ai agents