TRANSMISSION // 2611.06603v1
A proposed scheduling layer separates AI agents’ urgent work from lasting changes
Source published
Haibin Tong and colleagues propose a scheduling framework that alternates foreground work with background review while reserving persistent changes for separate validation. Five synthetic experiments identify conditional benefits and failure modes, but the accompanying language-model prototype does not establish improved task performance or consciousness.
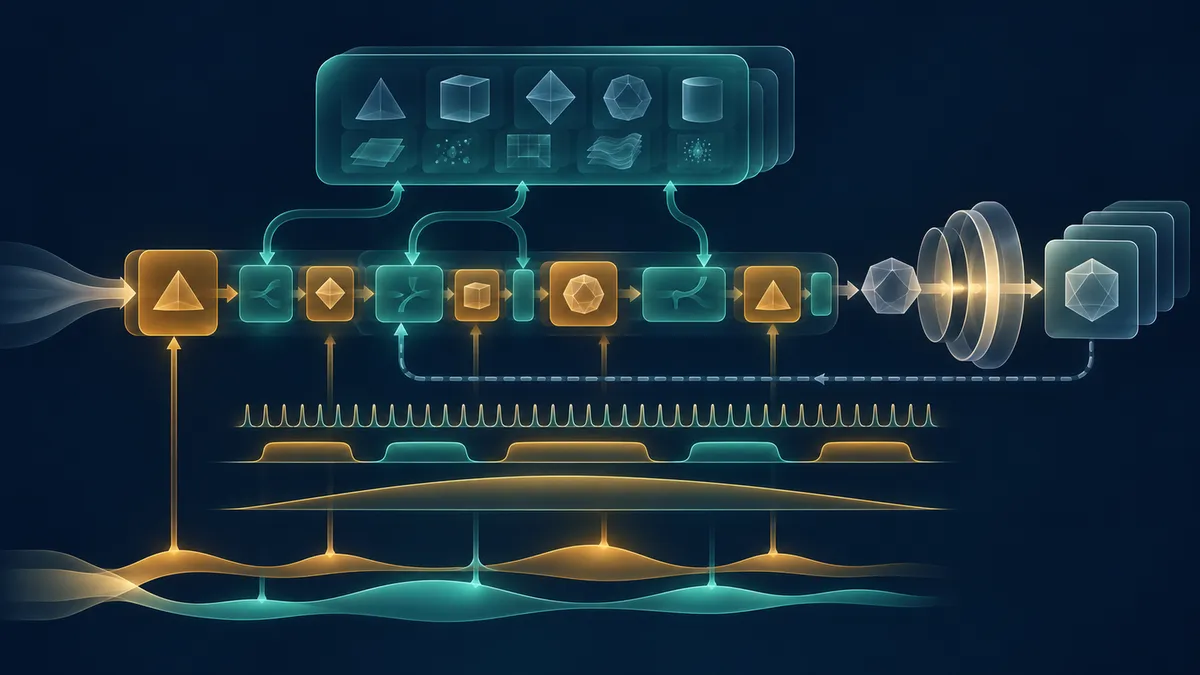
An AI agent answering an urgent request may also need to retain rejected ideas, revisit mistakes and decide whether to change its memory. A paper proposes making those competing activities explicitly scheduled and auditable, rather than treating background reflection as an unspecified process.
Scheduling action and reflection
In version 1 of their paper, submitted to arXiv on November 4, 2026, Haibin Tong, Luming Guo, Nana Cui and Jiang Yu propose a temporal organization layer for continual AI agents. Their central distinction is between generating possibilities quickly and allowing those possibilities to produce lasting changes.
The framework uses time-division multiplexing: different activities receive different processing slots while sharing model and memory infrastructure. Foreground slots handle selected requests and authorized actions. Background, or “shadow,” slots preserve alternatives, replay errors and develop revision proposals. Background work need not wait until an entire user interaction ends, although its allocation remains subject to resource limits.
The authors call the smallest recorded unit a micro-epoch. Its record includes the processing phase, evidence, selected and rejected candidates, resource information, predictions and outcomes. A rolling duty cycle measures the fraction of recent micro-epochs assigned to foreground work. These are logical scheduling units, not a requirement to run a language model at a particular physical frequency.
Three clocks and a shared boundary
The proposal separates three timescales: micro-epochs for candidate processing, task episodes for interactions and accumulated errors, and evolution epochs for reviewed persistent changes. A candidate generated during a brief background slot would not gain permission to act merely because the system later changes phase.
The foreground workflow records evidence before interpreting it, selects a candidate, retrieves relevant memory, predicts consequences and plans an authorized action. The background workflow starts from recorded failures or alternatives, considers possible explanations and counterfactual actions, and builds an evidence-bearing revision proposal.
Durable changes would pass shared feasibility, validation, operational-continuity and authorization checks. If enforcing constraints changes a proposal, the final result must be validated again. The proposed background gates cover safety, capability regression, behavioral consistency and stakeholder values. These are design requirements, not safeguards fully demonstrated by the prototype.
The authors also separate content selection from resource allocation. One controller decides what deserves attention using urgency and evidence; another allocates computing resources using load and budget. The rationale is that heavy load should not automatically make urgent work ineligible for attention.
What the synthetic experiments show
The paper reports five synthetic experiments, each using 64 random seeds. They test mathematical and scheduling mechanisms rather than real-world agent competence.
The first examines updates to a simplified mathematical objective. Its deterministic descent inequality held in all 500 checked steps. Noisy updates did not consistently improve at every step. A fixed equal-weight mixture ended with a mean potential of 0.2766, compared with 0.5563 for strict alternation; lower was better. This distinguishes mixing noisy update directions from switching between them.
The second deliberately gives online and offline processing conflicting objectives. Under the strongest tested conflict, increasing offline weight worsened the online objective. Improvement according to background review therefore need not mean improvement on the foreground task.
The third varies the relative gain assigned to the channels. When noise increased proportionally with gain, the best tested ratio was approximately 1.55. With a different noise law it was approximately 2.43; with gain-independent noise, the best result occurred at the search boundary of 6. There is no universal optimal ratio established here.
The fourth constructs tasks combining urgency and load. Separate content and resource controls achieved 26.56% modeled success on the urgent, high-load subset, versus 11.13% for the chosen coupled controller. The comparison uses a prescribed success function and does not equalize total computing expenditure, limiting broader conclusions.
The fifth removes error logs before replay. Missing evidence reduced simulated failure-mode elimination. When corroborating records were required, rare failure modes were especially vulnerable; their elimination rate reached zero with 90% log removal.
What remains unproven
A frozen-backbone Qwen3-8B prototype exercises logging, shadow storage and execution pathways. However, its success metric depends on programmed confidence rather than independently scored answers. Some reported effects are built into the code, including bonuses for retained alternatives and confidence changes tied to operation order. These outcomes do not demonstrate better language-model problem-solving.
Neuroscience supplies motivation, not validation. The paper draws on reported alternation of perceptual representations in primate cortex, but explicitly rejects copying biological timing directly into an AI scheduler or treating the analogy as evidence of subjective experience.
Practical questions also remain: retaining rejected ideas can expose sensitive information, while repeated state revisions can create cumulative drift. The authors require bounded retention, access controls, auditability and interruptible authorization. Establishing useful agent improvement would require realistic longitudinal tasks, matched resource budgets and independently assessed outcomes.
- AI agents
- time-division multiplexing
- agent scheduling
- experience replay
- persistent memory
- authorization
- synthetic experiments
- Qwen3-8B