TRANSMISSION // 2611.06554v1
RAGAM-AI uses language-model feedback to guide edge resource allocation
Source published
RAGAM-AI combines multi-agent reinforcement learning with language-model-generated rewards to allocate CPU, memory and bandwidth. Simulations report smaller allocation-demand gaps than three baseline policies, while deployment overhead and broader scalability remain questions for further evaluation.
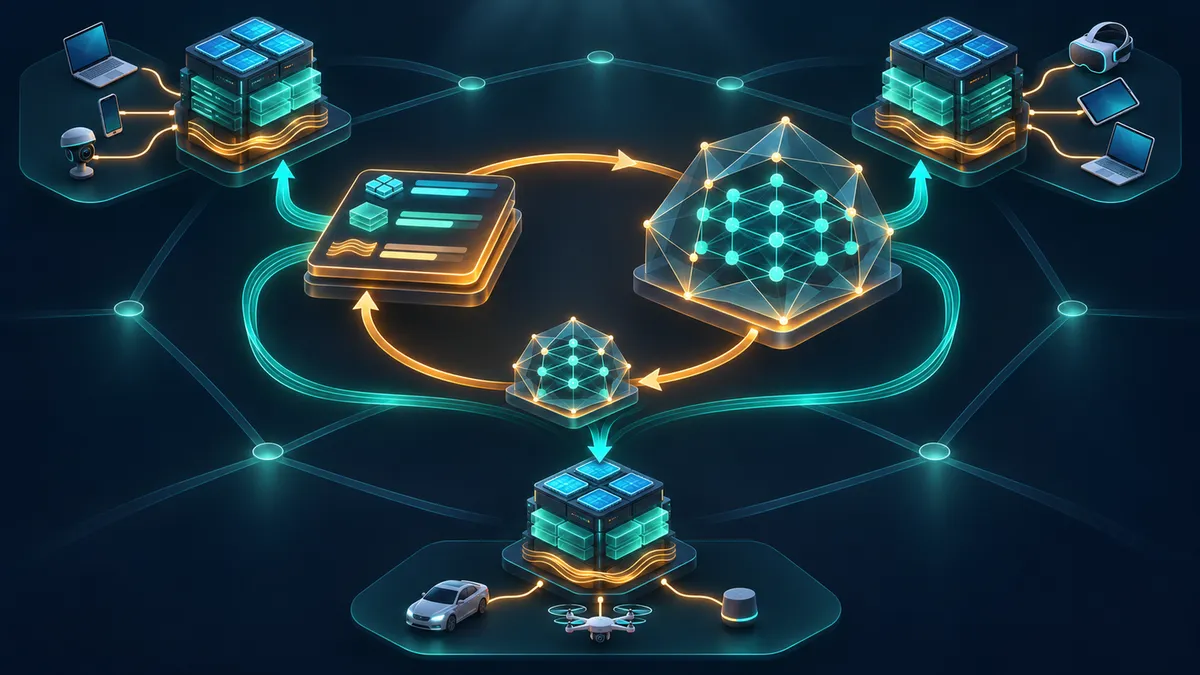
How should an edge server divide its resources when computing, memory and bandwidth demands keep changing? RAGAM-AI explores a hybrid answer: reinforcement-learning agents choose allocations, a mathematical language model helps evaluate them, and a smaller neural network learns to approximate that feedback.
Edge computing brings processing closer to the devices and services requesting it. But deciding how much CPU capacity, memory and bandwidth to allocate remains a balancing problem: allocations should match demand, respect server capacity and meet service-performance constraints. RAGAM-AI investigates whether language-model feedback can help reinforcement-learning agents navigate those competing objectives.
The paper is by Shreya K. Chari, John S. Vardakas, Kostas Ramantas and Christos Verikoukis. Its first version was submitted to arXiv on November 4, 2026. The reported evaluation is a simulation-based proof of concept, rather than a deployment in an operational edge network.
A language model evaluates decisions
Reinforcement learning depends on a reward signal that tells an agent which decisions are desirable. The authors argue that rigid reward formulas can inadequately represent changing trade-offs in edge resource management. Their proposed response combines a conventional, constraint-based reward with feedback generated by MathΣtral, a language model specialized in mathematical reasoning.
RAGAM-AI uses Multi-Agent Soft Actor-Critic, or MASAC. Agents associated with edge servers observe resource allocations, resource demands, latency and data rate, then choose CPU, memory and bandwidth allocations. The simulation architecture is described as centralized learning with decentralized execution.
The language model supplies feedback within the reward mechanism; it does not replace the allocation policy. A fixed, system-controlled prompt structures the state information and asks the model to evaluate constraints. The conventional reward component separately awards or penalizes constraint satisfaction using empirically chosen weights.
To reduce reliance on language-model inference, the framework also trains a smaller neural network on state-reward examples obtained from the language model. This surrogate is used after its prediction error meets a threshold. The intended benefit is to retain an approximation of the feedback without repeatedly running the larger model. The paper does not establish that this eliminates reward bias or solves reward generalization in general.
Smaller allocation gaps in simulation
The experiments use preprocessed Microsoft Azure Packing traces as resource requests. The authors describe removing incomplete or invalid records and organizing workload identifiers and timestamps. Their training setup lists 25 episodes with 512 steps per episode.
RAGAM-AI is compared with single-agent Soft Actor-Critic using a conventional reward, the REINFORCE policy-gradient method, and random allocations constrained by server capacity. Allocation deviation measures the gap between demand and allocation, normalized to total capacity; lower values are preferable.
The summary table reports CPU deviation of 23.65% for RAGAM-AI, compared with 28.61% for SAC, 32.53% for REINFORCE and 44.93% for random allocation. Memory deviation is 20.36%, against 24.35%, 24.68% and 46.37%, respectively. Bandwidth deviation is 20.40%, against 25.27%, 26.5% and 46.92%.
The authors also report lower latency and data-rate costs. These are resource-aware cost measures, not simply raw latency or throughput. Differences against the learning baselines are comparatively small in the summary table: latency cost is 0.00670 for RAGAM-AI and 0.00672 for SAC, while data-rate cost is 115.1 million and 115.3 million, respectively. These results should not be read as equivalent percentage improvements in user-facing speed.
What the evidence leaves open
The paper examines reward repeatability by querying 50 random states five times each and presenting detailed statistics for three states. Those examples have reward standard deviations of 0.06 to 0.08. Repeatability provides information about variation across calls, but does not by itself establish that a reward correctly captures operational priorities.
The comparison also changes both the agent architecture and the reward mechanism between RAGAM-AI and the single-agent SAC baseline. It therefore does not separately identify how much improvement comes from language-model feedback versus the multi-agent design.
Several practical boundaries remain. All incoming requests are assumed admitted, leaving admission control outside the study. The authors acknowledge a larger spread in some RAGAM-AI results and interpret it as greater exploration during training. Runtime-overhead measurements, sensitivity studies, further convergence analysis and cloud-native deployment are identified as future work.
The demonstrated result is consequently narrower than a general solution to autonomous network management: this hybrid design achieved better reported allocation matching and lower costs under the tested simulation conditions. Whether its feedback mechanism remains economical and effective in deployed, larger-scale systems still requires evaluation.
- RAGAM-AI
- edge computing
- resource allocation
- multi-agent reinforcement learning
- Soft Actor-Critic
- MathΣtral
- AI feedback
- surrogate reward model