TRANSMISSION // 2611.06449v1
A New Benchmark Tests Whether AI Can Rebuild Documents as Editable HTML
Source published
The AmbiHTMLBench preprint evaluates document-to-HTML reconstruction across 1,115 pages. Its automatic and human-calibrated visual rankings favor different models, highlighting the distinction between accurate content and perceived appearance.
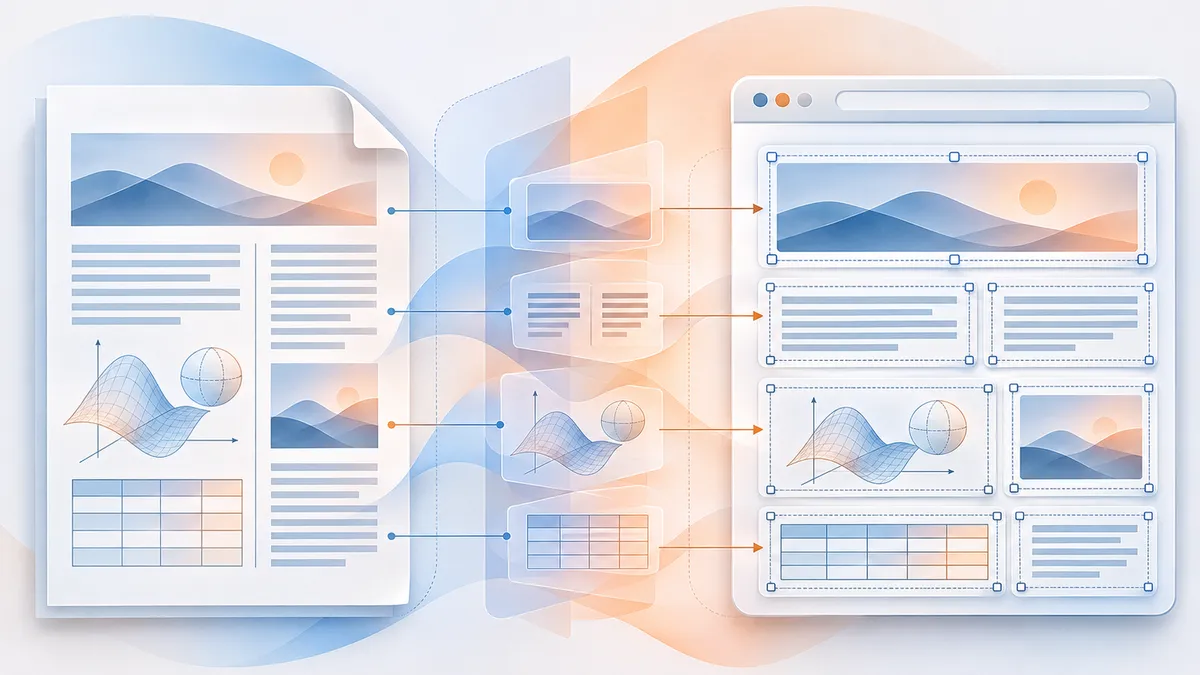
Extracting words from a document is not the same as reconstructing the page. A new preprint proposes a benchmark that asks multimodal AI systems to recover both the content and the visual organization of documents as renderable HTML.
A report’s columns, a table’s cells and a poster’s visual emphasis all carry information that can be lost when a page is reduced to a stream of text. In the AmbiHTMLBench preprint, Boyu Niu and colleagues propose testing whether AI systems can instead turn document images into HTML that preserves content, organization and appearance.
The choice of output format matters. Markdown can represent headings and simple tables, but it does not necessarily retain a page’s precise spatial arrangement. HTML provides elements for structures such as headings and tables, while CSS controls aspects of their presentation. The resulting artifact can be rendered in a browser and its individual elements can, in principle, be inspected or edited. The benchmark tests reconstruction itself, rather than establishing that the outputs succeed in every downstream use.
From varied pages to a test set
The researchers assembled 1,115 expert-annotated pages from sources including institutional reports, web documentation, newspapers, magazines and designed posters. The pages include features such as columns, tables, formulas and mixed media.
To select them, the team began with more than 50,000 candidates, removed pages with unusable initial parsing or fewer than 50 words, and grouped pages by layout. A diversity filter reduced redundancy before expert review removed examples such as overly simple or truncated pages. These choices make the benchmark a focused test of relatively text-rich, visually structured material, not a sample of every kind of document.
Experts recorded page-level characteristics and block-level content. Tables were annotated in HTML and formulas in LaTeX, a format for mathematical notation. The resulting references support comparisons of what a model transcribes as well as where it places elements.
Measuring more than one kind of fidelity
For the objective evaluation, each generated HTML page is rendered in a browser at a fixed viewport. The evaluator extracts visible blocks and matches them to reference annotations. It then measures text differences, table fidelity and layout consistency.
The matching procedure allows for a practical complication: a model might split one reference paragraph into several HTML blocks or merge several blocks into one. Table content can receive text credit even if it has been flattened, but table-structure credit requires a preserved table object. Layout scoring compares the positions and sizes of matched regions and their two-dimensional relationships. The reported table measure uses a row-and-cell edit approximation rather than a full HTML tree comparison.
The second protocol asks which of two reconstructions looks more faithful to a reference. Human participants judged a set of comparisons, and the researchers fitted a proxy that combines votes from five vision-language models to approximate those preferences. Photograph and chart interiors were neutralized for these judgments, although their placement and geometry remained relevant. The resulting ranking is therefore a measure of perceived reconstruction fidelity under that protocol, not a direct test of whether image or chart content was reproduced correctly.
Different leaders, different strengths
In the objective table, Gemini 3.1 Pro Preview leads with a weighted score of 0.8092. The aggregate gives weight to text and layout and a smaller weight to table fidelity; its components make it possible to see strengths that a single score can obscure.
The subjective ranking instead places GPT-5.6 Sol first among the ten systems in that comparison. This is a proxy-based ranking: most of the additional comparisons were scored by model judges rather than independently labeled by people. Although internal tests found substantial agreement between the proxy’s model ranking and the human ranking, those tests used repeated judge votes, whereas deployment used single votes. They do not independently validate the expanded leaderboard.
One example illustrates the distinction. On a page where an objective comparison favored Claude Opus 5 for both text and layout, the recorded proxy favored GPT-5.6 Sol. The latter preserved red emphasis but changed wording; the former kept the wording but lost the emphasis. The example shows how a visually persuasive reconstruction can still contain a meaningful content error.
Can a smaller model learn the task?
The authors also adapted two smaller Qwen models using examples from a separate document set. A larger model generated transcription-style HTML targets, which were filtered before fine-tuning. Both adapted models improved on the benchmark’s weighted objective score; the 9-billion-parameter model rose from 0.6623 to 0.7064. The paper also reports that the format of training targets mattered in a separate comparison.
The work presents a diagnostic framework rather than a guarantee of faithful conversion. Its central lesson is that readable text, preserved structure and convincing appearance are related but distinct goals—and that evaluating only one can conceal failures in the others.
- AmbiHTMLBench
- document parsing
- HTML
- multimodal AI
- benchmark
- layout reconstruction
- visual fidelity