TRANSMISSION // 2611.06425v1
D3D overlaps drafting and verification to speed up language-model decoding
Source published
A preprint reports that a standalone diffusion drafter can prepare possible continuations while a language model checks its current draft. In tests on seven benchmarks, D3D averaged 5.00× and 5.71× decoding speedups for Qwen3-8B and Qwen3-32B, respectively, under a two-GPU setup.
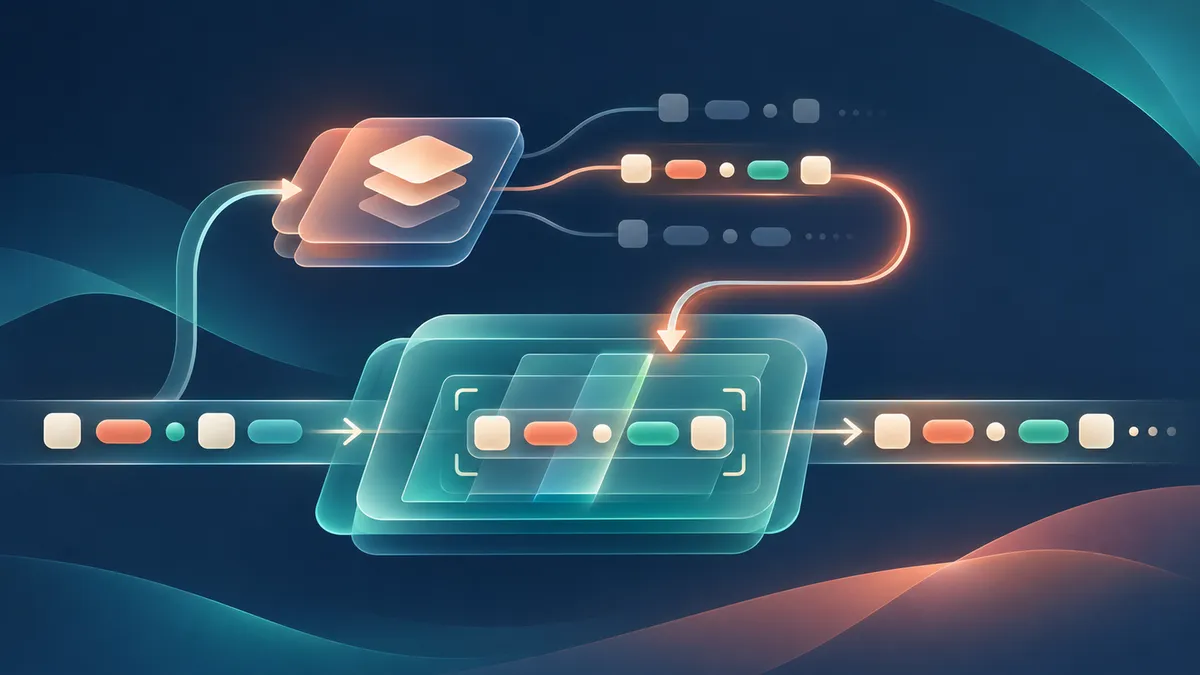
Generating text one token at a time can leave expensive computing hardware waiting. A new preprint proposes D3D, a method that tries to make better use of that time by predicting several possible continuations while the main language model verifies an earlier prediction.
Guessing ahead without waiting
Speculative decoding uses a draft model to suggest future tokens—the pieces from which a language model builds text—and a larger target model to check them. If the suggestions match what the target can accept, several tokens can be added in one verification round. With the appropriate acceptance rule, the procedure preserves the target model’s output distribution.
Some existing diffusion-based drafters predict a block of tokens in parallel but need fresh internal representations from the target before drafting the next block. That dependency makes the drafter wait for verification to finish. In their preprint, Baoyou Chen and colleagues propose a standalone drafter that instead builds its own representations from the token prefix.
D3D uses that independence to prepare several possible next blocks while the target checks the current one. Each prepared branch anticipates a possible point of rejection and a possible replacement token, or the acceptance of the full block. If a branch matches the verified prefix, its remaining draft can be reused. If none matches, the target must wait while a new block is drafted synchronously.
Preparing more branches improves the chance of a match, but also costs computation. In one AIME25 test, increasing position coverage raised the cache-hit rate from 71.3% to 78.3% yet reduced speedup. The useful balance depends on whether the packed drafting work can finish within the target’s verification time.
Training and trimming the drafter
The researchers initialize D3D from a pretrained language model and train it on responses generated by the target. One objective teaches it to predict masked positions within a block simultaneously. A second teaches ordinary next-token prediction from unmasked prefixes. The training gives extra weight to earlier block positions, because verification stops accepting candidates at the first rejection.
In a smaller-model ablation with Qwen3-8B as the target, adding the auxiliary next-token objective increased average acceptance length by 0.24 to 0.40 tokens across four benchmarks compared with diffusion-only training. The paper defines acceptance length as the mean number of output tokens added per verification round, including the token produced by the target.
The team also removes drafter layers progressively. At each stage, it tests which layer’s removal least reduces validation acceptance length, removes that layer, and performs recovery training before reassessing the remaining layers. With Qwen3-8B as target, reducing the drafter from 36 to 31 layers retained over 99% of mean acceptance length across MATH-500, HumanEval and MT-Bench. Mean speedup on those three benchmarks rose from 4.44× to 4.69×; further pruning reduced both acceptance and speedup.
What the benchmarks showed
The main evaluation covers seven mathematics, coding and dialogue benchmarks. It uses a 31-layer D3D-8B drafter with a block size of 16, and measures decoding speed relative to ordinary autoregressive decoding of the target model.
Across the seven benchmarks, D3D averaged 5.00× speedup with Qwen3-8B and 5.71× with Qwen3-32B. DFlash averaged 4.03× and 3.67×, respectively. The highest reported D3D result was 7.48× on GSM8K with Qwen3-32B. D3D had the highest average speedup among the evaluated methods for both targets, although it was fastest on five of seven individual benchmarks with the 8B target and all seven with the 32B target.
D3D’s average acceptance lengths were 7.88 and 7.73 tokens per round for the 8B and 32B targets, compared with DFlash’s 5.96 and 4.82. Longer acceptance did not invariably mean faster decoding: larger blocks and more prepared branches also add work.
The hardware comparison matters. D3D and the asynchronous SSD and PARD-2 baselines used two NVIDIA H800 GPUs, while the synchronous DFlash, DSpark and EAGLE-3 baselines used one. Evaluations used the Transformers backend, greedy decoding and non-thinking mode. The authors did not compare throughput per GPU with alternatives using the same two-GPU budget, such as tensor-parallel target inference.
A separate serving test used a smaller D3D-1.7B drafter with Qwen3-32B. At 16 concurrent requests, aggregate throughput reached 864 tokens per second on MATH-500, a 2.7× gain, and 386 tokens per second on MT-Bench, a 1.5× gain. Relative speedups declined as concurrency increased, underscoring that single-request results do not describe every serving workload.
A separate long-context trade-off
The preprint also tests using D3D to select parts of a long prompt before target processing, followed by sequential speculative decoding. This is distinct from the main full-prompt asynchronous method: removing prompt content can change the target’s output.
On LongBench single-document question answering, an 8B drafter retaining 10% of the prompt achieved a score of 47.05 and 3.32× end-to-end speedup, versus 47.91 and 1.40× with full-prompt D3D. Other categories and retention levels showed different score–latency trade-offs. The authors identify production-framework evaluation as future work, so the reported gains should be read as results for the tested models, benchmarks and implementation rather than a general deployment guarantee.
- D3D
- speculative decoding
- diffusion drafting
- asynchronous inference
- language models
- layer pruning
- Qwen3