TRANSMISSION // 2611.06282v1
MonoLaDN teaches a camera-only 3D detector with language it won't need at runtime
Source published
MonoLaDN uses vision-language descriptions as an auxiliary training signal for monocular 3D detection. The authors report improved KITTI results without adding inference cost, alongside substantial offline generation and training overhead.
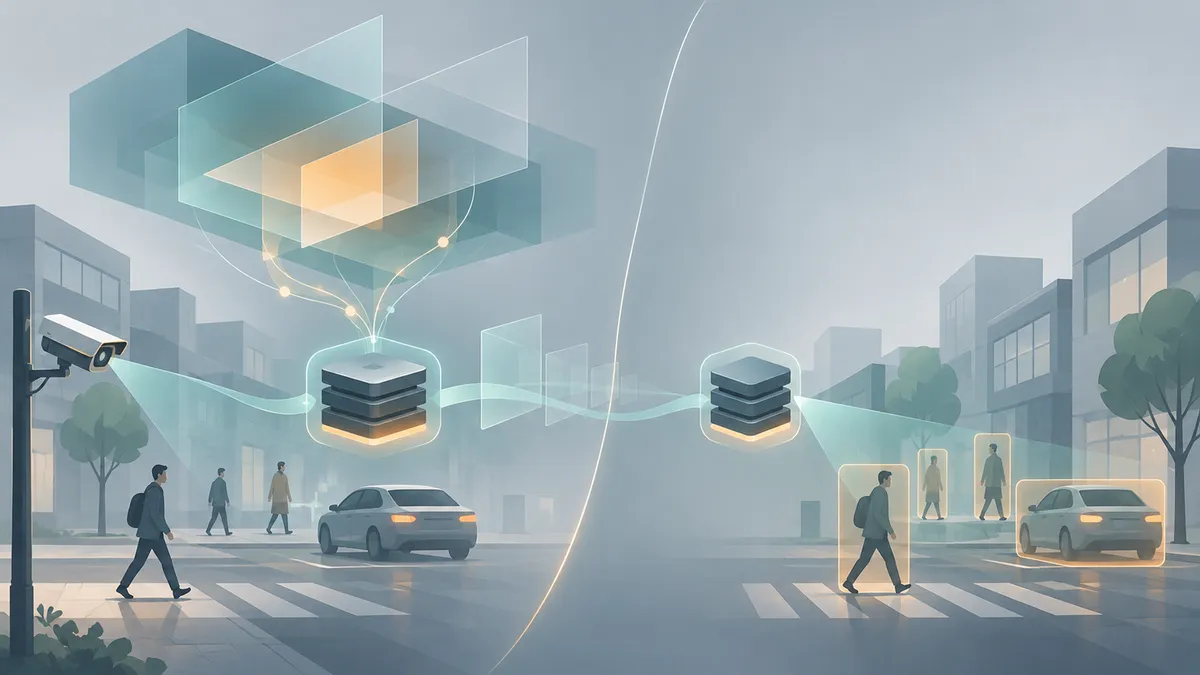
A single camera image can show a car, but it does not directly reveal the car's distance or three-dimensional shape. MonoLaDN tries to make those estimates better by using a vision-language model as a training-time teacher, then removing it before the detector is deployed.
From a flat image to a 3D box
Monocular 3D detection estimates an object's location, dimensions and orientation from one image. It is attractive for camera-based perception, but the same image can be consistent with multiple 3D scenes. Distant objects, overlap and objects cut off by the image edge make the missing depth especially difficult to infer.
Kiet Dang Vu and colleagues propose MonoLaDN, a training scheme built on the MonoDGP camera-only detector. Their idea is to use a vision-language model (VLM) to create object-specific descriptions of geometric cues, and use those descriptions to train a detector that will not need language at inference. The version discussed here is arXiv preprint 2611.06282v1; its arXiv landing page says the paper was accepted at ACCV 2026.
A teacher that sees the answers
The teacher is not asked to discover 3D geometry from scratch. For each annotated training object, the pipeline uses the scene image, an object crop and a view with the background dimmed. It also draws on ground-truth annotations to describe four attributes: visibility or occlusion, distance, shape and viewing angle. For example, numerical depth is placed into distance bins, while orientation is mapped to viewpoint categories. A frozen VLM generates concise evidence sentences about the visual cues associated with the attributes.
The main paper describes the VLM as conditioned on annotation-derived labels. The supplement also describes a label-selection prompt before evidence generation, leaving some ambiguity about how the selected labels relate to the annotation-derived labels. In either description, this is supervised training using ground-truth information, not proof that the VLM independently measures accurate 3D boxes.
A text encoder converts the four pieces of object reasoning into separate numerical embeddings. The method perturbs those embeddings with learned Gaussian noise and feeds them as auxiliary queries into the detector's depth-guided transformer, alongside its ordinary detection queries. Training asks the model to reconstruct the clean embeddings and the associated object box, while retaining the baseline's detection loss. The authors' hypothesis is that these auxiliary tasks encourage the shared detector to learn useful geometric cues.
The attention mask is important because the auxiliary queries originate from ground truth. It prevents ordinary detection queries from attending to the reasoning queries, limiting a shortcut that would disappear at inference. It also allows a reasoning query to attend to related attributes of the same object, the same attribute across objects, and ordinary queries, while blocking unrelated object-attribute pairs. Once training is complete, the language path and its queries are removed. The deployed model takes an image, not a VLM explanation or a ground-truth box.
What the experiments show
On the KITTI car test set, the authors report 3D average precision at 40 recall positions of 29.67, 20.45 and 18.02 for the easy, moderate and hard categories. The MonoDGP baseline reports 26.35, 18.72 and 15.97 respectively. These are gains of 3.32, 1.73 and 2.05 percentage points on that metric, not proportional increases in real-world driving safety. The paper also reports KITTI test results for pedestrians and cyclists; at moderate difficulty, their 3D average precision is 10.81 and 4.45 respectively.
Ablations support the value of the training design on KITTI validation cars. With the same Qwen-based teacher and SigLIP text encoder, combining embedding and box reconstruction gives 23.61 moderate 3D average precision; adding the separated-reasoning mask raises it to 24.52. In a separate mask comparison, removing the leakage-prevention mask drops the score from 23.61 to 10.92. These comparisons show the components matter in the reported setup, although they do not establish exactly what knowledge the detector has internalized.
For a narrower test of domain shift, the researchers evaluate a KITTI-trained model without fine-tuning on cars in the nuScenes frontal validation set. Its overall depth mean absolute error is 1.28, compared with 1.26 for DEVIANT and 1.40 for MonoCon in the paper's comparison. It is therefore competitive, not uniformly best, on this cross-dataset measure.
The cost is shifted, not eliminated
The authors report that MonoLaDN and MonoDGP each have 42.16 million deployed parameters and run in 42.4 milliseconds per image on an RTX 3090 at batch size one. This supports the no-added-inference-cost claim for the measured setup, not a universal latency guarantee.
Training is more expensive: reported time rises from 4.68 to 5.23 minutes per epoch and peak memory from 14.35 to 20.45 GB. The supplementary table also reports 230.6 hours to generate the cached reasoning with the selected SpaceThinker teacher. That offline work is separate from repeated training epochs.
The study focuses on single-image detection; multi-view and temporal extensions remain future work. KITTI and the limited nuScenes transfer evaluation cannot establish performance across all environments, camera systems or safety-critical cases. The results make a case for training-time language supervision, while the claim that specific VLM reasoning is retained inside the vision-only detector remains the authors' interpretation rather than a direct measurement.
Source: Vu and colleagues, MonoLaDN: Language-Guided DeNoising for Monocular 3D Object Detection, arXiv:2611.06282v1, including its supplementary material.
- monocular 3D detection
- vision-language models
- denoising
- knowledge transfer
- KITTI
- computer vision
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
Teaching diffusion models to do more with fewer decoding steps
Source published
Shared keywords: vision language models
Researchers examine multi-camera strategies for luggage re-identification
Source published
Shared keywords: computer vision
AuroraWorld turns outside-camera footage into synthetic robot-eye videos
Source published
Shared keywords: computer vision
Teaching vision transformers where finer image patches matter
Source published
Shared keywords: computer vision
Visual AI Models Show Uneven Ability to Maintain Spatial State
Source published
Shared keywords: computer vision