TRANSMISSION // 2611.06254v1
HarnessFlow searches for better AI-agent software without changing the model
Source published
A preprint reports that tree-guided search can improve the software controlling an AI agent’s memory, tools and execution. Across six benchmarks, HarnessFlow achieved the highest mean test scores among the compared methods, although its reported execution savings exclude the cost of searching for better designs.
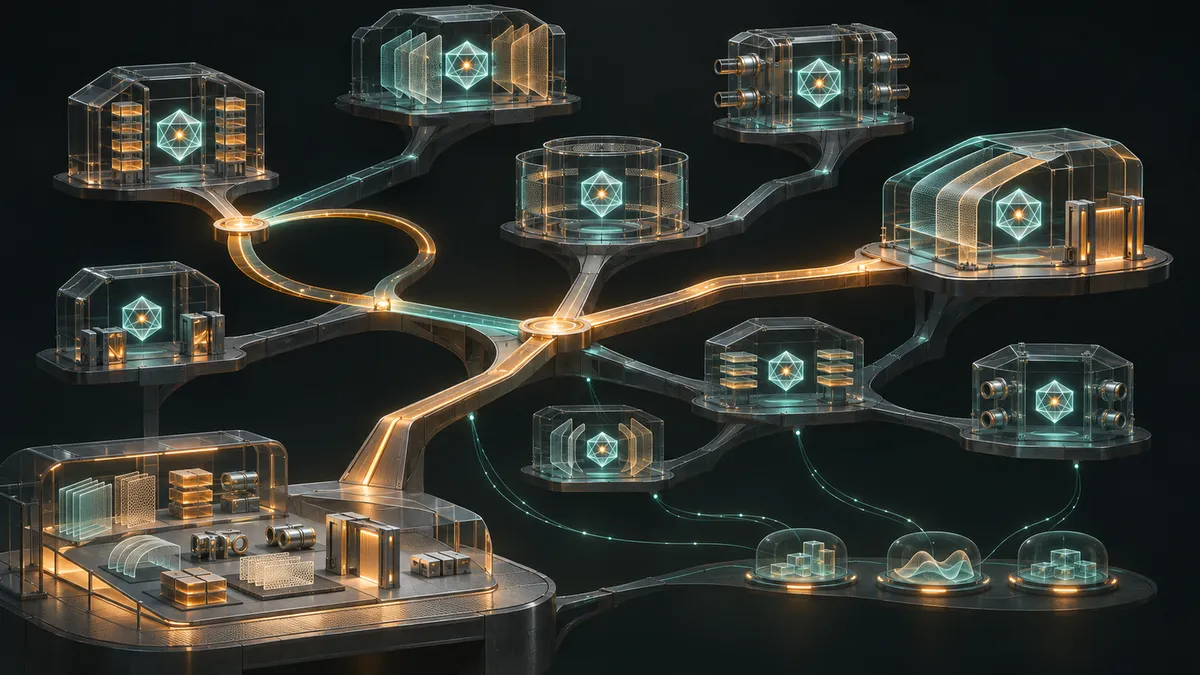
An AI agent’s results depend on more than its language model. The surrounding software decides what information to retain, when to use tools and when to stop. HarnessFlow turns the design of that software into a structured search, preserving earlier versions so a coding agent can revisit promising alternatives.
Improving an AI agent does not necessarily require training a new model. It can also mean changing the software that manages the model’s interaction with its environment. In a November 4 preprint, Zhi Hong and colleagues introduce HarnessFlow, a system that searches for better versions of this surrounding software while keeping the executing model and task environment fixed.
The authors call that software a harness. It constructs the model’s input, retains task state, invokes tools and controls execution. These responsibilities interact: adding a verification step, for example, may also require remembering additional evidence and changing the rule for ending a task.
HarnessFlow therefore edits complete executable codebases rather than choosing only among predefined prompts or settings. Its central question is how to spend a limited number of expensive evaluations on useful design changes.
Keeping alternative designs alive
The system stores harness versions in a refinement tree. Each node contains a particular implementation, its measured validation score and records of its execution. A branch records which earlier version was modified to produce a new candidate.
An approach based on Monte Carlo Tree Search chooses which version to refine next. It first shortlists up to five of the highest-scoring versions. Within that shortlist, it mixes two preferences: higher validation scores and fewer previous direct expansions. This balances developing successful designs against trying less-explored alternatives, though exploration remains restricted to the shortlist.
A separate coding agent decides what to change. In the experiments, this was Codex running GPT-5.5 at its highest reasoning effort. It could inspect archived implementations, scores and execution traces, including evidence from other branches. An optional library supplied reusable mechanisms for memory, context management, control flow and tool interfaces.
Each proposed candidate consumed one of 15 refinement attempts per benchmark. Valid candidates joined the tree; earlier implementations retained their directly measured scores. After search, the system selected the version with the highest observed validation score for evaluation on a disjoint test set.
What the experiments found
The main comparison used GPT-5.4-mini at medium reasoning effort to execute every harness. The six benchmarks covered interactive tool use, application tasks, web interaction and coding: TAU2-bench, AppWorld, WebShop, BrowseComp-Plus, SWE-bench Verified and BigCodeBench-Hard.
Comparisons included each benchmark’s starting harness, four hand-engineered agent systems and Meta-Harness, another full-code optimization method. The authors report matching the executor, benchmark-tool access and per-task resource limits. Meta-Harness also received the same coding agent and candidate budget. Scores were reported over five repeated executions, rather than five independently repeated optimization searches.
HarnessFlow achieved the highest mean test score on all six benchmarks. Its six-benchmark average was 69.48%, compared with 58.59% for the starting harnesses and approximately 65.5% for Meta-Harness. That represents a 10.89-percentage-point gain over the initial designs and roughly four points over Meta-Harness. The average combines different benchmark metrics, including task success, software-issue resolution and answer accuracy; it is not a universal success rate.
One software-repair example illustrates the changes involved. A retained lineage added local repository-history retrieval, compatibility fixes for older Python interpreters, symbol-based retrieval and more compact submission patches. Its validation score rose from 67.60% to 79.20%. Those scores describe cumulative designs, not isolated measurements of each edit’s contribution.
Savings with qualifications
The reported execution costs were also favorable on average. Using the arithmetic mean across benchmarks, HarnessFlow cost $0.232 per test task, versus $0.398–$0.555 for three hand-engineered systems and $0.561 for Codex. It was not cheapest on every benchmark. These estimates price executor input and output tokens and exclude the one-time harness-search cost.
Supporting experiments found that removing the component library reduced performance on a three-benchmark subset, while mixing exploration and exploitation outperformed either selection signal alone on another three-benchmark comparison. With GPT-5.4 as executor, rerunning search produced the highest average across three benchmarks, but not the highest score on every individual benchmark. That experiment does not demonstrate unchanged harnesses transferring between models.
The authors identify important boundaries: optimization requires an automatic grader, evaluations consume compute, and each candidate has only one recorded parent. Graph-based ancestry remains future work, although the coding agent can already consult other branches. The preprint says implementation and reproduction scripts will be released. Its results support structured harness search under the tested conditions—not a guarantee of optimal designs or lower total costs in deployment.
- HarnessFlow
- LLM agents
- harness optimization
- Monte Carlo Tree Search
- coding agents
- agent benchmarks
- execution costs