TRANSMISSION // 2611.06219v1
When Does Poor AI Performance Become Catastrophic?
Source published
A theoretical preprint proposes measuring AI catastrophe against two reference points: what would happen without deploying the system, and what would remain if the environment’s evolution were unrelated to human preferences. The aim is to distinguish missed opportunities from the destruction of conditions people value.
An AI assistant that achieves less than it could has not necessarily caused harm. Even one that breaks something has not necessarily caused a catastrophe. A new preprint asks how mathematical theories of AI alignment can distinguish those cases—and proposes judging severe failure by how much human-valued progress is undone.
An AI system can fall short of perfection while still being useful. It can also cause enormous damage without deliberately seeking to hurt anyone. Those distinctions motivate A Definition of Catastrophic Performance, a theoretical preprint by Henrik Marklund, Alex Infanger and Benjamin Van Roy, posted on November 4, 2026.
The authors propose a mathematical scale intended to separate merely disappointing performance from catastrophic loss. Their central idea is to compare AI outcomes not with perfection or maximum possible harm, but with the benefits already present in an environment and those expected to develop without the AI.
Two reference points instead of perfection
The paper argues that familiar performance comparisons miss important distinctions. Measuring an agent against the best possible outcome reveals missed opportunities, but does not establish whether deployment helps or hurts. Comparing it with the worst possible outcome instead evokes a knowledgeable, malicious agent deliberately pursuing what people most dislike.
The authors focus on a different concern: an agent pursuing an inadequately specified objective and causing severe damage as a byproduct.
Their first reference point, baseline value, is the expected value of what happens if the AI is not deployed. This is not necessarily a frozen world. People can continue working, improving their surroundings and pursuing their goals. Performance below that baseline is detrimental, but a robot knocking over a vase illustrates why that alone is insufficient to establish catastrophe.
Their second reference point, orthogonal value, is more abstract. It evaluates a sequence of environmental states drawn independently of the reward function representing the designer’s preferences, using the simplest possible distribution under a specified programming language.
Here, simplicity means the length of the shortest program describing the distribution—not how orderly or attractive the resulting world looks. A uniform distribution over configurations can be simple, but so can a distribution concentrated entirely on one easily described configuration.
Measuring the loss of valued conditions
The motivation is that an environment often already reflects human preferences. Buildings, parks and other desirable arrangements embody past effort. Continued human activity can preserve or improve them. The paper also notes that favorable conditions need not originate in human action: people’s preferences can reflect the environment in which humans evolved.
An orthogonal trajectory removes the connection between those preferences and the states being evaluated. The authors interpret the gap between baseline and orthogonal value as the loss of favorable conditions and their expected continuation.
They define a degree of catastrophe using a parameter, eta, between zero and one. Performance qualifies when it falls at least eta of the way across that gap, or farther. At eta zero, the threshold is the baseline itself; at eta one, it is orthogonal value.
This scale is meaningful only when baseline value exceeds orthogonal value. It concerns expected performance assessed before the designer’s deliberation in constructing the agent, averaging over uncertainty—not simply the severity of one observed incident.
What the examples establish
The mathematical setup uses Markov decision processes: environments described by states, actions, transition probabilities and rewards. Rewards and a discount factor represent preferences over future trajectories. The uncertainty belongs to the designer, including uncertainty about how to specify preferences. An appendix extends the definitions to partially observable environments.
A toy gridworld supplies a calculable example. Its boundaries wrap around, and rewards favor proximity to a randomly selected desirable location over proximity to an independently selected undesirable one. The starting state and no-AI dynamics favor the desirable location. Under this construction, the authors derive an orthogonal value of zero and a positive baseline value. One numerical illustration gives a baseline of approximately 7.8.
That calculation establishes a separation within the model, not that traversing a grid constitutes a recognizable human catastrophe.
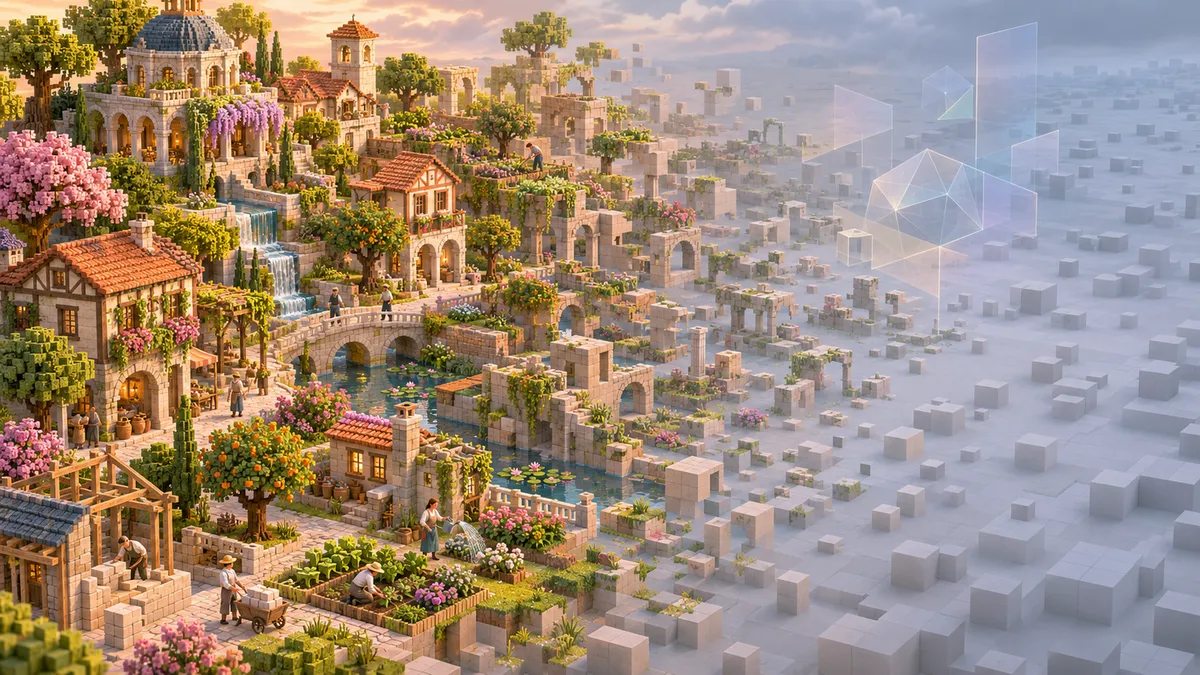
For intuition, the authors turn to Minecraft. A person has spent a long time building a desirable city. Arbitrary block configurations are unlikely to preserve its sophisticated structures. Losing those structures can be catastrophic without producing the particular city the person would most detest.
A definition, not a risk forecast
The Minecraft discussion is an informal argument, not an experiment demonstrating destructive AI behavior. The authors also acknowledge that simplicity depends on the programming language. Specially constructed languages can make an ideal state exceptionally easy to describe; their broader justification for ordinary languages remains an open research question.
The preprint therefore offers a proposed vocabulary and mathematical reference scale, not a probability estimate for future AI catastrophe. Its contribution is to make explicit a distinction that optimal-performance comparisons can obscure: failing to improve the world is different from undoing what makes it valuable.
- AI alignment
- catastrophic performance
- baseline value
- orthogonal value
- reward specification
- Markov decision processes
- algorithmic complexity