TRANSMISSION // 2611.06123v1
Teaching Alexa+ Icon AI to Leave Room Between the Lines
Source published
A preprint from University of Southern California and Amazon Alexa researchers describes reinforcement learning that improves generated icons’ stroke separation. The authors report a single-generation pass rate rising from 15.7% to 58.7%, although a separate results table contains inconsistent counts.
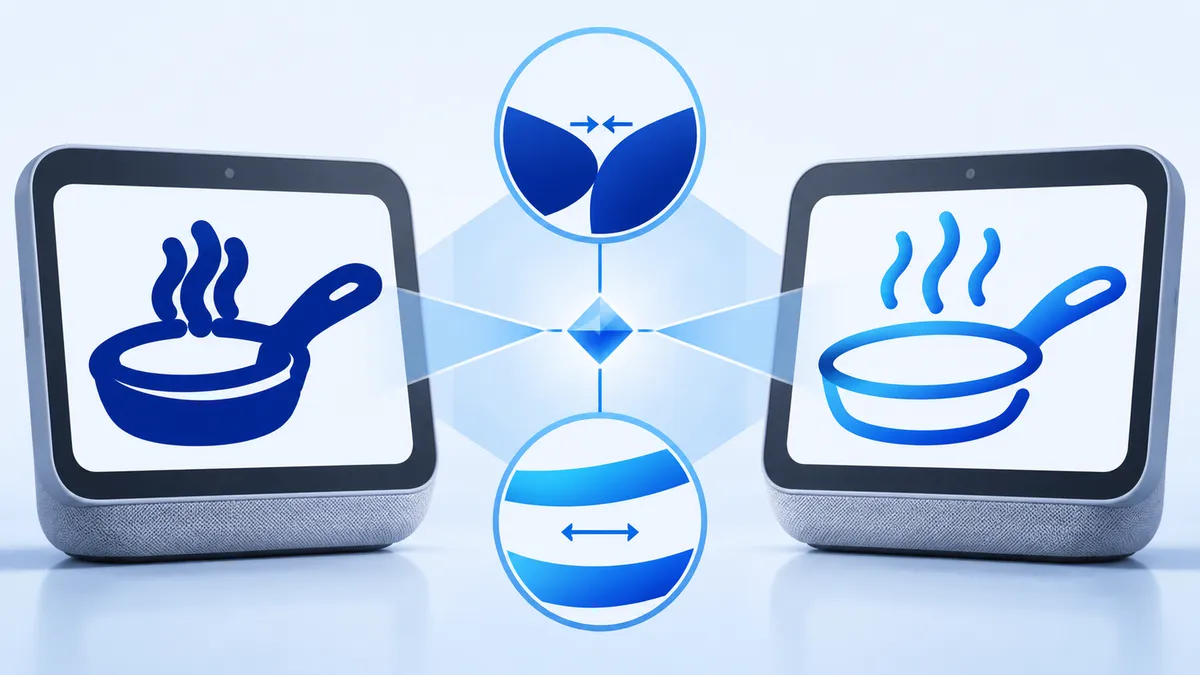
An icon can look crisp at high resolution and become an unreadable blob on a small screen. Researchers working on Alexa+ describe how they trained an image generator to account for that gap, using automated checks to reward drawings whose lines remain distinct at the required display size.
Why a clean drawing can become a blob
Alexa+ devices with screens use animated line-art icons to reinforce conversations: a skillet for cooking, for example, or an umbrella for weather. According to a November 4, 2026 preprint by Rohan Sequeira and colleagues at the University of Southern California and Amazon Alexa, the original hand-drawn collection could not keep pace with open-ended conversation topics.
The team describes a production pipeline that turns text descriptions into vectorised animations. Its central difficulty is not simply generating a recognisable object. The drawing must survive rendering on a small canvas with relatively thick strokes.
At high resolution, neighbouring contours can look comfortably separated. At the required display size and stroke width, those contours can merge into solid shapes. The researchers call this stroke crowding. Because later processing inherits the original geometry, animation and styling cannot repair a structurally overcrowded drawing.
Training against the rendered result
The pipeline first generates black-on-white line art. It then identifies semantic components, separates them into colour-coded parts, converts them into centreline vector paths, applies a blue gradient palette, and produces a Lottie animation for playback.
The research focuses on improving the first stage using FLUX.2 [klein] 4B, a flow-matching image model. The authors say no suitable public dataset of correct line-art icons exists under their rendering constraints. Rather than supervise the generator with target drawings, they use reinforcement learning from verifiable rewards, or RLVR.
Their checking system starts with geometric measurements. It flags gaps narrower than one stroke width, strokes that have fused into oversized regions, and small enclosed holes that would fill in. Thresholds are expressed relative to stroke width rather than fixed pixel distances.
But a narrow gap is not automatically a mistake. Crossed scissor blades or a watch strap meeting its case may require tight spacing. Penalising every such region would teach the generator to remove legitimate structure.
To distinguish defects from intentional geometry, the team trained a gradient-boosted classifier using 3,836 human-labelled regions from 682 generated icons. This distinction matters: the approach avoids requiring target images for generator training, but its verifier still depends on human annotations.
Preventing easy ways to cheat
A reward based only on crowding would invite shortcuts. An almost empty canvas could contain no crowded strokes while failing to depict anything useful. A tidy drawing of the wrong object could also score well.
The reward therefore combines defect counts with penalties for insufficient stroke content and unwanted colour, plus a vision-language model’s assessment of concept fidelity. The semantic checks ask whether the drawing depicts the requested object and whether its strokes remain minimal and uncrowded.
The authors report encountering these shortcuts during development, including near-empty drawings and icons shrunk into a corner. Their final reward gives graded penalties rather than simply rejecting such outputs, preserving a signal for improvement.
Flow-GRPO training updates a low-rank adapter while leaving the base model weights frozen. The training list contains 474 concepts, with another 118 reserved for held-out reward monitoring.
What the evaluation reports
For the main evaluation, the researchers used 1,000 concepts disjoint from the training concept list. Each model generated one image per concept. An independent vision-language judge, Claude Opus 4.6, compared each original drawing with its re-rendering at production stroke width, issuing one pass-or-fail verdict without retries.
The headline result is an increase from 15.7% to 58.7%, or 43 percentage points. This measures passing the stroke-crowding gate on a single generation, not overall approval of a finished animation. The authors also report that adding explicit spacing instructions to the base model did not produce a statistically significant improvement.
One reporting discrepancy deserves attention: the paper’s paired-verdict table implies 197 base-model passes and 687 trained-model passes out of 1,000, which do not reconcile with the headline percentages. The reported rates should therefore be read alongside that unresolved inconsistency.
Better spacing, not unlimited simplicity
The verifier is imperfect. Its held-out macro F1 score is 0.685, and the authors acknowledge that false defect predictions introduce noise into the training reward.
Complex objects remain another boundary. Some require more strokes than the small canvas can accommodate, while excessive simplification can destroy recognisability. The authors propose future rewards that explicitly credit useful concept simplification, alongside training across different rendering scales and stroke widths.
The preprint reports that both the trained model and verifier are deployed in production, with the verifier acting as an automated quality gate before final design review. Its practical lesson is specific: teaching a generator about downstream rendering constraints can improve usable line art, but neither the reward nor the resulting drawings are flawless.
- Alexa+
- line-art icons
- reinforcement learning
- RLVR
- Flow-GRPO
- FLUX.2
- stroke crowding
- vector animation