TRANSMISSION // 2611.06075v1
UniCompress shrinks a multi-skill vision-language model while recovering most task performance
Source published
A preprint reports reducing approximate model-weight storage from 8.9 GB to 2.1 GB while keeping a four-task average score within 0.9 percentage points of its high-precision teacher. The approach combines expert consolidation with training that targets errors introduced by low-bit quantization.
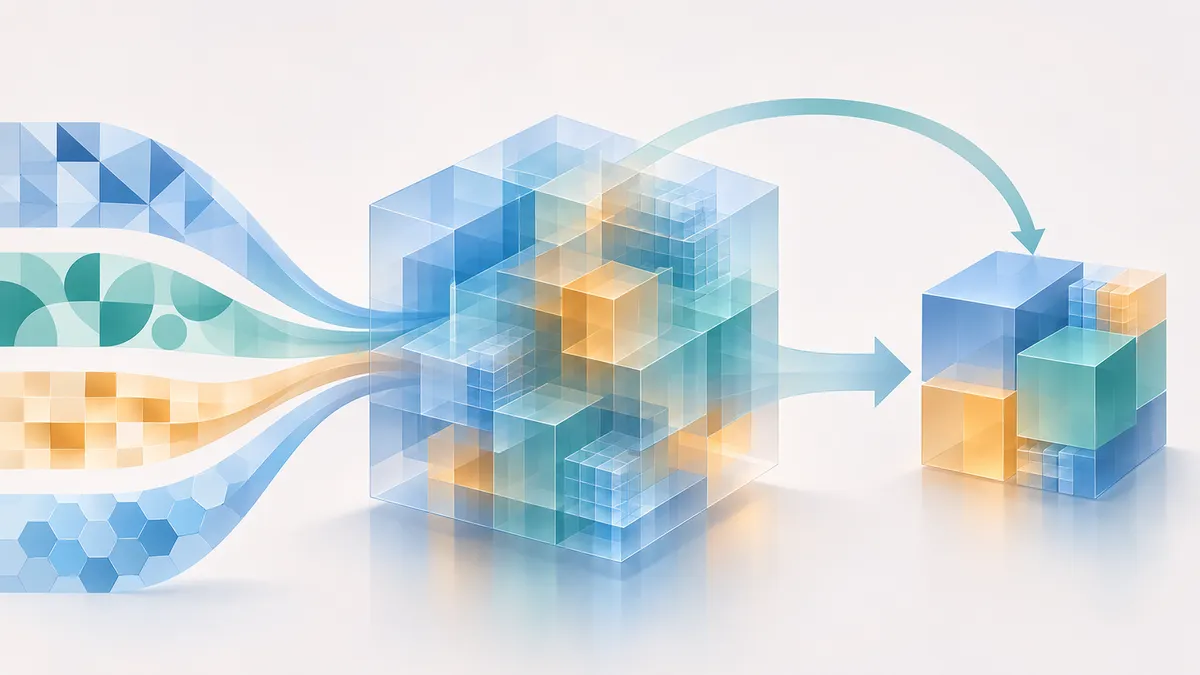
Packing several AI skills into one edge device creates two problems: managing task-specific adaptations and storing the large model underneath them. UniCompress addresses both, first consolidating four specialist adapters and then recovering performance after aggressive mixed-precision compression.
A smaller model is useful only if it can still do its jobs. In the UniCompress preprint, Mingkang Liu and colleagues at Juhaokan Technology report a way to compress a vision-language model while retaining most of its measured performance across four tasks. Their final model uses approximately 2.1 GB of weight storage, compared with 8.9 GB for its high-precision teacher—a reduction of about 76%.
The central result is not compression alone. Direct low-bit quantization sharply reduced performance in the authors’ experiments. UniCompress adds training designed to repair that damage, bringing the compressed model’s average score close to the teacher’s. These are results from the authors’ task suite, not evidence that every capability of the original model survives compression.
First combine the skills, then shrink the weights
The starting system uses Qwen3-VL-4B with four task-specific LoRA adapters. These are lightweight adaptations attached to a shared model, but each must still be stored and selected for the appropriate task. Together, the four adapters add roughly 0.2 GB to the backbone’s approximately 8.9 GB of weights.
UniCompress first has each specialist generate responses for its own task data. An adapter-free model then learns from the combined responses. This produces the consolidated BF16 teacher: one high-precision model that serves all four tasks without switching adapters.
That step removes adapter storage and selection, but it does not shrink the backbone. The second stage addresses that larger cost through quantization, which represents weights using fewer bits.
Importantly, the model called “INT2” is mixed-precision, not uniformly two-bit. The method specifies four-bit projection weights in the vision encoder and two-bit projection weights in the language backbone. Embeddings, normalization layers and the language-model output remain in BF16. That distinction matters when interpreting both the compression claim and the remaining storage.
Repairing errors along the model’s own path
The student starts from GPTQ-quantized weights and learns under simulated low-bit quantization. The teacher provides two complementary forms of supervision.
One uses annotated responses to keep the student anchored to task knowledge. The other lets the quantized student generate its own responses, then asks the teacher to supervise predictions along those student-generated sequences.
The reason is sequential: an early prediction changed by quantization can alter the context for every prediction that follows. Training only on fixed reference responses may miss the situations that the compressed model actually encounters when generating an answer.
A floating-point “shadow” version shares the student’s underlying trainable weights but temporarily bypasses quantization. Comparing its predictions with the quantized student’s helps identify positions especially sensitive to compression. Training gives those positions more emphasis. Neither the shadow policy nor the teacher is included in the deployed model.
What the experiments show
The authors evaluate four in-house datasets: sitting-posture classification, household-safety labeling, choosing which camera input a TV assistant needs, and predicting the next Android interface action. Their headline score is the unweighted average of the four task metrics, rather than a pooled accuracy over all examples.
The original specialist system scores 93.6%, and the consolidated BF16 teacher scores 93.7%. Direct GPTQ-INT2 quantization drops that average to 58.5%. UniCompress raises it to 92.8% at the same approximate 2.1 GB weight storage: a recovery of 34.3 percentage points and a remaining gap of 0.9 points to the teacher.
The losses are uneven. Mobile-interface action accuracy falls from 87.7% for the teacher to 17.8% after direct quantization, then recovers to 85.4% with UniCompress. The recovered model slightly exceeds the teacher on household safety and camera routing, but remains below it on posture recognition and mobile actions.
Experiments separating the training signals yield averages of 91.4% for offline supervision alone and 91.9% for student-generated trajectories alone, versus 92.8% together. This supports combining the signals in this setting; it does not separately establish how much the shadow-based weighting contributes.
Storage savings are not a complete deployment benchmark
The evidence covers one backbone and four in-house datasets. Recovery training uses an NVIDIA A100 80GB GPU, and the paper reports a fixed random seed rather than variation across repeated runs.
The size figures describe approximate weight storage and exclude tokenizer and configuration files. They are not measurements of total running memory, device latency or energy consumption. The preprint therefore supports a narrower conclusion than universal edge readiness: teacher-guided recovery can preserve much of this model’s measured multi-task behavior after aggressive mixed-precision compression.
- UniCompress
- vision-language models
- model compression
- mixed-precision quantization
- knowledge distillation
- LoRA
- edge intelligence
- on-policy distillation