TRANSMISSION // 2611.05997v1
Taobao researchers recycle unseen recommendations to broaden video discovery
Source published
A preprint from Alibaba researchers describes URED, a system that gives highly scored but unshown videos another chance to enter Taobao’s recommendation pipeline. The authors report significant gains in category discovery, content richness and completed video views without retraining models; the increase in total views was not statistically significant.
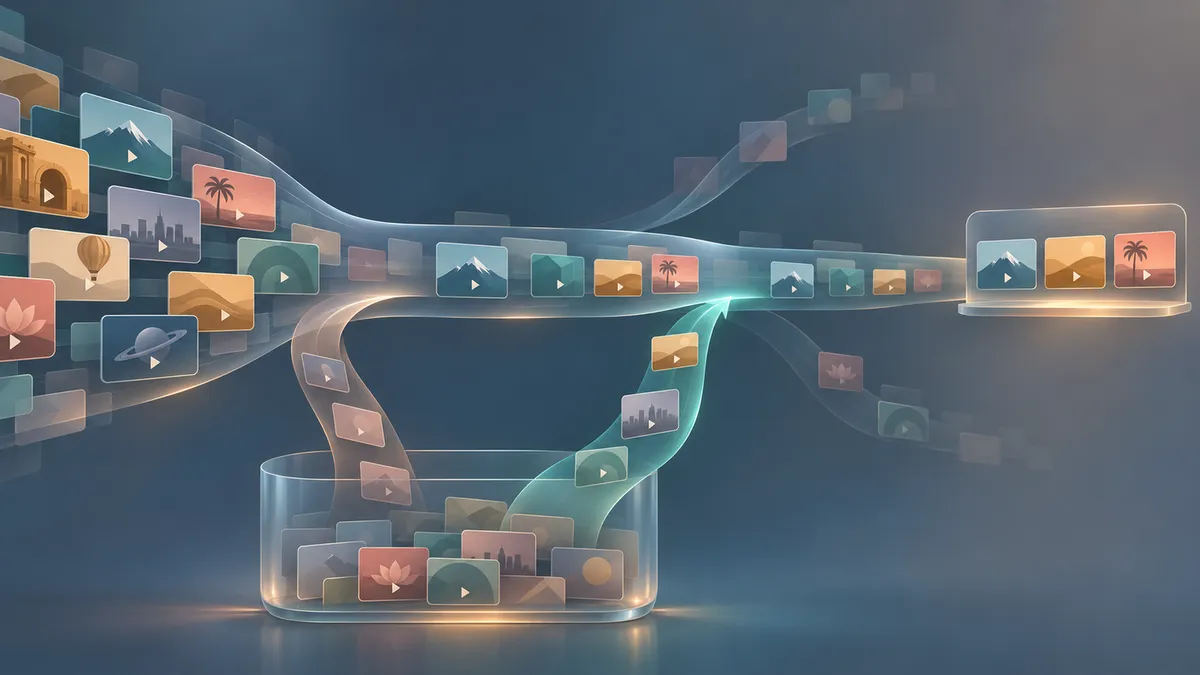
A recommendation system can identify promising content and still never show it. URED turns those discarded candidates into a reusable resource, collecting them over a month and returning selected items to the recommendation process when their categories offer something the user has not recently seen.
A second chance for unshown content
Recommendation systems consider far more items than they display. Videos can receive high predicted engagement scores yet lose out because screen space is limited and other candidates take priority. In a preprint, Ge Fan, Kai Meng, Huiping Chu, Yuning Jiang, Han Zhu and Bo Zheng describe using that overlooked pool to broaden discovery in Taobao’s short-video feed.
Their system, Unexposed Recycling for Efficient Discovery, or URED, adds a candidate-retrieval channel rather than replacing the recommendation models. The authors report that it has operated in production for more than six months, serving tens of millions of daily active users.
“Discovery” has a specific meaning here: a category that has not been shown to a particular user during a defined recent period. The reported experiments use 15 days. It does not necessarily mean a topic the person has never encountered or a lasting new interest.
Why not simply inject unfamiliar videos?
The researchers’ starting point was a failed alternative: randomly adding discovery candidates, including cold-start items. In their controlled experiment, this produced a statistically insignificant 0.12% increase in discovered categories and a statistically insignificant 0.17% decline in total video views.
Their explanation concerns prediction quality. When a model lacks information connecting a user with a category, it may fall back on population-level expectations that overestimate that user’s engagement. Production-log measurements showed greater overprediction and prediction error for discovery candidates than for non-discovery candidates, with naive boosting making both measures worse.
URED instead selects discovery candidates that the existing ranker has already scored highly. The authors interpret those scores as evidence of relevance and sufficient information for prediction. That reasoning rests on a stated working assumption: the ranker is approximately unbiased when it has enough input signal. A high score is therefore not an unconditional guarantee of quality.
A month-long collection pipeline
After ranking, URED retains the 200 highest-scoring unshown candidates per session, along with category information, timestamps and component scores. These records are stored asynchronously rather than requiring a new model to run during the request.
Daily batch processing combines each user’s records over a rolling 30-day window, removes duplicate items and retains up to 10,000 candidates ordered by recency. A subsequent filter keeps candidates from categories absent from the user’s recent exposure history.
The resulting lists are stored by user ID in an online key-value store. On a request, URED contributes up to 1,000 candidates to the shared retrieval pool. These still pass through the existing ranking and re-ranking stages: recycling an item does not guarantee it a feed position.
The authors report less than 1% additional end-to-end serving latency and no model retraining. Training-free does not mean infrastructure-free: URED requires logging, storage, batch aggregation and online serving. Its deployment reused existing infrastructure, including spare batch capacity.
What the experiments found
Users were randomly assigned to control and treatment buckets, and every reported experiment ran for more than a week. The paper describes significance testing using a Z-test with CUPED variance reduction.
Against the baseline pipeline, URED increased discovered categories by 3.47% and content richness—the paper’s measure of distinct exposure diversity—by 8.47%. Completed video views increased by 2.62%. All three changes were statistically significant. Total video views increased by 0.36%, but that result was not statistically significant.
The accumulation window mattered. Reducing it from 30 days to one day left a 0.55% category-discovery increase that was not significant. Extending it to 60 days produced little additional discovery benefit, supporting the authors’ choice of a month-long window.
A separate channel comparison found that 85.9% of URED-attributed exposures belonged to discovery categories, versus 6.2% platform-wide. That 13.9-fold ratio describes discovery concentration within a channel, not a 13.9-fold improvement in overall user discovery. URED’s rate of views exceeding a fixed duration threshold was 1.03 times the platform average.
Where recycling reaches its limits
URED inherits the ranker’s blind spots and depends on users generating enough unshown candidates. The authors report much larger discovery gains for highly active users and essentially no change for low-activity users. In operation, they combine it with cold-start retrieval channels.
Batch processing also creates a freshness gap: categories can cease to qualify as discovery between offline filtering and online exposure. The authors attribute URED’s discovery concentration falling below 100% to that delay.
The preprint offers evidence for a specific production intervention, not a universal solution to recommendation diversity. Its practical lesson is narrower: previously scored but unshown content can be a useful discovery resource when the existing model’s predictions are trustworthy.
- recommender systems
- Taobao
- URED
- content discovery
- unexposed candidates
- short-video recommendation
- candidate retrieval
- A/B testing