TRANSMISSION // 2611.05992v1
Clips2Story turns shuffled footage into keyword-guided video storyboards
Source published
Junnuo Wang, Weihan Xu and Hao-Wen Dong propose a video-editing pipeline that retrieves existing clips and uses a language model to arrange them into editable storyboards, optionally adding narration. Their preprint reports stronger keyword alignment and viewer ratings than selected baselines in controlled experiments, but does not establish performance on real production footage libraries or guarantee factual storytelling.
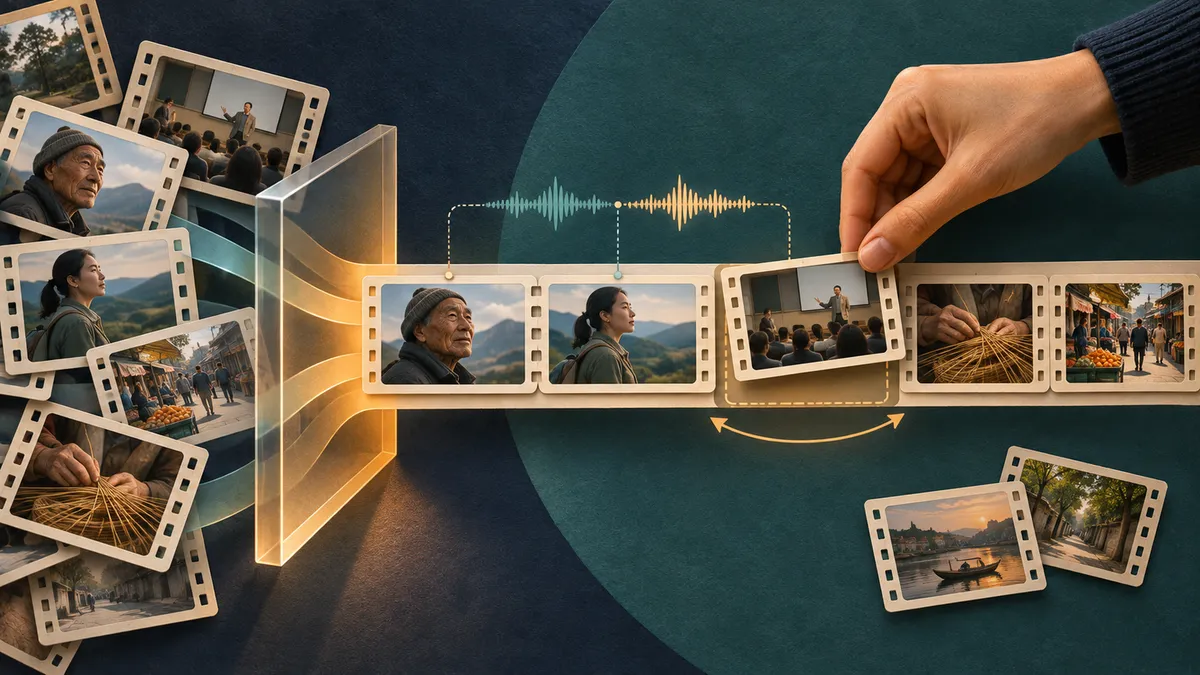
Choosing footage is only part of editing: the selected pieces also need to tell a story. Clips2Story explores whether existing AI models can help with both tasks, using a keyword to guide clip retrieval and narrative planning while leaving the proposed storyboard open to human revision.
From a keyword to an editable sequence
Clips2Story addresses a different problem from shortening a video while preserving its existing storyline. Given an unordered collection of clips and a keyword, it proposes which footage to use and how to arrange it into a themed short video. Junnuo Wang, Weihan Xu and Hao-Wen Dong describe the system in the preprint Clips2Story: Training-Free Video Storyboarding and Editing Using Multimodal Retrieval-Embedded Generation.
The central idea is to let a language model plan an edit using written descriptions of footage rather than the raw audiovisual material. The output includes a human-readable storyboard that a creator can inspect and revise before assembly. The authors also describe a prototype interface for adjusting clip selections, reordering segments and previewing the proposed sequence.
“Training-free” means the pipeline uses existing pretrained models without training a new task-specific model. It does not mean the underlying models were never trained.
How the pipeline works
First, Clips2Story builds descriptions of each clip. These include speech transcripts, speaker information, a caption generated from the middle frame, detected entities, background cues and duration. The implementation combines speech recognition and visual-analysis models for this stage.
Next, it compares the keyword with each clip’s transcript and caption using numerical representations of their meaning. It retrieves the highest-ranking candidates, up to a combined duration of 15 minutes. This filtering keeps the planning input manageable, rather than asking the language model to reason over the entire footage collection.
The authors test two editing variants, both using GPT-5.2 for planning. The narration-free version, Clips2Story-NF, selects and sequences existing audiovisual clips. The narration-driven version, Clips2Story-ND, also writes connective narration and synthesizes it as speech. It retrieves footage to accompany those passages, muting that footage’s original audio, while retaining original sound in other selected segments.
This is primarily an assembly system, not a generator of new video imagery. Its creative intervention lies in selection, ordering and, for the narration-driven version, the words connecting the material.
What the experiments show
The evaluation uses 100 long-form YouTube videos, evenly divided among documentaries, films, lectures, vlogs and news. Each source video is segmented and shuffled to create an unordered candidate pool. One setting uses individual shots; another groups adjacent shots into longer scenes. The authors generate five keywords per source video with a language model using its full transcript and captions.
They compare Clips2Story with adapted versions of A2Summ, TeaserGen and REGen. Their reported automatic results show the narration-free variant best preserving the source video’s original ordering, while the narration-driven variant achieves the strongest narration-based keyword relevance. Improvements in visual keyword relevance are smaller and less consistent across genres.
These results do not amount to a win on every measure. TeaserGen scores higher on the reported CLIPScore and VTGHLS alignment measures. Both Clips2Story variants repeat less content than TeaserGen and REGen, but A2Summ reports no repetition in the aggregate results. Both variants also tend to exceed the requested three-to-five-minute duration, especially the narration-driven version.
A human study involved 15 participants and videos from three genres: documentaries, films and lectures. The authors report higher ratings for Clips2Story-ND than REGen across the evaluated video criteria. For example, the reported mean coherence rating is 4.43 out of five, compared with 3.17 for REGen. Textual storyboard organization is tied between those systems, rather than improved.
What remains unproven
The experiments simulate fragmentation by shuffling material from already edited videos. They do not establish equivalent performance on a production library containing unrelated shoots, incomplete coverage or footage that never formed a coherent original story. The keywords are also model-generated from the source material, rather than collected from editors pursuing independent creative briefs.
Several measurements need careful interpretation. Agreement with the original clip order is a diagnostic proxy, not direct proof that a newly constructed story is coherent. Likewise, the survey’s “realness” question asks whether a video appears realistic and convincing; it does not test factual accuracy.
The authors identify important failure modes. Text descriptions can miss fine visual details and background-music continuity, producing jarring transitions. Hard filtering can discard supporting footage that is useful to a story despite being only indirectly related to its keyword. More seriously, rearrangement and narration can recontextualize factual footage into misleading accounts, particularly in news and documentaries.
Source status
This account concerns arXiv version 2611.05992v1, submitted on 4 November 2026. The supplied materials identify it as a preprint and do not establish peer-review acceptance. The paper says source code and implementation details will be released upon acceptance. This account relies on the supplied landing page, metadata and extracted paper text; extraction omits images and may garble tables or equations. The findings above are author-reported experimental results, not independently verified production outcomes.
- Clips2Story
- AI-assisted video editing
- storyboard generation
- multimodal retrieval
- large language models
- keyword-guided editing
- synthetic narration
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
When AI learns new facts, its confidence may lag behind
Source published
Shared keywords: large language models
A Formula-Aware Map Helps AI Navigate Spreadsheets with Less Data
Source published
Shared keywords: large language models
Temporarily disabling safety neurons could make AI models harder to jailbreak
Source published
Shared keywords: large language models
GEdit Uses Geometry to Update AI Facts With Less Collateral Damage
Source published
Shared keywords: large language models
AI literature reviews: better access helps, but expert judgment still matters
Source published
Shared keywords: large language models