TRANSMISSION // 2611.05937v1
Two ways of reading radio signals work better together—in a CPU-only benchmark
Source published
FuseAMC combines a compact neural network with a classifier built on hand-crafted signal statistics. On a reduced synthetic radio benchmark, the authors report 55.8% classification accuracy, outperforming either approach alone overall. The advantage depends on signal conditions, and simulated channel changes substantially weaken performance; real-world radio validation remains future work.
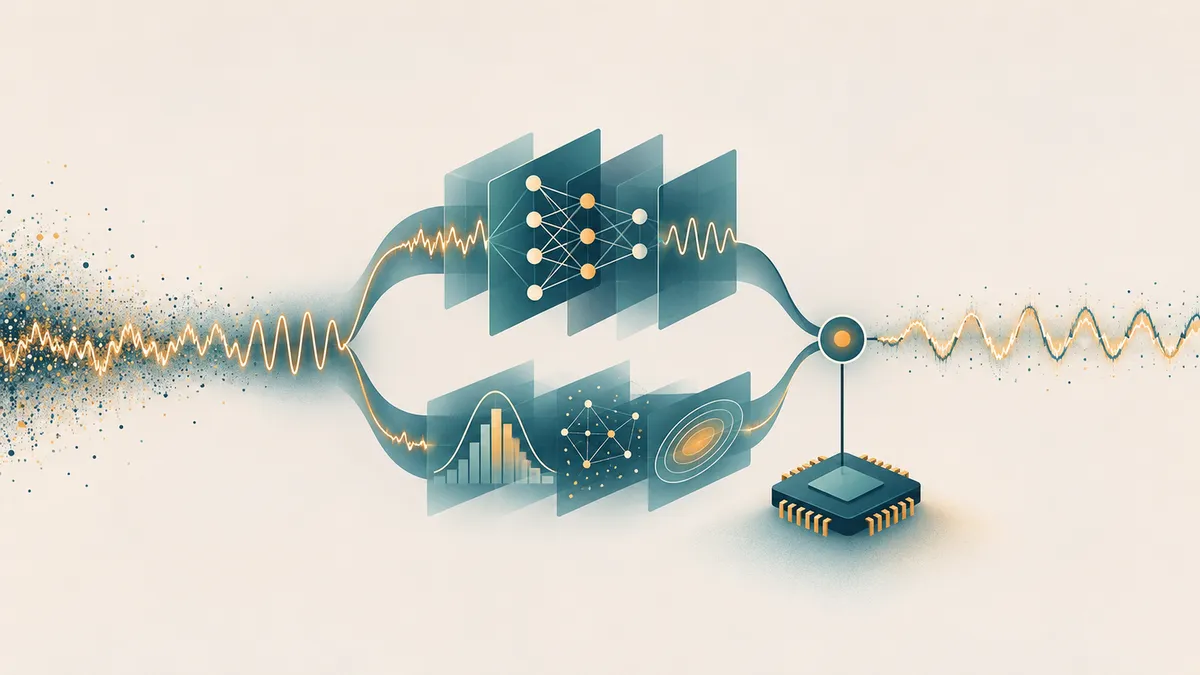
A radio receiver may need to identify how a signal encodes information without knowing its transmitter. This preprint asks whether two relatively lightweight classification methods can compensate for each other’s weaknesses, rather than compete for a single winner.
Two approaches, different strengths
Automatic modulation classification means identifying the scheme used to encode information onto a radio signal. The task matters for applications such as spectrum sensing and identifying unfamiliar transmissions. In this study, however, those applications are motivation—not demonstrated deployments.
Zhiyi Yin and colleagues investigate two approaches that can run on a central processing unit without a graphics accelerator. One is a compact convolutional neural network, or CNN, which learns from paired numerical samples representing the received waveform. The other uses hand-crafted statistical features, including higher-order cumulants, which summarize aspects of the signal’s distribution. A gradient-boosted tree classifier converts those features into predictions.
The authors’ central observation is that these approaches have different strengths on their chosen benchmark. The CNN performs better when noise is relatively strong. Statistical-feature classifiers perform better when the signal is clearer. FuseAMC combines their predictions to exploit that difference.
Combining decisions, not building a larger network
Each input contains 128 paired in-phase and quadrature samples, two components used to represent a radio waveform. Both processing streams receive the same power-normalized input and independently produce probabilities for 11 modulation classes.
FuseAMC joins these probability lists and passes them to a small logistic-regression model. This final model learns how to combine the two sets of predictions. It is fitted on validation data separate from both the streams’ training data and the test set.
The combiner does not receive the signal-to-noise ratio, or SNR, when making predictions. The authors interpret its behavior as implicitly adjusting trust between the streams as their prediction patterns change with signal quality. This is not an explicit measurement of noise conditions.
What the benchmark shows
The experiments use RadioML 2016.10a, a synthetic dataset generated with GNU Radio. It covers 11 modulation classes and 20 SNR levels, from −20 to +18 decibels. To limit CPU costs, the researchers use a reduced subset: approximately 22,000 training frames, 11,000 validation frames and 44,000 test frames.
They report results across five random seeds, with the same fixed data split and test examples throughout. Those runs therefore measure variation under that split, not performance across five independently sampled datasets.
In the main results, FuseAMC reaches 55.8% overall accuracy. The authors report gains of 5.1 percentage points over the strongest classical baseline, a support-vector machine using cumulant features, and 3.2 points over the CNN alone. Their reported paired-bootstrap 95% confidence intervals for those gains are 5.0–5.2 and 3.1–3.4 points, respectively. These intervals describe the experimental comparisons, not uncertainty about deployment performance.
The overall figure conceals substantial differences by signal quality. At low SNR, defined here as at most 0 decibels, fusion achieves 33.7% accuracy, close to the CNN’s 33.6% and above the classical baseline’s 24.1%. At high SNR, at least 6 decibels, fusion reaches 83.5%—below the best classical baseline’s 84.3%, but above the CNN’s 76.2%. Fusion is therefore not the strongest method in every regime.
The extra benefit of learning the combination is also small. Alternative soft-combination methods finish within 0.4 percentage points overall in the authors’ comparison. They attribute most of the improvement to combining complementary predictions, with the learned combiner providing a modest refinement.
Lightweight does not establish deployment readiness
The authors report single-core execution without a GPU and end-to-end training times of 150–160 seconds per seed on a modern CPU core. They describe roughly five megabytes of uncompressed model storage. The CNN’s arithmetic cost is estimated analytically at about 3.3 million floating-point operations per frame.
These figures support the paper’s resource-conscious design, but do not establish real-time performance on a particular embedded radio. The study does not report an over-the-air deployment.
Its simulated stress tests show why that distinction matters. Models trained on the unperturbed benchmark lose approximately 8–24 percentage points of fusion accuracy under changes involving sampling rate, fading, additional noise or carrier frequency. Under fading, simple probability averaging outperforms the learned combiner. Combining predictions does not reliably repair unfamiliar channel conditions.
Source status and remaining limits
This account concerns arXiv version 2611.05937v1, submitted on November 4, 2026. The landing page reports acceptance at the 2026 International Conference on Artificial Intelligence, Automation and High Performance Computing. That reported acceptance is distinct from independent verification of the findings.
The evidence reviewed consists of the supplied landing page, metadata and extracted paper text. PDF extraction can disrupt tables and equations and omits images. The manuscript’s code-availability wording both describes materials as available and says they will become public upon publication; their accessibility was not verified here.
The substantive result is a benchmark-specific demonstration of complementary classifiers. Full-dataset evaluation, testing on another benchmark and over-the-air captures remain future work, as the authors acknowledge.
- automatic modulation classification
- FuseAMC
- decision fusion
- convolutional neural networks
- higher-order cumulants
- RadioML 2016.10a
- CPU-efficient machine learning
- radio signal classification