TRANSMISSION // 2611.05918v1
Merging Salesforce Systems Without Hiding the Data Problems
Source published
A preprint proposes an auditable pipeline for consolidating Salesforce customer records after a merger. Synthetic-data experiments show how matching, quality checks and anomaly detection can work together—but also reveal false merges, missed semantic errors and differences between incremental updates and a full rebuild.
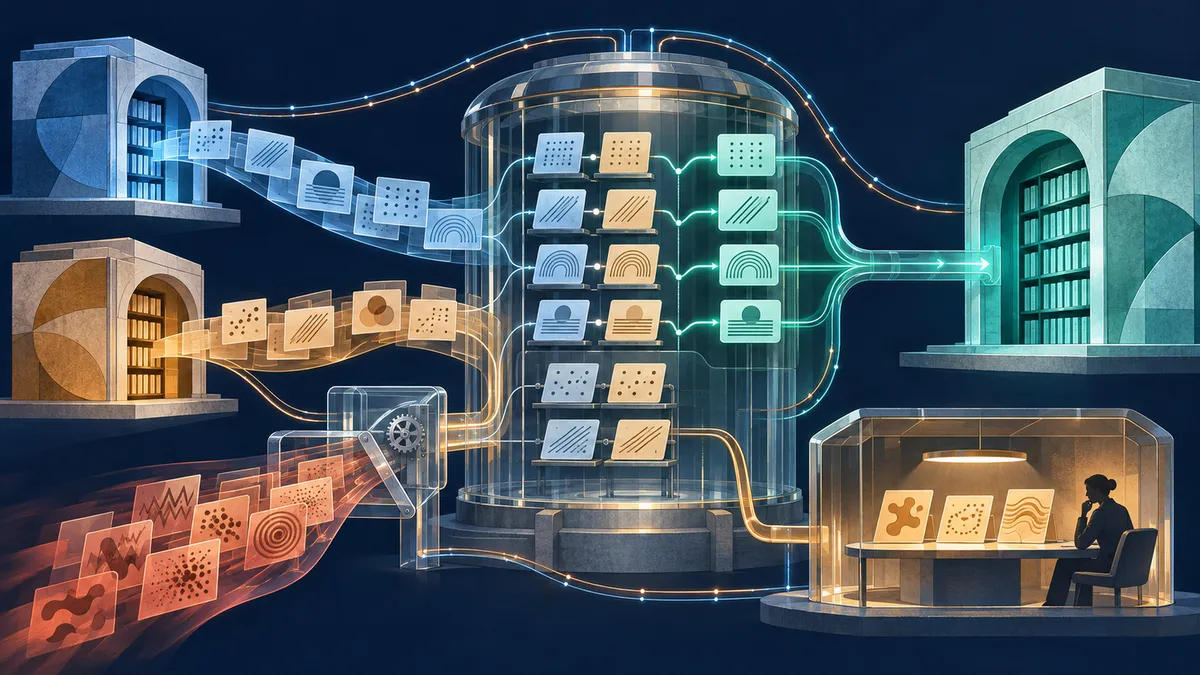
Combining two companies’ customer databases is not simply a copying job. A new preprint by Imran Basha Shaik, Sahla Sultana and Khader Moinuddin Shaik explores how automated consolidation can preserve relationships, expose bad data and keep records current while both businesses continue operating.
A merger is also a data reconciliation problem
Two Salesforce systems can describe the same customer with different names, field formats and category labels. They can also contain records that look alike but belong to different companies or people. Meanwhile, employees keep changing the source databases, making the migration a moving target.
In their preprint, Imran Basha Shaik, Sahla Sultana and Khader Moinuddin Shaik propose a reference framework for handling these problems together. Their contribution is an integrated design and a synthetic-data evaluation, not evidence from a production Salesforce merger. The paper also maps the design onto Jitterbit Integration Studio, but that mapping was not executed in the study.
Automation with a visible audit trail
The proposed extract-transform-load pipeline first gathers source records in manageable partitions. Mapping templates translate different schemas, timestamps and picklist vocabularies into a shared format. Quality checks then quarantine defective records or hold children whose parent account needs repair.
Duplicate detection combines exact rules with approximate, or fuzzy, matching. It produces a consolidated “golden” record, generally choosing the most recently modified non-empty value for each field. A cross-reference preserves the connection between source records and their consolidated identities. Opportunity records remain separate transactions, with their account references redirected appropriately.
Here, “autonomous” means routine decisions happen automatically and are logged for review. It does not mean eliminating human judgment: rejected records and suspicious batches still require attention.
Exact matches can still be wrong
The authors tested a Python reference prototype against generated Salesforce-like organizations with known duplicate identities and deliberately injected defects. Scaling experiments covered 32,040 to 383,973 source records; matching experiments used five random seeds.
At the preset matching threshold, the hybrid approach achieved pairwise F1 scores of 0.918 for accounts and 0.885 for contacts. F1 balances precision—how often a proposed match is correct—and recall—how many true matches are found. These scores describe record pairs, not the percentage of all customer records correctly migrated.
A revealing failure came from an exact rule: accounts sharing a web domain were automatically linked. In the simulated data, that merged distinct subsidiaries using a parent company’s domain. Most false account merges came from this deterministic rule rather than fuzzy matching.
Different thresholds improved the reported account and contact scores to 0.938 and 0.963. However, the authors selected those thresholds on the evaluation data itself. They are not independently validated performance forecasts; a real migration would need its own labeled calibration sample.
Quality checks prevent some losses, not every mistake
With quality gates enabled, the authors report no load failures across the evaluated runs. Without them, roughly 1,000 records per run failed during loading. More subtly, some unmapped category values became blanks that the simulated target accepted. Early checks made those problems visible instead of allowing silent information loss.
The gates nevertheless missed semantic errors. Only 2.3% of records with swapped first and last names were flagged, and those detections arose from additional defects. A plausible-looking name can pass structural validation while remaining wrong.
The strong detection rates also need context: the generator injected many of the same defect types the rules were written to catch. The authors acknowledge that this partly tests correct rule implementation rather than broad resilience to unfamiliar data problems.
Keeping up is not the same as rebuilding
In one five-day simulation spanning 120 hourly batches, the pipeline skipped 84 replayed events. A circuit breaker also held an injected faulty batch that blanked contact details, before it affected the target. None of the other 119 batches triggered an alarm.
The incrementally updated target closely resembled a full rebuild, but was not identical: reported field-value agreement was 99.94% for contacts and 99.36% for accounts. Existing clusters were not reconsidered when updates changed matching attributes. The authors therefore suggest periodic rebuilds and reconciliation at cutover. The rebuild comparison excluded the held faulty batch.
What remains unproven
Measured runtimes were local prototype results, not Salesforce migration timings. The experiments used two CPU cores and SQLite, excluding network delays, Salesforce API limits and Jitterbit execution costs. Matching also consumed a growing share of runtime as candidate groups expanded.
The synthetic scenarios were not calibrated against a real merger and omitted cases, activities, attachments, sharing rules and loading-time automation. Production validation remains future work. The supplied PDF extraction also omits figure visuals and disrupts some formatting; this account relies on explicit numerical and narrative statements rather than reconstructing missing graphics or equations.
The practical lesson is bounded: auditable automation can expose and contain modeled failures, but successful loading alone does not establish that customer identities or meanings are correct.
- Salesforce
- mergers and acquisitions
- ETL
- data integration
- entity resolution
- data quality
- change data capture
- Jitterbit
- synthetic data
- preprint
Related reading
Automatically matched by shared topic keywords. These links do not imply that the sources agree or establish a consensus.
AI agents organize thermoelectric research records—and reveal why traceability matters
Source published
Shared keywords: data quality
A Search for Training Data With Unexpected Side Effects
Source published
Shared keywords: synthetic data
A simulated city tests whether AI investigators can separate evidence from suspicion
Source published
Shared keywords: synthetic data
Transport model learns from unused routes—but matching flows does not guarantee reliable welfare estimates
Source published
Shared keywords: synthetic data