TRANSMISSION // 2611.05802v1
GREP asks whether AI-generated rooms actually make sense
Source published
A preprint introduces an evaluator that combines geometry, targeted views and human-use reasoning to inspect generated rooms. Its small validation studies suggest detailed diagnoses can outperform scores alone, but judge bias and incomplete inspection remain concerns.
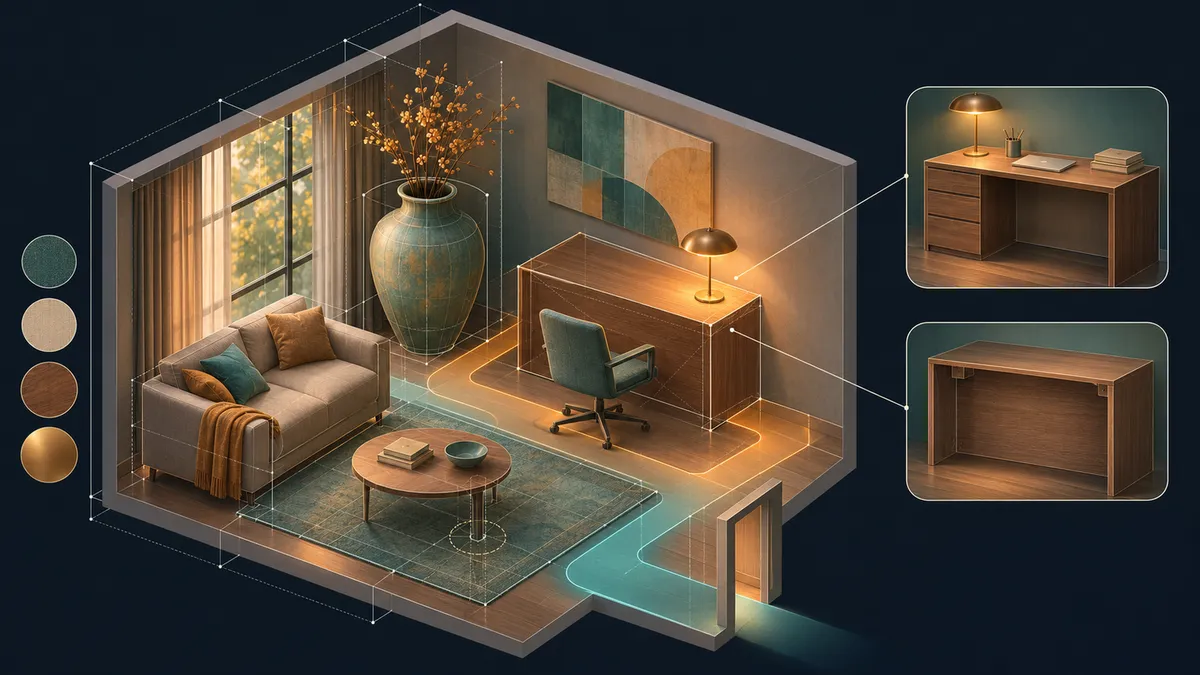
An AI-generated room can look convincing while leaving a chair unusable or furniture intersecting. GREP evaluates these scenes through physical validity, visual coherence and everyday usability, then explains the defects it identifies.
A furnished virtual room can pass a quick visual inspection and still make little sense. Furniture may intersect, objects may have implausible proportions, or a chair may face the closed back of a desk. In a preprint submitted to arXiv on November 4, 2026, Mohan Cao and colleagues introduce GREP, short for Grounding Generated Room Evaluation in Principles, to assess these different kinds of failure together.
The proposal shifts attention from a predefined list of scene-specific questions to three guiding principles. Physical validity concerns support, unintended collisions and objects crossing room boundaries. Visual coherence covers scale, style and compatible object choices. Human-use logic asks whether objects occupy sensible locations and remain usable, including their access, orientation and spacing.
An inspection rather than a single glance
GREP takes structured scene information, including assets, geometry, positions, orientations and scales. Geometric screening resolves clear cases directly. An overlap between coarse bounding boxes, however, identifies a possible collision rather than automatically proving one: intended contact and actual penetration can require closer inspection.
A vision-language model helps identify other checks and interpret evidence. It can use measurements, retrieve existing images or request additional rendered viewpoints while leaving the scene unchanged. For example, measuring the angle between a chair and a desk may not establish which side of the desk is usable. Another view can reveal whether the chair faces the knee space or a closed panel.
This flexibility has a defined boundary. The evaluator selects objects and relationships within fixed check types; it does not invent unrestricted new evaluation procedures. Its inspection records retain verdicts, reasons, measurements, views and evidence gaps. Confirmed defects receive severity-based penalties, which are aggregated into metric, room and scene scores.
Promising agreement on a small comparison
The authors compared GREP with human preferences using six selected open-space scenes. Five computer graphics researchers independently judged all 15 scene pairs from global images and room context. GREP agreed with the human majority on 13 pairs, or 86.7%.
A holistic vision-language judge agreed with the majority on 62.2% of pairs, averaged across three runs. A physical-only baseline agreed on 53.3%. That baseline reused GREP’s physical scores rather than running an independent geometry-only detector.
These results support the authors’ argument that room quality extends beyond physical plausibility. They do not establish broad human-level judgment. The comparisons reuse the same six scenes, so the pairwise decisions are not independent scene samples. Evidence also differed: humans and the holistic judge saw global images, whereas GREP’s original evaluations could use geometry and additional views.
Diagnoses can guide repairs
A separate experiment tested whether GREP’s explanations help a generator revise its work. GPT-4.1 revised five scenes with fixed assets over three rounds. The branches received either no evaluation feedback, scores alone, or scores accompanied by confirmed defect records.
After three revisions, the report-guided branch increased its mean reported score from 0.585 to 0.676; the other branches declined slightly. Reports also prompted layout changes in every revision, unlike the other feedback conditions.
Those figures use a separate refinement-specific scoring protocol. They are not the main GREP scores divided by 100. The small experiment also exposed incomplete repairs and evaluator variability: some unchanged layouts received different scores when evaluated again. Detailed feedback helped in this setting, but it did not guarantee that revisions removed every problem or avoided introducing new ones.
Planning and inspection both have limits
The paper also benchmarks native model planning, specialized generation pipelines and tool-using agents. In its fixed-asset comparisons, all four tested pipelines reduced GPT-5.6 Sol’s score relative to direct placement, while LayoutVLM improved GPT-4.1’s result. The authors interpret these patterns as evidence that stronger planning does not necessarily bring better adaptation to external guidance. These are setting-specific findings, not proof that pipelines or harnesses are generally harmful; computational budgets were not equalized across pipeline methods.
GREP itself remains fallible. Its main judge, GPT-5.6 Sol, is also an evaluated generator, creating a potential self-preference concern. A limited second-judge analysis cannot settle that issue. Discovery may miss relevant relationships, even when every instantiated check receives a verdict.
Inspection budgets introduce another constraint. Unresolved checks can receive forced binary judgments from incomplete evidence, and some procedures use labeled default-valid outcomes after non-hard failures. Reports disclose these decision sources, but disclosure does not make them correct. GREP’s contribution is therefore a structured, evidence-recording approach to room assessment—not a guarantee that a high-scoring scene is defect-free.
- 3D scene evaluation
- vision-language models
- room layout generation
- physical validity
- human-use logic
- diagnostic feedback
- AI evaluation