TRANSMISSION // 2611.05798v1
Same Shape, Different Weights: An Audit Separates AI Accuracy From Consistency
Source published
A preprint tests whether systems reading neural-network weights recognize visual content when equivalent networks are written differently. Some supervised readers lose substantial accuracy, while normalized readers retain their predictions. Language-model experiments show why recognition, consistency and variation between identical requests need separate measurements.
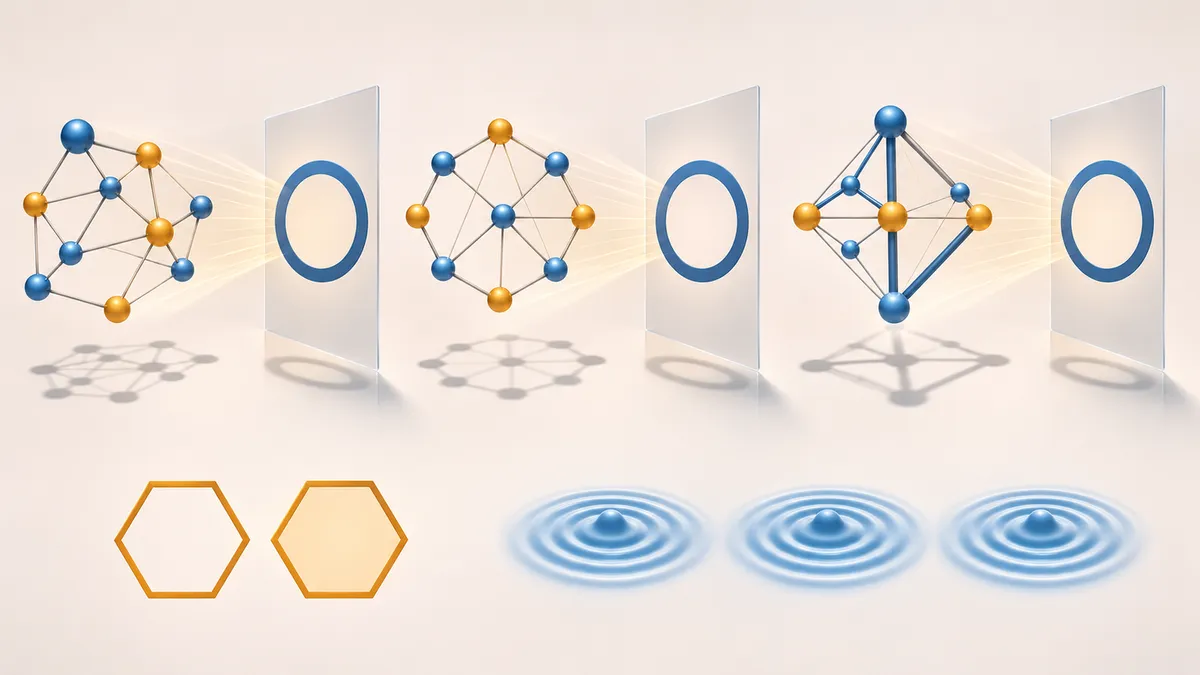
A neural network can encode a picture without storing it as pixels. But the numbers describing that network are not a unique representation of the picture. A new preprint asks whether systems interpreting those numbers follow the visual content—or depend on how the network happens to be written.
Recognizing a shape from neural-network weights poses a subtle evaluation problem: different lists of numbers can describe exactly the same function. A system that identifies a circle from one list should still identify it after a function-preserving rewrite. Yet giving the same answer every time is not enough; a reader that always guesses one class is perfectly consistent.
In the preprint Consistency Is Not Understanding: Orbit Audits for Neural Field Weight Readers, Sungguk Cha and colleagues at LG Uplus propose measuring recognition accuracy, answer agreement and numerical fidelity separately. Their experiments illustrate how each can reveal a different failure.
Changing the description, not the shape
The researchers fitted 480 independent neural fields representing six shape classes: circles, squares, diamonds, triangles, crosses and rings. Each field is a small network that takes a two-dimensional coordinate and returns a number; values at or below zero define its foreground. They also fitted 1,000 fields to downsampled MNIST handwritten-digit images.
The audit changes network parameters in two ways. It rearranges hidden neurons, and it rescales each neuron's incoming weights and bias by a positive factor while inversely rescaling its outgoing weight. For these one-hidden-layer ReLU networks, both operations preserve the represented function in exact arithmetic.
The resulting parameter lists look different without intentionally changing the visual content. Transformed copies remain grouped with their original field, rather than being counted as independent examples. Supervised readers were evaluated on 120 held-out shape fields and 200 held-out digit fields; language models used a 60-field shape subset.
Strong recognition can depend on arbitrary coordinates
One supervised reader classified shapes using summary statistics of the weights. Its accuracy was unchanged by neuron rearrangement, but fell from 96.7% on original weights to 24.2% when rearrangement and rescaling were combined. A set-based reader similarly fell from 96.7% to 20.0%.
Normalization changed that outcome. A reader that normalized neuron parameters before set-based processing achieved 95.0% shape accuracy, with unchanged predictions across the tested transformations. On the digit fields, the normalized set reader retained 69.0% accuracy, while its unnormalized counterpart fell from 68.5% to 20.0%.
These results distinguish robustness from recognition. Another approach normalized and sorted the parameters into a standard order before applying a simple classifier. It also retained its predictions, but reached only 71.7% shape accuracy. Removing the tested coordinate ambiguity did not make every classifier equally capable.
A separate control evaluated each network at 81 fixed coordinates and classified those outputs. It achieved 100% observed shape accuracy. That supports the presence of useful information in the fitted functions, but it is not tool-free weight reading: it executes the target network.
Language-model answers need additional controls
Four small frozen language models achieved 15.0–21.7% original-weight accuracy on the six-way shape task, whose chance reference is 16.7%. Their choices came from next-token scores for answer letters, not generated explanations. Qwen2.5-0.5B selected the letter F on every original prompt, matching its predictions when weights were redacted. Its stability therefore did not demonstrate weight-dependent recognition.
A separate experiment collected 1,920 scored sessions across four requested reasoning configurations through Codex. Original-weight accuracy ranged from 35.0% to 86.7%. All four answered every control prompt correctly when explicitly given the shape name.
However, fresh requests with identical original prompts disagreed on 8.3–38.3% of fields. Disagreement after a function-preserving rewrite must therefore be compared with variation already present without any input change. For the Astra configuration, transformation disagreement exceeded identical-input disagreement by 11.7 percentage points, with a reported interval excluding zero. The corresponding intervals for the other configurations included zero; that does not establish their equivalence or absence of sensitivity.
The authors do not interpret the small-model and reasoning results as a scaling law: models, execution context and answer interfaces differ together.
Even the printed numbers require checking
Prompts contained weights rounded to six significant digits. The researchers executed those rounded networks and supplemented sampled checks with exact-rational output-error bounds across the input square. Small output-error bounds do not, by themselves, certify unchanged semantic labels.
Canonicalization—normalizing and sorting parameters—made equivalent prompts identical in the tested cases. Yet fresh identical canonical requests still produced disagreement in the generated-answer experiment.
The evidence is limited to small, shallow fields, selected prompts and recorded execution configurations. Codex exposed requested model identifiers, not independently verified server snapshots. The audit is therefore a diagnostic protocol, not a universal verdict on whether language models understand weights: correctness, representation robustness and response variability remain separate questions.
- neural network weights
- neural fields
- orbit audits
- function-preserving transformations
- canonicalization
- language model evaluation
- robustness