TRANSMISSION // 2611.05742v1
Teaching vision transformers where finer image patches matter
Source published
SPLIT learns which image regions deserve fine-grained tokens before transformer processing. The researchers report higher throughput with accuracy close to full-resolution baselines, but token budgets require retraining and aggressive compression can lose important detail.
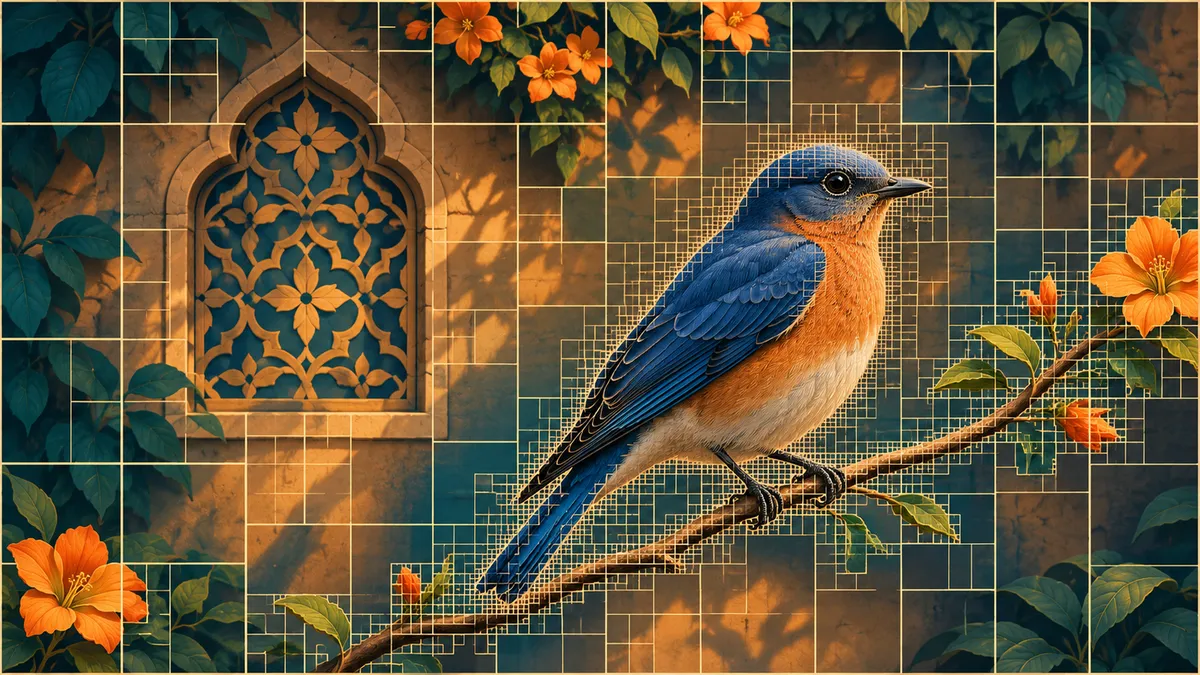
A textured wall can contain plenty of visual complexity without being the subject of an image. SPLIT trains a vision transformer’s patch-selection module to spend computation on information useful for its task, rather than treating visual busyness as importance.
Vision transformers typically divide an image into equally sized patches, turning each patch into a token for the model to process. That uniform grid gives background texture and important objects the same spatial resolution. Using fewer tokens can reduce computation, but choosing which details to preserve is crucial.
In Learning Hierarchical Patch Splitting Policies for Faster Vision Transformers, Aditya Gupta and colleagues at Carnegie Mellon University introduce SPLIT: Split Policy Learned Image Tokenization. Their arXiv preprint reports experiments in image classification, object detection, semantic segmentation and visual question answering. The supplied arXiv record also lists the work as accepted at NeurIPS 2026.
Deciding where to split
SPLIT begins with coarse image patches and learns whether to replace each one with four smaller patches. Repeating that decision creates a mixed-resolution representation: some regions remain large patches, while others receive finer coverage.
The decision module compares a parent patch’s embedding with embeddings of its four children. A small cross-attention component summarizes the children using the parent as its query; a neural network then predicts a splitting probability. At inference, probabilities above 0.5 trigger a split.
This differs from methods that first process a dense token sequence and subsequently discard or merge tokens. SPLIT reduces the sequence entering the transformer layers. It also differs from adaptive patchification based on pixel entropy, a measure that can assign high importance to busy textures regardless of their relevance to the task.
The approach still computes multi-scale patch embeddings and makes selection decisions. It does not eliminate the cost of inspecting candidate regions. Its intended saving comes from sending fewer tokens through the more expensive transformer backbone.
Learning the accuracy–computation trade-off
Choosing which tokens exist is a discrete operation, making ordinary backpropagation through the selection step difficult. The authors therefore train the splitting policy using reinforcement learning, specifically proximal policy optimization, or PPO.
Training weighs downstream prediction error against the fraction of tokens retained. An adaptive multiplier increases pressure to reduce tokens when average usage exceeds the target. The mathematical constraint concerns expected token usage, not an inviolable limit for every image; individual images can receive different sequence lengths.
Before reinforcement learning, a warm-start phase teaches the decision module to imitate splitting labels based on parent–child embedding differences. The backbone is fine-tuned during this phase to accommodate mixed-resolution inputs, then frozen during subsequent policy training. For classification, the reported recipe uses one warm-start epoch followed by one reinforcement-learning epoch.
Faster processing, with small accuracy differences
The paper’s headline result is classification accuracy close to full-resolution baselines while using about 30% fewer tokens. The measured throughput improvement varies substantially with model size and image resolution. All reported inference measurements use a single NVIDIA A100.
For a large vision transformer at 336-pixel resolution, SPLIT processes 570 images per second versus 395 for the uniform-grid baseline, a reported 44% throughput increase. Accuracy is 88.1% versus 88.2%. For the huge model at that resolution, throughput rises from 175 to 281 images per second, while accuracy changes from 88.5% to 88.4%.
Dense prediction shows smaller throughput gains. On COCO detection with the large EVA-02 backbone, throughput increases from 1.61 to 2.02 images per second, while mean average precision changes from 62.28 to 62.24. On ADE20K segmentation at 640-pixel resolution, throughput rises from 3.44 to 3.97 images per second; mean intersection-over-union changes from 60.05 to 59.99.
These results support near-baseline quality rather than literal equality on every metric. Visual question-answering scores are mixed, and the entropy-based APT comparison runs somewhat faster than SPLIT in that setting.
What the policy preserves—and misses
To test allocation more directly, the researchers measure how often object and class-boundary patches receive fine tokens on ADE20K. At similar, though not identical, token fractions near 0.7, SPLIT assigns fine tokens to 90.7% of object patches and 94.5% of boundary patches, compared with APT’s 80.8% and 83.3%. These are allocation measurements, not segmentation-accuracy scores.
There are practical limits. Changing the desired token budget requires retraining in the current formulation. At a 45% retention target, the authors show segmentation failures involving coarse boundaries and missed thin structures. Image generation remains untested, and broadly reusable policies across different tasks remain an open direction.
The evidence therefore favors learned patch allocation as a way to improve inference efficiency in the tested image-understanding systems—not as a guarantee that less computation preserves every detail.
- vision transformers
- adaptive tokenization
- hierarchical patch splitting
- reinforcement learning
- inference efficiency
- computer vision