TRANSMISSION // 2611.05702v1
TACT puts an AI council to work on qualitative data—with humans retaining judgment
Source published
A preprint presents a workflow combining three model families, evidence checks and human review to analyze qualitative responses. Its evaluation on Stack Overflow threads found better agreement with prior researchers’ coding than a single-model baseline, but shared errors and limited generalizability remain concerns.
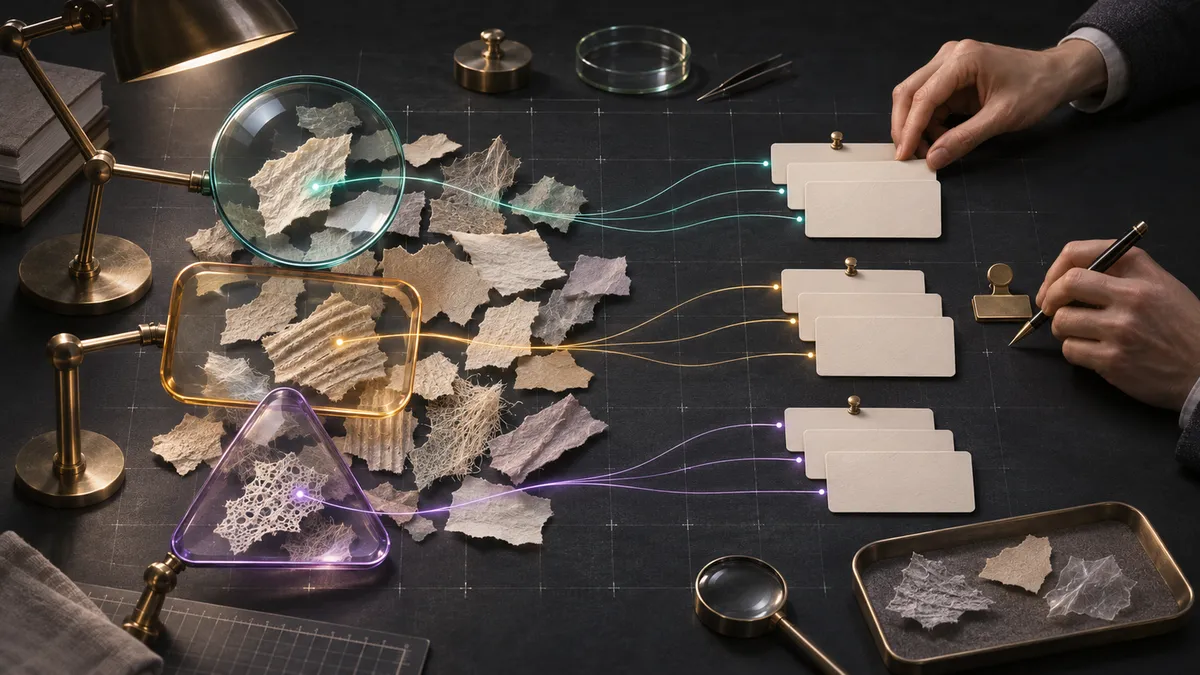
An AI-generated theme can sound convincing without faithfully representing the people behind the data. TACT attempts to make that interpretation inspectable: models propose and apply codes, software checks quoted evidence, and researchers approve the categories and assess the results.
Software teams collect interview transcripts, survey responses and discussion threads to understand what people need. Analyzing that material carefully takes time; asking a language model for themes is quicker, but can obscure how its conclusions arose.
In a preprint posted on November 3, 2026, Rudrajit Choudhuri, Christian Bird, Carmen Badea and Anita Sarma introduce TACT, short for Traceable AI Council for Thematic analysis. The procedure delegates explicit tasks to several models while reserving interpretive decisions for researchers. Its central distinction is between models agreeing with one another and an analysis being well supported by the data.
A division of labor, not an automated verdict
TACT begins with decisions about consent, de-identification, permitted model providers and evaluation thresholds. Software divides the material into identifiable units, such as discussion threads, and draws separate samples for researchers to code without seeing model output.
Three AI analysts from different model families independently propose codes: categories used to organize passages of qualitative material. They examine what respondents explicitly say, underlying assumptions and contrasting positions. Each proposed code comes with a definition, application rules and supporting quotations.
A deterministic program checks that cited units and quotations actually exist in the source material and that no unit was silently skipped. This can detect invented or altered evidence. It cannot establish that a genuine quotation supports the interpretation attached to it; researchers must make that judgment.
A reconciler model consolidates the proposals into a candidate codebook. Researchers first develop their own codes from a blind-pass sample, then review the model proposals against their evidence. They can merge, split, remove or add codes before approving the codebook.
Three AI coders subsequently apply that approved codebook independently, supplying rationales for their assignments. A code enters the consensus result when at least two coders assign it. Software measures agreement, while researchers examine problematic cases and compare the result with their own coding of a separate held-out sample.
What the fuller version adds
TACT-Lite provides this core workflow. TACT-Full adds adversaries from other model families to critique discovery, reconciliation and coding. The original model responds to each critique rather than allowing the adversary to edit its work directly.
Full also adds a decision model that scores how likely each code is to apply to a unit. Those scores screen the codes presented to the AI coders and flag low-scoring consensus assignments for human review. These mechanisms provide additional checks, not a guarantee that the council is correct.
Testing against an earlier study
The authors evaluated TACT using Stack Overflow discussions about GitHub Copilot that another research team had manually analyzed in 2023. Of 303 original posts, 256 remained available. The authors reconstructed the threads as they stood at the earlier study’s collection date.
The AI analysts saw all 256 threads during discovery, but agreement and reliability were evaluated on 192. The researchers mapped TACT’s codes to the earlier study’s categories, which were not identical in granularity. Reference comparisons therefore measured agreement with that coding scheme, rather than establishing a uniquely correct interpretation.
Candidate-codebook F1 scores were 0.75 for Lite and 0.77 for Full. Final-coding F1 scores were 0.71 and 0.72, compared with 0.65 for a single-model GPT-5.6 baseline. F1 combines precision and recall; here, its interpretation also depends on the category mapping and the available reference labels.
There is an important experimental qualification: both variants’ final coding used the same refined, 72-code codebook. Lite’s coding result was therefore not an independent end-to-end Lite run. The design instead helped isolate the effects of Full’s coding additions.
Full produced higher internal consistency: median per-code Krippendorff’s alpha rose from 0.77 to 0.87. On 50 held-out threads, agreement with the authors’ own manual coding was Cohen’s kappa of 0.79 for Lite and 0.85 for Full. That human check involved TACT’s designers using the final codebook, not an external assessment by unrelated researchers.
Affordable model calls, unresolved limits
Reported model-call costs were $35.26 for Lite and $86.00 for Full across 256 threads, using September 2026 list prices. These are model costs, not a complete accounting of human preparation and review. Costs for other datasets depend on their length and research questions.
The validation covered one English-language forum dataset. Because the threads and reference labels were public, training-data exposure could not be ruled out, even though the labels were withheld during the experiment. Different model families can also share errors.
The authors recommend starting with Lite while preserving evidence trails and human checks. The preprint supports a bounded claim: this workflow produced useful agreement in one evaluation, while making its decisions more traceable. It does not show that model consensus can replace researchers’ responsibility for interpretation.
- qualitative analysis
- thematic analysis
- AI council
- large language models
- human oversight
- evidence provenance
- software engineering
- TACT