TRANSMISSION // 2611.05664v1
A relevance rule for combining expert knowledge maps
Source published
An arXiv preprint proposes combining expert knowledge graphs according to how differently they answer a particular query. Simulations using seven synthetic stroke-risk maps show that the method changes model behavior, but do not establish better predictive accuracy or clinical usefulness.
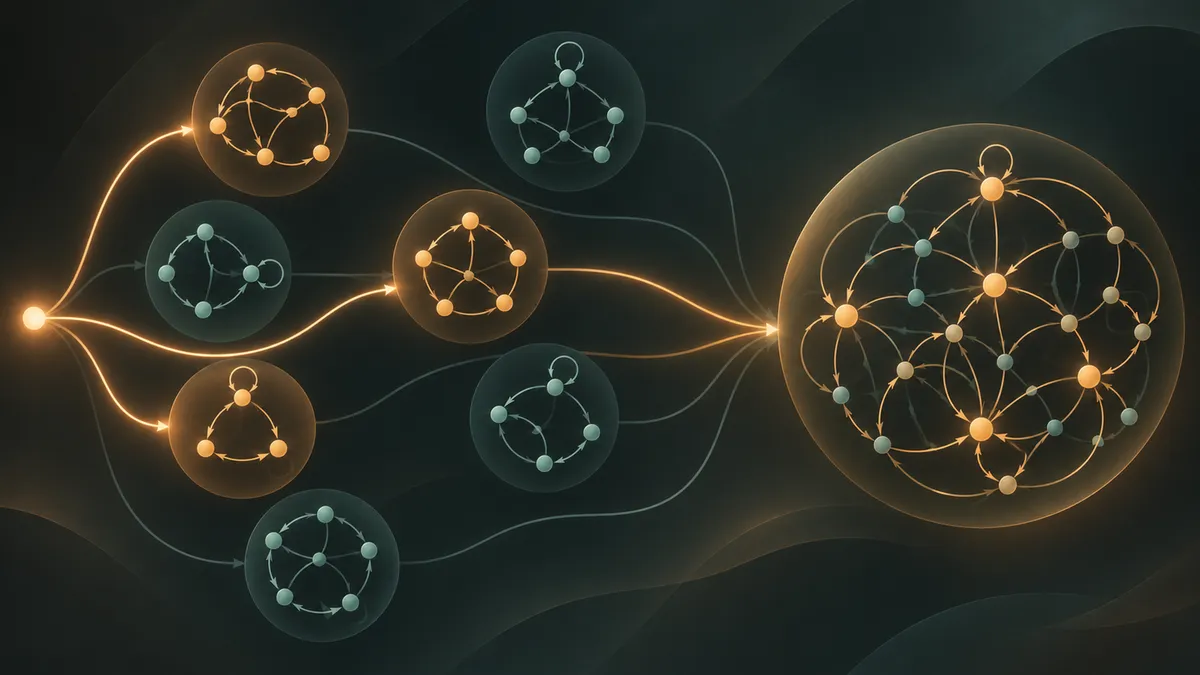
When several expert models offer answers, simply averaging their knowledge can obscure important differences. Olaoluwa Adigun, Akash Kumar Panda and Bart Kosko propose a query-dependent weighting method inspired by legal evidence rules, testing it on synthetic models derived from a published ischemic-stroke knowledge map.
Relevance has two parts
An AI system drawing on multiple knowledge sources needs a way to decide which contributions matter for a particular question. In an arXiv preprint posted on November 3, 2026, Olaoluwa Adigun, Akash Kumar Panda and Bart Kosko propose a mathematical approach to that decision. Their demonstration concerns simulated knowledge graphs, not a clinically validated stroke-prediction system.
The authors borrow a two-part definition from the law of evidence: relevant evidence must be both material and probative. Materiality concerns whether it bears on the matter at hand. Probativeness concerns whether it changes the evidential picture. They represent relevance as the product of these two quantities.
For their experiment, however, the materiality question is settled in advance. Every simulated expert concerns stroke, so each receives a materiality value of one. Expert credibility is also held at one. The study therefore mainly explores a proposed measure of probativeness, rather than demonstrating how a system discovers appropriate subject-matter experts or judges their trustworthiness.
Expert knowledge as a feedback network
The experts are represented by fuzzy cognitive maps, or FCMs. Each map contains nodes representing variables and directed, weighted connections representing proposed causal influences. Positive connections increase a receiving node’s activation; negative connections decrease it. Feedback loops allow influences to circulate.
Starting from an input state, a map repeatedly updates its node values. It may settle into a fixed pattern or a repeating sequence called a limit cycle. The authors treat these long-run patterns as the map’s answers to a “what if?” question.
Maps can be combined by taking a weighted average of their connection matrices. When maps contain different variables, missing rows and columns are filled with zeros so their matrices can be added. Importantly, this averages the connections, not the final answers: the resulting feedback network has its own dynamics.
The framework is motivated by systems combining human or artificial experts. In this demonstration, the queries are encoded node-activation patterns, not natural-language questions posed to conversational agents.
Giving disagreement more influence
The procedure starts with an initial mixture whose weights express confidence in the individual maps. It then constructs what the authors call “posterior-like” maps using matrix inversion, or a pseudoinverse when inversion is unavailable. These constructions resemble Bayesian updating algebraically, but their connection weights are not ordinary posterior probabilities.
The posterior-like maps are themselves combined using the initial weights. For a given input, the method compares each posterior map’s long-run pattern with the posterior mixture’s pattern. It measures their distance across a sequence of states, allowing starting positions within cycles to vary to maximize that distance.
Larger differences produce larger relevance weights. After normalization, those weights combine the original expert maps into a new, query-specific network.
This makes the proposal distinct from rewarding agreement with a consensus. An expert receives more influence for contributing a different answer. The authors interpret that difference as probative information. Difference alone, however, does not establish that an answer is correct.
What the simulations show
The starting point was a published 13-node ischemic-stroke FCM containing demographic, clinical and lifestyle variables, including age, blood pressure, diabetes, exercise and stroke risk. The researchers generated seven synthetic experts by perturbing its connections: randomly reversing or removing some influences and adding noise.
They examined both equal initial weights and unequal weights, with one expert receiving half the initial weight in the unequal case. For the equal-weight original mixture, they report checking all 8,192 binary input states. Each reached one of four nonzero equilibria or the all-zero fixed point. Relevance weights were also reported for representative inputs from four large attraction basins.
One illustrated comparison starts with only the age node active. The original mixture reaches a fixed point with the stroke-risk node inactive. The relevance-weighted mixture instead reaches a three-step cycle in which that node does not remain inactive. This demonstrates a change in the model’s answer—not that either answer accurately describes a person’s medical risk.
What remains unproven
The paper reports no patient-level validation, clinical accuracy measurements or evidence that relevance weighting outperforms ordinary mixing against observed outcomes. Its synthetic experts all originate from one reference map, rather than independently elicited expert judgments.
There are also boundaries to the formulation. The relevance calculation assumes answers settle into fixed points or limit cycles, although the paper notes that FCMs can exhibit chaotic behavior. Its normalization gives no explicit rule for a case where every measured difference is zero. All relevance weights in the reported tables are positive, so those examples do not demonstrate excluding experts entirely.
The contribution is a proposed query-dependent mixing method and a small simulation demonstration. Claims about large-scale, parallel or hardware implementations remain prospects rather than demonstrated results.
- artificial intelligence
- fuzzy cognitive maps
- expert knowledge
- relevance
- knowledge graphs
- neuro-symbolic systems
- model mixtures
- ischemic stroke