TRANSMISSION // 2611.05542v1
Ranking a Whole Feed Without Repeatedly Recomputing Its Contents
Source published
A Meta-authored preprint proposes Multi-Item Scoring, a method for ordering advertisements and organic content while accounting for earlier placements. The authors report quality close to an autoregressive comparison model with faster benchmark decoding, plus small positive outcomes in a randomized platform study. The findings come with important limits on what the comparisons and resource measurements establish.
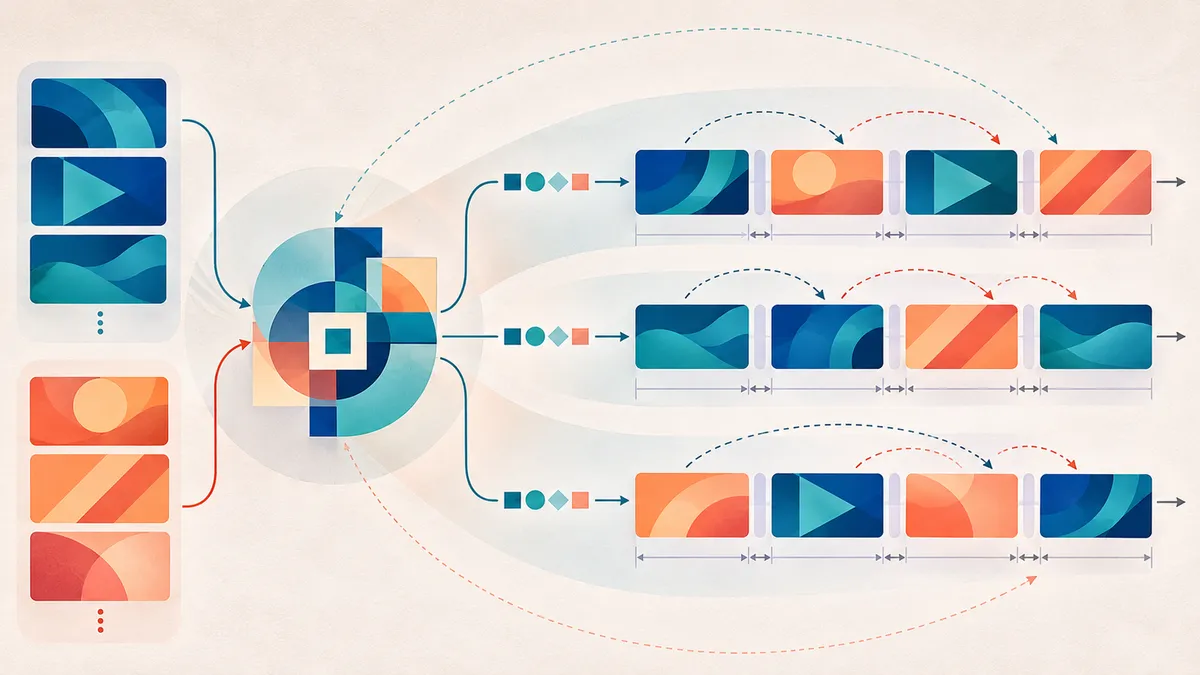
Choosing what appears in a feed is not simply a matter of sorting individual scores. An advertisement may affect engagement with the video after it, while spacing rules restrict where another ad can go. In “Towards Efficient Whole Page Ranking with One-Pass Inference,” Qi Xu and colleagues at Meta Platforms describe a way to consider these interactions without repeatedly running the most intensive candidate-processing computation. The paper was submitted to arXiv on November 3, 2026; the supplied source is a first-version preprint, not evidence of peer-reviewed publication.
Why ordering matters
Whole-page ranking chooses an ordered collection of items, called a slate, rather than evaluating each item in isolation. Its objective can combine advertising-related value and user engagement, subject to restrictions such as ad load, eligibility and minimum spacing.
The paper focuses on a trade-off between two approaches. Prefix-independent non-autoregressive models can efficiently calculate item–position scores, but those scores do not directly change with the sequence already selected. Autoregressive models condition decisions on earlier placements, potentially capturing more order-dependent effects at greater computational cost. This is a distinction between particular scoring designs, not proof that every non-autoregressive model is less accurate.
What “one-pass” actually means
The proposed Multi-Item Scoring framework, or MIS, separates reusable representations from sequence-dependent scoring. It computes representations of candidate items and output positions once, then uses a lighter scoring component to assess each possible next item given the selected prefix—the items already placed.
The full architecture combines interactions across the candidate pool, information about earlier placements and context about the target slot. It does not assign positional embeddings to the arbitrary input order of candidates; the selected output order is represented separately.
“One-pass” therefore does not mean that an entire page appears in one simultaneous decision. Prefix updates, conditional scoring and search still proceed sequentially. A constrained beam search retains several promising partial pages, masks invalid extensions and selects the strongest remaining alternatives. MIS evaluates only the candidate rows needed for live search branches rather than storing scores for every possible history. This preserves the fixed model’s beam-search decisions under matching rules, but does not make beam search globally optimal.
What the public benchmarks show
The authors evaluated MIS on KuaiRand-1K and RL4RS, using ten-item windows and nine-item slates, respectively. Their complete-prefix MIS variant produced prediction and generated-slate quality close to, or above, the adapted autoregressive CGA baseline’s point estimates.
For KuaiRand, generated-value lift over random ordering was 18.284% for MIS and 18.279% for CGA. On RL4RS, the corresponding figures were 34.067% and 33.276%. These are scores assigned by separately trained evaluators, not observed improvements in user behavior. Disjoint training reduces leakage, but does not turn predictions about alternative orders into causal evidence.
In single-model decoding measurements at beam width 32, MIS took approximately 6.76 milliseconds versus CGA’s 27.54 milliseconds on KuaiRand, and 5.72 versus 20.28 milliseconds on RL4RS. Those results yield the reported 4.07-fold and 3.54-fold speedups on one AMD EPYC-Genoa CPU thread. Simpler comparison methods remained faster than complete-prefix MIS. The timing protocol excluded tower fitting and loading, and generation-quality results used multiple models, whereas headline timings measured single models. The paper does not establish statistical equivalence in quality.
Compression is a separate trade-off
An optional residual-quantization method compresses historical item representations while keeping current candidate states uncompressed. In a matched KuaiRand comparison, the represented historical-catalog payload fell from 187.81 to 2.207 MiB, about an 85-fold reduction under packed code-storage assumptions. Generated-value lift decreased from 18.284% to 18.120%.
These figures describe catalog payload, excluding networks and working states—not total system memory savings. Compression also changes the scorer’s historical information; it is distinct from evaluating only active search rows.
What happened on the platform
The industrial study used a different MIS variant, representing four recent lags through content-type and relative-position information while retaining the immediate predecessor’s embedding. A randomized comparison against an industrial ranker used 300 hash-assigned segments per arm.
The authors report a 0.104% relative increase in their realization metric, with a 95% confidence interval of 0.054% to 0.153%, and a 0.058% increase in overall video watch time, with an interval of 0.001% to 0.114%. The linked-session interval included zero.
Ranking-service CPU consumption fell 9.73%, while prediction-service CPU rose 1.39%. Those percentages use different resource baselines and cannot be added to claim a net infrastructure saving. Overall, the results support a promising quality–computation trade-off in the evaluated settings, not a universal efficiency guarantee.
- whole-page ranking
- Multi-Item Scoring
- recommender systems
- advertisements and organic content
- prefix conditioning
- constrained beam search
- inference efficiency
- preprint