TRANSMISSION // 2611.05139v1
Meta² teaches AI agents when to change their working setup
Source published
A preprint reports that reusable guidance learned from training runs can help AI agents selectively adjust their prompts, tools and checks during new tasks, improving results on two evaluated benchmarks without changing model weights.
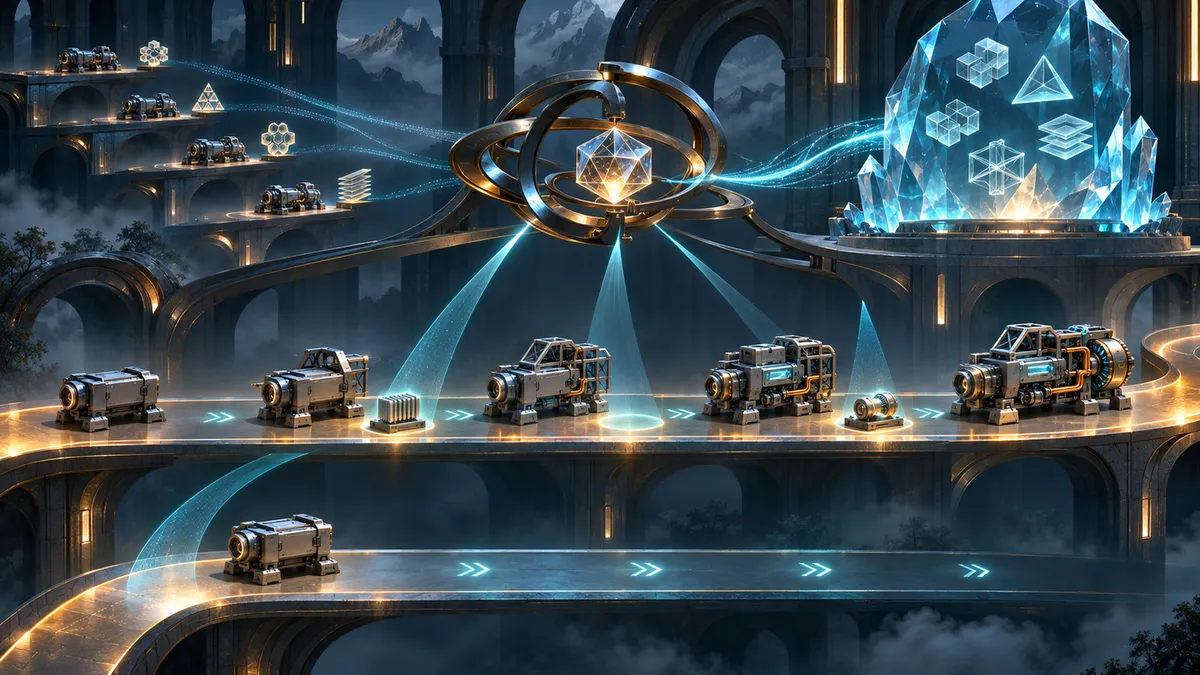
An AI agent can struggle because of its working setup, not just its underlying model. Meta² learns guidance for a separate supervisor that decides when to adjust that setup—and when to leave productive work alone.
A long-running AI agent depends on more than a language model. Its prompts, tools, memory policies and automated checks form a surrounding system called a harness. A fixed harness cannot anticipate every problem that emerges during a task, but changing it mid-run can also interrupt useful work or introduce mistakes.
In a preprint, Lingzhi Yuan and colleagues introduce Meta², a method that learns reusable guidance for making those changes. Rather than producing one optimized harness for every future task, it prepares a textual library called a Meta-Skill. A separate supervisory agent then consults that library while watching a task unfold. The underlying model weights remain frozen.
Learn the intervention rules beforehand
The offline learning stage compares training runs under three conditions: a task agent working without a supervisor; an agent supervised using the current Meta-Skill; and an agent whose supervisor receives privileged information about the training task’s verifier—the mechanism that assesses success.
Comparing successful and failed runs supplies candidate lessons. Some support intervention, such as addressing a contradiction the agent has left unresolved. Others favor holding back when the agent is already recovering. A third category warns against particular actions, such as redirecting a search that is still producing useful evidence.
The method reflects on these comparisons, combines recurring patterns across tasks and updates the library. Its aggregation procedure requires support from at least two distinct training tasks for each retained entry. Task-specific details are separated from general guidance.
Privileged verifier information is restricted to training. The verifier-informed supervisor is instructed not to pass that information to the task agent, and the authors exclude training trajectories that fail a leakage audit. These safeguards are part of the reported procedure, not a demonstration that leakage is impossible.
Adapt locally without restarting
During evaluation, the Meta-Skill stays fixed. Each run begins with the same seed harness, while the supervisor examines emerging execution evidence at checkpoints. The default schedule includes a checkpoint after the first agent step, regular five-step intervals and a final inspection when the agent claims completion.
At each checkpoint, the supervisor can keep the harness unchanged or modify it through permitted channels, including a notice, standing instructions, a hook or an added tool. The task agent continues in the same environment with its accumulated progress intact. At completion, a bounded send-back mechanism can request further work.
Crucially, those edits expire with the run. They do not become instructions for unrelated tasks, and neither evaluation outcomes nor task-local corrections update the frozen Meta-Skill. The supervisor cannot access held-out verifier contents or outcomes while the task is running.
Higher scores in the evaluated settings
The authors tested terminal-based workflows on Terminal-Bench 2.1 and repository-level software engineering on DeepSWE 1.1. They used 29 and 38 training tasks, respectively, with 60 and 75 held-out tasks. Scores average five runs per held-out terminal task and three per software-engineering task; they are not best-of-several-attempt success rates.
With GPT-5.6-Terra, Meta² achieved the highest performance point estimates among the evaluated methods: 81.00% on Terminal-Bench and 44.44% on DeepSWE. The shared NexAU seed scored 66.33% and 34.67%, respectively.
Ablations support both learned guidance and task-local editing. Adding a supervisor without distilled knowledge scored 74.67% and 36.44%. Retaining Meta²’s online edits across later tasks, rather than resetting the harness, reduced scores to 78.33% and 39.11%.
A separate Terminal-Bench experiment using DeepSeek-V4-Flash-0731 reached 77.67%. However, the researchers built a separate Meta-Skill for that model; this was not a test of transferring an unchanged library between models.
Gains with costs and limits
Supervision requires additional model calls. On the GPT-5.6-Terra terminal evaluation, Meta² cost $110.19 to construct offline and $64.72 to deploy across the evaluated runs. Its combined cost was lower than AHE and Meta-Harness, but lower-cost human-designed harnesses remained alternatives. More frequent checkpoints increased cost without improving the reported score.
The evidence also has attribution limits. Independently sampled runs can diverge before an intervention, so an outcome contrast cannot establish that one particular edit caused success. The appendix additionally notes scaffolding and segmentation differences between supervised and unsupervised training runs.
The results therefore support a bounded conclusion: reusable intervention guidance helped in these terminal and software-engineering evaluations. They do not establish universal transfer, guaranteed beneficial edits or applicability to domains with less explicit completion criteria.
- AI agents
- harness optimization
- Meta-Skill
- within-run adaptation
- long-horizon tasks
- software engineering
- Terminal-Bench
- DeepSWE