TRANSMISSION // 2611.04805v1
When AI Agents Agree, Their Majority Can Still Be Wrong
Source published
A preprint tests a method that discounts redundant AI agents rather than treating every answer as independent evidence. It improves accuracy on MMLU when a large, weaker model family dominates the pool, but can hurt when the dominant family is strongest—and the study finds no reliable label-free way to distinguish those cases.
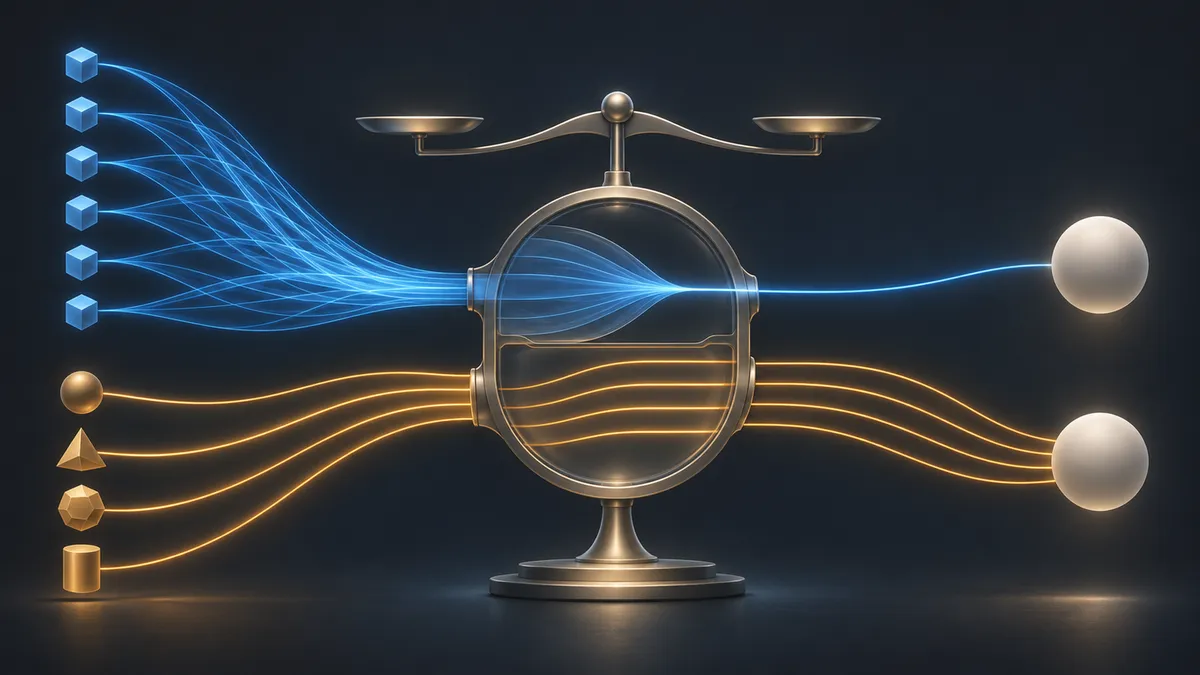
Thirteen AI agents do not necessarily provide thirteen independent opinions. If several are variations of the same underlying model, their agreement can amplify shared mistakes. A study by Laure Berti-Equille explores how to discount that redundancy, while showing why doing so is not always the right choice.
A crowd of AI agents can look more knowledgeable than it is. Several agents may use the same underlying language model with different prompts, personas or retrieval settings. When they agree, they may be repeating a shared mistake rather than independently confirming an answer.
In the preprint Where Is the Truth When AI Agents Disagree?, posted on November 3, 2026, Laure Berti-Equille of IRD, ESPACE-DEV investigates this problem through multiple-choice benchmarks. The proposed method, BP-TD, reduces the influence of correlated agents. Its central finding is conditional: discounting a dominant group helps when that group is weaker, but can hurt when it is strongest.
Why agreement can mislead
Classical truth-discovery methods estimate answers and source reliability together. Sources that agree with the emerging consensus become more trusted, and their answers then receive more influence. This can work when sources make errors independently.
A large group of related AI agents can upset that process. If its members repeatedly make the same mistake, the algorithm may interpret their agreement as expertise. The group shapes the consensus and is rewarded for matching it.
The study’s main pool contained 13 locally served agents built on five model families. On MMLU, six llama3.2-based agents formed the largest family but were relatively inaccurate, while four qwen2.5-based agents were substantially stronger. This deliberately correlated, unbalanced pool made shared errors consequential.
Counting a model family roughly once
BP-TD assigns each agent a weight reflecting its redundancy. One version uses model provenance: agents sharing a family divide one effective vote among themselves. Another uses observed answer agreement, reducing an agent’s weight when it agrees sufficiently often with other agents. Neither requires correct-answer labels.
The method then alternates between estimating which answers are correct and estimating agent reliability. Despite its name, the paper specifies that BP-TD uses mean-field variational inference, not sum-product belief propagation.
Its first answer update is simply a weighted vote. Later updates estimate reliability, but the experiments suggest that most accuracy gains come from the redundancy weights rather than repeated iteration. Those reliability scores are intended to rank agents, not provide calibrated probabilities of correctness.
The paper also tests a seemingly intuitive alternative: identifying dependence through shared mistakes. This fails when mistakes are judged against a consensus already controlled by the dominant group. The group’s answers look correct, so its members escape the discount intended to limit their influence.
Gains on one benchmark, not a universal victory
The main evaluation used MMLU, SciQ, TruthfulQA and ARC-Challenge, with 40 random validation/test half-splits. The paper distinguishes settings that use validation labels to tune parameters from genuinely label-free versions.
On the 160-question MMLU sample, label-free BP-TD using family weights or a fixed agreement threshold achieved mean test accuracy of 71.6%, compared with 62.4% for majority vote. The paper reports these gains as statistically significant under its corrected comparison procedure.
The advantage persisted in a larger MMLU harvest: family-weighted BP-TD reached 70.7% on 10,000 questions, versus 67.4% for majority vote. That harvest used a different serving setup, with half-precision models, so it was not simply an enlarged copy of the small experiment.
Results elsewhere were less favorable. SciQ offered little room for improvement because nearly every agent was already correct. On TruthfulQA, decorrelated BP-TD fell below majority vote, although not significantly. Family weighting improved ARC accuracy numerically, but that gain was not significant. BP-TD also did not significantly outperform the correlation-fusion baseline on MMLU.
The unresolved question: whose votes should shrink?
Across 2,852 sub-pools from the four benchmarks, pool composition strongly affected the outcome. On MMLU, family-weighted BP-TD beat majority vote in 98% of random sub-pools whose largest family was not the most accurate. When the largest family was strongest, it lost in most sub-pools. TruthfulQA remained difficult, with losses in most sub-pools of either kind.
The author tested two label-free diagnostics for predicting whether discounting would help. Neither reliably separated beneficial from harmful cases across benchmarks. Agreement alone did not reveal whether agents were jointly right or jointly wrong.
A small supply of known answers changed the practical choice. With 20 labeled questions, selecting a single agent outperformed every tested aggregator on MMLU, ARC and TruthfulQA.
The evidence remains limited to these benchmarks and local open models of up to 14 billion parameters; only MMLU was tested at larger scale. The dependence correction is heuristic, and possible benchmark contamination could affect shared-answer patterns. BP-TD therefore offers a conditional tool for redundant agent pools—not a label-free guarantee of truth.
- AI agents
- truth discovery
- correlated errors
- large language models
- ensemble methods
- BP-TD
- model reliability