TRANSMISSION // 2611.04785v1
A simulated city tests whether AI investigators can separate evidence from suspicion
Source published
KierstonBench evaluates language models using linked records from a synthetic population of about 125,000 people. In an initial, small evaluation, models often handled routine record lookups but failed to identify perpetrators in five staged suspect-identification tasks. Selective abstention reduced wrong accusations, highlighting the difference between retrieving records and drawing justified conclusions.
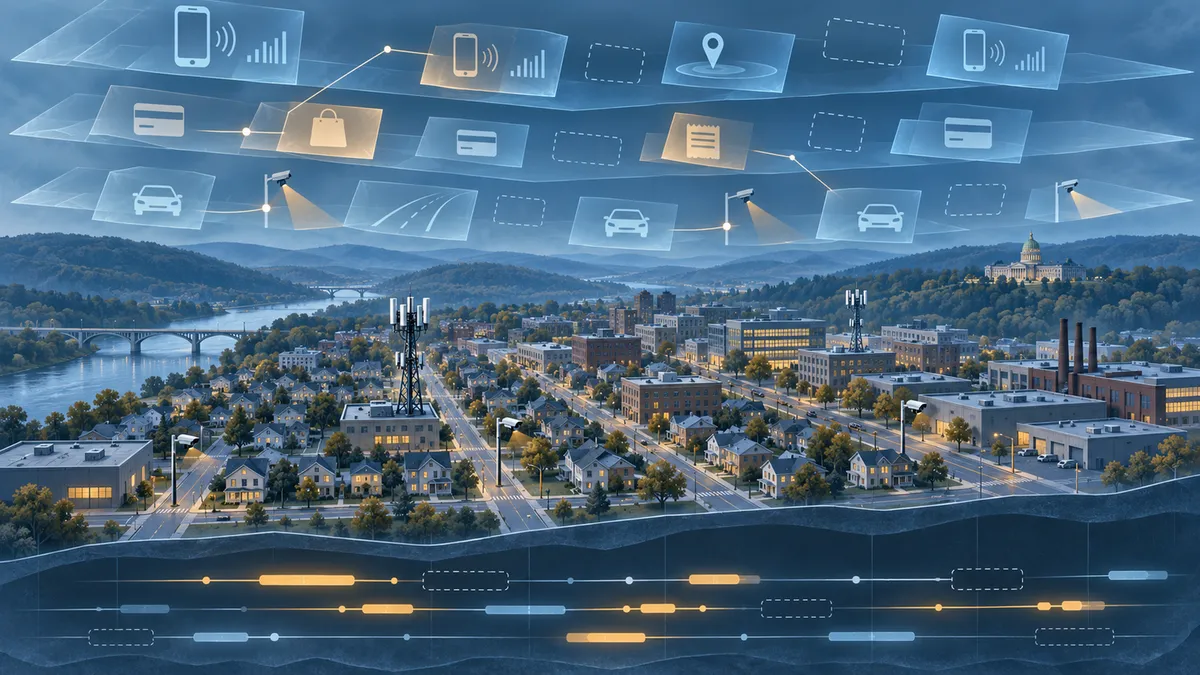
A phone connecting to a nearby cell tower does not prove its owner witnessed a crime. A vehicle registration does not establish who was driving. A new preprint introduces a simulated city where researchers know what actually happened—and can test whether AI systems respect those distinctions.
A city with an answer key
Investigative records offer fragments of events: a bank payment, a license-plate observation, a phone connecting to a cellular network. Connecting those fragments to people is different from establishing what those people did.
In a preprint posted to arXiv on November 3, 2026, Andrew Semenov and Svyatoslav Dorofeev introduce Kierston, a simulation based on Allentown, Pennsylvania, and KierstonBench, a benchmark for language-model investigations. The work is not presented as peer-reviewed research.
Their approach addresses a measurement problem: real investigations rarely provide complete knowledge of everyone’s activities. A simulation can retain that knowledge while exposing only the incomplete records an investigator would receive.
Generating behavior before records
Kierston models approximately 125,000 synthetic residents using public census, geographic and infrastructure inputs. Programmed behavioral rules generate work, school, shopping, social activities and travel. Telecommunications records, payments and camera observations then derive from the same underlying timeline, rather than being invented independently.
This shared origin matters. A journey can produce mutually consistent phone events, purchases and plate reads, while the simulation retains the activity that generated them. Personal identities are synthetic; public maps and infrastructure information provide the setting.
The observations are deliberately imperfect. Plate readers can misread characters, miss vehicles or produce false readings, and confidence values overlap between correct and incorrect observations. Cellular records constrain location without revealing an exact position. A phone can also remain behind while its owner travels elsewhere.
Investigating through restricted access
KierstonBench contains 32 task families: 22 technical tasks, seven real-time investigations and three deception tasks. Questions range from resolving a subscription to its user to reconstructing journeys, identifying incident participants and checking a caller’s account against independent records.
Models receive initial evidence but no candidate list. They query an interface representing 15 separate sources, including carriers, banks, vehicle registers and camera operators. No universal resident identifier connects those sources; models must follow identifiers contained in the records.
The underlying activity histories and incident roles remain hidden. Staged investigations also impose evidence cutoffs, preventing models from using later events. Some instances intentionally retain insufficient evidence, requiring a decision about whether an answer is justified.
Sixteen models were evaluated through the same coding-agent setup, with tools for querying records and writing analysis scripts. Each investigation had a 20-minute allowance.
Correctness is not simply answering more
Scores range from −1 to 1. Correct answers earn credit, incorrect identity claims attract penalties, and abstention receives zero. These are benchmark scores, not percentages of investigative accuracy.
GPT-6 Sol had the highest reported all-task mean, 0.55. Its mean on answered tasks was 0.93, but it explicitly abstained on 13 of the 32 tasks. Claude Fable 5.1 scored 0.52 overall and 0.58 on answered tasks, with two explicit abstentions and one run ending without an answer file.
The distinction is central: a model can improve the quality of its submitted answers by declining uncertain cases, without solving more cases overall.
The starkest finding concerned the five suspect-identification tasks within the real-time group. No evaluated model identified a perpetrator in any of them. Models either abstained, failed to submit an answer, or supplied incorrect identifications. Stronger performance on routine tasks therefore did not translate into successful perpetrator identification in these sampled incidents.
How plausible leads became wrong answers
The authors examined saved queries, scripts and answers to understand failures. In one shooting investigation, a model required a phone event during a narrow incident window. That excluded the perpetrator’s handset, whose last event occurred just before the window.
Other investigations ranked candidates using firearm ownership, criminal records and departures from the area without establishing involvement in the incident. These records supplied reasons for suspicion, but not the missing connection to the crime.
Some models more consistently distinguished presence from participation and withheld identities when records could not separate perpetrators from bystanders. However, abstention was not uniformly well targeted: models also declined some routine questions that others solved.
A limited test with dual uses
Each model attempted only one sampled instance per family, once, on one simulated day. The authors caution that small score differences could change on another attempt. Comparisons also have a staging caveat: nine models received a corrected disappearance scenario, while seven retained results from an earlier version in which an abandoned handset still communicated.
The simulated city has additional simplifications. It lacks weather and holidays, uses one travel mode per person, and does not calibrate messaging volume or call-answer rates against measured data.
The authors acknowledge that the system could support both surveillance development and scrutiny of surveillance claims. They release code and public inputs, but withhold generated outputs and evaluation tasks because synthetic identities may coincide with real people. Their conclusion is that these models may assist investigators, but the reported results do not support replacing them.
- Kierston
- KierstonBench
- language models
- synthetic data
- investigative reasoning
- surveillance
- uncertainty
- AI evaluation