TRANSMISSION // 2611.04479v1
A Geometric Approach to Making Transformer Attention Sparse
Source published
A preprint introduces a cone-based method for removing structured groups of attention connections. The authors report strong classification results at 90% attention sparsity, but performance varies by task, and faster sparsification does not establish equivalent end-to-end inference gains.
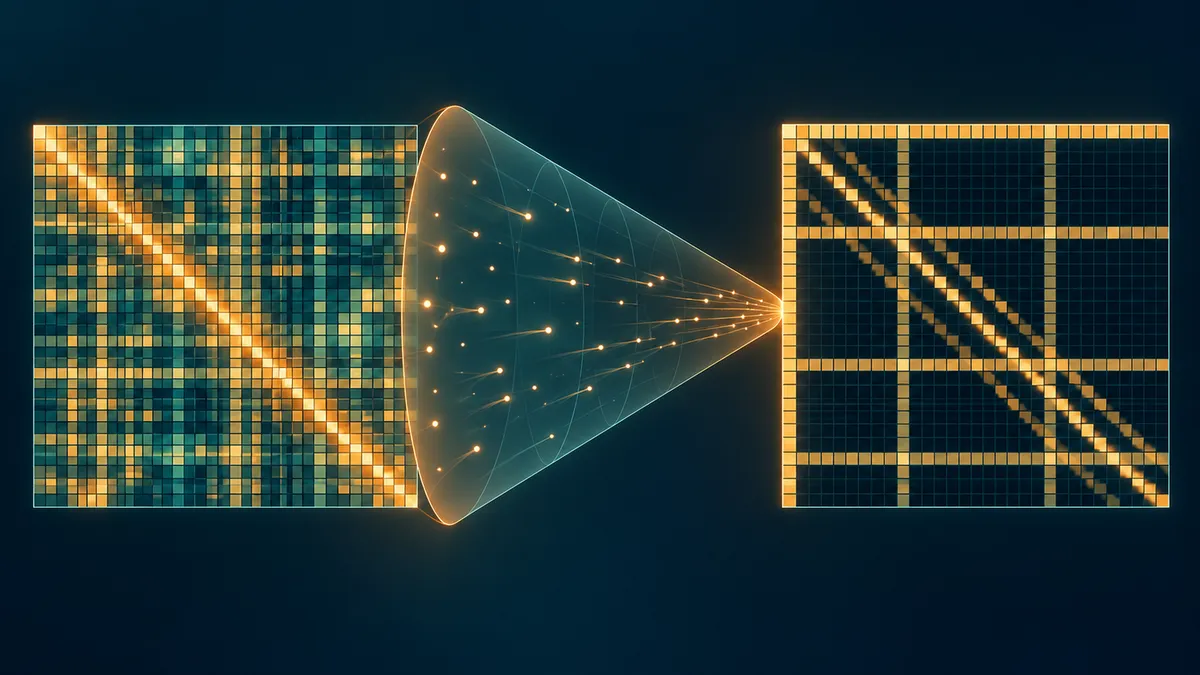
Which attention connections can a Transformer lose without losing useful information? Michel Barlaud and colleagues propose answering that question with geometry: identify groups of connections using a scale-invariant constraint, then reshape their values analytically. Their preprint combines mathematical analysis with language-classification experiments, while leaving important questions about deployment and generalization open.
Why the pattern of zeros matters
Transformer attention represents interactions between tokens in a matrix. As sequences grow, these matrices become expensive to process and store. Sparsification removes some interactions, but scattered zeros do not necessarily translate into efficient computation. Removing organized groups, such as rows, columns or diagonal bands, offers a structure that hardware can more readily exploit.
In their preprint, Michel Barlaud, Clement Genninasca, Maxime Zanella, Benoit Macq and Benoit Legat introduce the Parametric Linear Conic Projection, or PLCP. Their aim is to combine adaptable structured sparsity with an inexpensive mathematical procedure, rather than rely solely on fixed attention patterns or magnitude rankings.
A score for concentration, not an exact zero count
The method starts with the Cone Alignment Index, or CAI. For a nonzero vector, it divides the square of the sum of absolute values by the sum of squared values. Multiplying every entry by the same nonzero factor leaves the score unchanged.
A vector with one nonzero entry scores one. A vector with equally sized nonzero entries scores the number of those entries. More generally, CAI measures how concentrated the values are; it does not directly count zeros.
The authors impose an upper limit, called l, on this score. Smaller limits encourage greater concentration and sparsity, but do not specify an exact percentage of zeros. The final number depends on the input values, so the paper describes calibrating the parameter on validation data.
Geometrically, vectors violating the constraint lie inside a convex cone in the nonnegative region. The acceptable region is outside that interior, including the boundary, and is nonconvex. This distinction matters: exploiting a convex cone's geometry does not make the sparsity-constrained problem itself convex.
Two stages, two related projections
PLCP first identifies the surviving entries, known as the active support. It repeatedly calculates a threshold from the current values and removes entries below it. Once the support stops changing, a closed-form calculation moves the retained values onto the target CAI boundary. Inputs already satisfying the constraint are intended to remain unchanged.
The paper also develops a Euclidean version, PECP, which chooses the nearest point along the corresponding boundary direction. Under the authors' construction, the two procedures share their threshold and support, and their final vectors differ only by a positive scaling factor. PLCP therefore does not generally return the same numerical values as the Euclidean projection.
The authors establish finite termination of support selection, with at most n iterations for an n-entry vector. Each pass is linear in vector size, giving O(Kn) work for K passes. They observe few passes experimentally, but this is not a universal near-linear guarantee: the stated worst-case bound permits quadratic work.
For matrices, the framework first summarizes groups through their norms, applies the vector procedure, and then adjusts those groups. Reshaping allows diagonal attention patterns to be handled through this group-based approach.
What the experiments report
The classification experiments cover SST-2, QNLI, QQP and MNLI from GLUE, plus WiC from SuperGLUE. Sequence lengths are 128 tokens for SST-2 and 256 for QNLI, QQP and MNLI. All compared masks preserve the first attention row and column to retain global interactions.
At 90% attention sparsity, the reported PLCP accuracy exceeds the structured-pruning, GSP and BigBird comparisons on all five tasks. Relative to the baseline without projection, however, the picture varies.
SST-2 rises from 92.7% to 94.56%, and QQP from 88.65% to 89.66%. WiC rises from 69.55% to 75.13%. MNLI falls from 78.9% to 78.20%, while QNLI drops from 88.52% to 82.95%—a loss of 5.57 percentage points. Thus, the headline of 90% sparsity with little accuracy loss does not describe every task equally well.
What remains unproven in practice
The runtime experiments concern the sparsification procedure, including comparisons on an NVIDIA A100 GPU. The authors report runtime comparable to structured pruning and a speed-up over GSP-Hybrid that they fit quadratically with matrix size. These results should not be read as equivalent acceleration of an entire Transformer: computing group norms and processing the remaining matrix still require work.
The BigBird comparison also needs context. The paper evaluates a fixed-mask setup on relatively short sequences and acknowledges that BigBird was designed for larger attention matrices. The results do not establish superiority across long-context workloads.
Overall, this preprint offers a geometric construction and encouraging task-specific evidence, not an established general solution. Broader deployment gains, systematic linguistic effects and extensions to mixture-of-experts models remain questions for further evaluation.
- structured sparsity
- Transformer attention
- Parametric Linear Conic Projection
- Cone Alignment Index
- sparse attention
- geometric optimization
- GLUE
- SuperGLUE