TRANSMISSION // 2611.04473v1
AI Can Fix a Simulated System Without Finding What Broke It
Source published
A preprint studying seven language models in synthetic gene networks reports a consistent gap between restoring healthy outputs and identifying the underlying fault. Follow-up tests suggest that models often encounter useful evidence but struggle to work out what competing explanations predict. The results concern controlled simulations, not real biological discovery or clinical diagnosis.
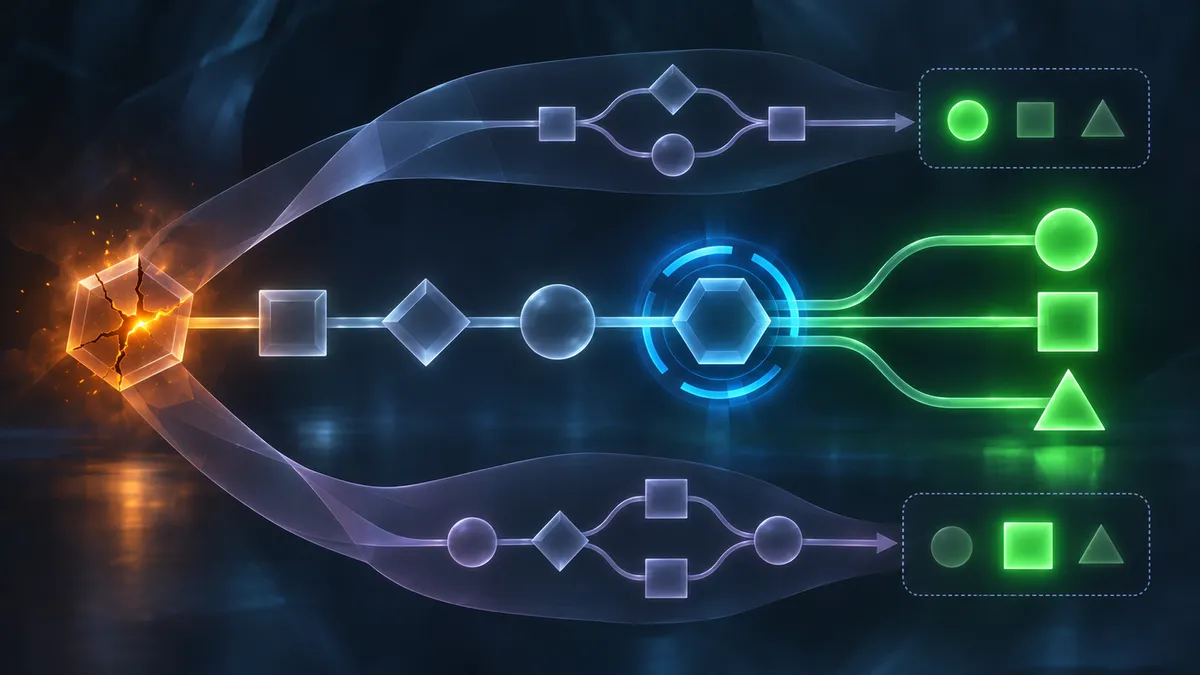
Making a malfunctioning system behave normally is not the same as understanding its malfunction. A study by Anna Gogleva, Thomas Charman, Martin Balla and Karl Gemayel examines that distinction in AI agents—and finds that successful interventions can conceal weak causal reasoning.
An intervention can compensate for a fault without revealing where it began. In a regulatory network, changing a component downstream of the original problem may restore normal outputs while leaving the underlying malfunction untouched. That distinction anchors this preprint, which has not been peer reviewed: does an AI agent understand the cause, or has it merely found something that works?
The researchers tested seven language models in LUCA, a simulated experimental environment. Each synthetic organism contained 20 genes, three external signals and three observable outputs, called phenotypes. One hidden fault disrupted the system: a gene locked at high or low activity, or a signal permanently switched on. All names were invented, preventing agents from simply retrieving knowledge about familiar biological pathways.
Agents could alter gene activity, activate signals and observe the results. Each session allowed 31 experiments, enough to test every gene once with some room remaining. Agents had to commit to a diagnosis before testing a rescue, so rescue results could not subsequently change their diagnosis. The researchers, unlike the agents, knew the underlying network and could simulate how alternative faults would respond.
Across all seven models, average rescue scores exceeded diagnosis scores. On 20 medium-difficulty systems, Claude Opus 4.6 and Sonnet 4.6 restored all abnormal outputs to their healthy ranges. Their average diagnosis scores were 0.55 and 0.35, respectively. Importantly, those headline diagnosis scores awarded half credit for identifying the right component but the wrong fault type; they are not simply percentages of fully correct diagnoses. Later analyses required an exact match. Estimates were also uncertain: rescue and diagnosis confidence intervals overlapped for the weakest-performing models.
The authors then examined 420 sessions across 60 organisms to investigate the gap. Although models that explored more tended to perform better overall, additional experimentation within a given model was not associated with better diagnosis. That observational result argues against a simple shortage-of-experiments explanation; it does not establish that extra, carefully chosen experiments could never help.
Was the task sometimes impossible? Yes. Seven organisms had an alternative fault that the available interventions could not distinguish from the true fault. But 14 had no competing explanation matching the initial abnormal outputs, and another 39 had alternatives that experiments could resolve. Under the study’s criteria, the cause was therefore identifiable in 53 of 60 organisms.
The more revealing result concerned evidence already collected. Among organisms with at least one distinguishable alternative, 91% of committed sessions included an experiment capable of separating the true fault from an alternative before diagnosis. Exact diagnosis accuracy in those sessions was only 30%. Encountering such a result did not necessarily eliminate every competing explanation, but it showed that agents often possessed useful causal evidence without reaching the right conclusion.
To investigate further, the researchers replayed experimental records while varying the help supplied. With two candidate faults and their predicted outcomes provided, models generally interpreted decisive observations correctly and revised contradicted hypotheses. They also performed well at finding informative observations inside full experimental logs when the candidate predictions were supplied: accuracy ranged from 88% to 100%.
When those predictions were withheld, leaving models to infer what each candidate fault implied, accuracy fell to 51–74%. This supports the authors’ interpretation that constructing predictions from competing explanations is a major difficulty, rather than simply locating an observation in a record. The comparison is not a perfectly isolated test of that ability, however: the predictions-supplied condition also explicitly reminded models about simulation noise.
Models also struggled when observations could not meaningfully distinguish the candidates. They often selected the numerically closer prediction instead of acknowledging that the difference was too small relative to noise. Another association stood out: exact diagnosis accuracy was 71% when agents tested the true cause in both directions, versus 4% when they tested it in only one. That does not prove bidirectional testing caused success; agents already pursuing the correct explanation might test it more systematically.
These findings have clear boundaries. The organisms were invented abstractions, not representations of real species, and each model–organism pairing had only one sampled live run. Replay records came almost entirely from one model, although a second record source reproduced the main prediction-support pattern. The study does not establish failure rates in real biology or deployed systems. Its narrower lesson is that successful intervention alone is an inadequate measure of causal understanding: evaluation must also examine how agents connect experiments, alternative explanations and conclusions.
- artificial intelligence
- scientific reasoning
- causal inference
- language models
- synthetic gene networks
- experimental design
- AI evaluation