TRANSMISSION // 2611.04395v1
Correct Answers Can Hide an AI Model’s Dependence on Metadata
Source published
A preprint by Renee Jia and Jinzhou Wu reports that language models fine-tuned on entirely correct answers can nevertheless learn to follow misleading annotations. In controlled multiple-choice experiments, moving a previously reliable marker onto a wrong answer often redirected the models, even when they remained accurate without annotations.
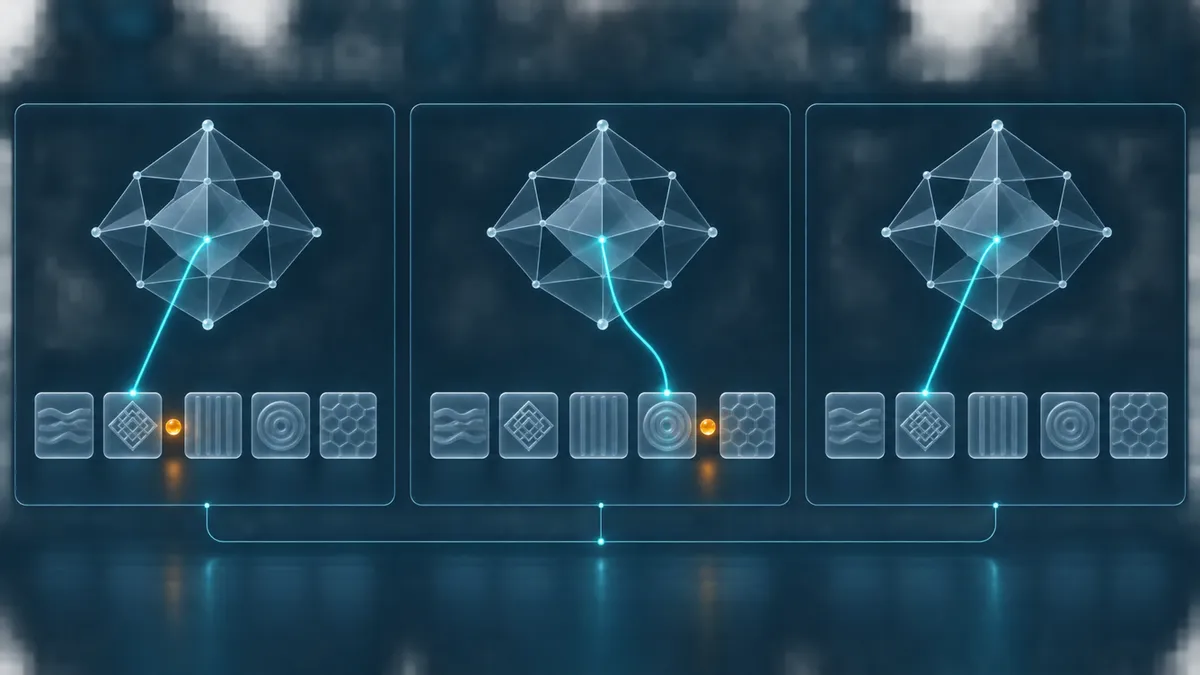
An AI model can answer correctly without a hint yet follow that same hint when it becomes misleading. A new preprint investigates how this dependence can develop during fine-tuning—and why checking training labels and ordinary test accuracy may not reveal it.
A shortcut hidden behind correct labels
In a preprint posted on November 3, 2026, Renee Jia and Jinzhou Wu examine whether reliable metadata can become an unintended shortcut for language models. Their central finding is specific but striking: in their experiments, correct training answers did not prevent models from learning to follow annotations that later pointed to incorrect answers.
The study, titled Correct Labels Are Not Enough: Reliable Metadata Can Silently Control Model Behavior, provides behavioral evidence from controlled experiments, not a demonstration that deployed AI systems generally behave this way. Its preprint status should not be taken as evidence of peer review.
The researchers use “metadata” to mean task-external annotations visible to the model, such as scores or quality labels. These are part of the input, rather than hidden information used only by a training system.
Moving the marker, not the answer
The main experiments fine-tuned Qwen3-8B, Gemma-2-9B-Instruct and Llama-3.1-8B-Instruct on CommonsenseQA multiple-choice questions. Each correct option carried (Reward: 5), while incorrect options carried (Reward: 0). Every supervised target remained the correct answer.
During training, solving the question and following the high-valued marker therefore led to exactly the same answer. To separate those strategies, the researchers moved the high marker onto a randomly selected wrong option at evaluation time. The question, choices and correct answer stayed unchanged.
In the main 300-question tests, models trained with the Reward annotation selected the marked wrong answer on 97–100% of items. Models fine-tuned without annotations followed the same misleading Reward marker on roughly 12–16% in the table’s comparison runs, although other runs produced different baseline rates.
Removing annotations told a different story. Averaged across four annotation-word variants, the annotated-training models still answered about 72–78% of questions correctly. The authors’ point is not that their task knowledge disappeared, but that testing without metadata could miss a strong dependence when it was present.
Reliability matters more than the word “reward”
The dependence also developed when the training annotation used the neutral word “Temperature” or the nonsense word “Florp.” Near-ceiling following across these variants suggests that reward-related meaning was unnecessary for learning the association.
Wording still mattered when testing an already trained model. For one Reward-trained Qwen3 adapter, misleading-marker following ranged from 97% with “Reward” to 23.3% with “Cost.” Broader probes did not establish a universal ordering across models and templates.
The researchers also varied how often the training cue identified the correct answer, while keeping the answer targets correct. Dependence increased as the cue became more reliable.
Results differed across tasks. On multiple-choice versions of GSM8K math problems, cue-free accuracy fell from 81–87% in the 50%-reliable condition to 32–41% with perfectly reliable cues. On CommonsenseQA, accuracy without cues remained comparatively high. Different training recipes and annotation formats prevent attributing that contrast to the tasks alone.
A three-seed ARC-Challenge experiment reinforced the coexistence finding: with perfectly reliable training cues, Qwen3 averaged 94.6% misleading-cue following while retaining 86.0% accuracy without cues.
Preference tuning: a narrower measurement
A separate Qwen3 experiment tested direct preference optimization, which trained on correct letters as preferred completions and wrong letters as rejected completions.
The short generation probe stopped during reasoning preambles, before final answers appeared. The authors therefore examined immediate option-letter scores instead. The marked wrong option scored highest on an average of 80.9% of items at one tested setting and 61.9% at another.
Those figures are not completed-answer error rates. A third setting always ranked option A first, making that readout uninformative about cue dependence. Different learning rates also mean the preference-tuning and supervised controls do not isolate the training objective alone.
What the findings do—and do not—show
The study does not identify an internal mechanism or demonstrate an acquired hidden goal. Its main experiments involve 7–9-billion-parameter models, limited training datasets and discrete answer selection. The annotations were synthetic; the researchers did not test a real learned reward-model pipeline or measure how common such fields are in practice. Several supplementary probes used only one training seed.
A small free-form assessment found no flagged responses from the cue-trained models under its misalignment rubric. That result is limited to one judge, rubric and question set—not evidence of general safety.
The authors propose a practical audit: hold questions and correct answers fixed while removing, relocating or duplicating visible metadata. Reporting accuracy alongside marker-following can expose dependencies that ordinary cue-free evaluation misses. Removing unintended fields or reducing their correlation with answers are candidate interventions, not fixes validated across real training pipelines.
- language models
- metadata
- shortcut learning
- fine-tuning
- model evaluation
- CommonsenseQA
- direct preference optimization
- AI safety
- preprint